Tag: playbook

  • WordPress Plugin Conflicts: The Playbook, Step By Step

    WordPress Plugin Conflicts: The Playbook, Step By Step

    Your site shows a white page, or the message “There has been a critical error on this website.”

    You updated one plugin an hour ago, and you have a lot of plugins installed.

    Short answer: A plugin list cannot prove a WordPress plugin conflict. Only errors, logs and a clean test can. What a plugin list can do is show you which plugins do the same job, which ones are switched off but still installed, and where to test first. That is the whole job of the Plugin Conflict & Redundancy Check playbook, and this post walks through its two steps.

    What this post is, and is not: A method write-up of one read-only playbook, based on its two step files as shown in the Protuno dashboard on 16 October 2026. It is not a result from a real run: no playbook was run for this post, and every picture and plugin name in it is an illustration with example values. It is not a conflict detector, and it does not read error logs.

    What A Plugin Conflict Looks Like When It Shows Up

    A conflict rarely announces itself with the names of the plugins involved.

    It shows up as a symptom. A page that stops loading. A checkout button that does nothing. A spinner in the editor that never finishes. In the worst case, the critical error message, or the white screen.

    WordPress’s own training material describes where these come from. The Learn WordPress lesson on plugin and theme conflicts lists the most common causes of a white screen or critical error as an exhausted memory limit, PHP errors, database issues, and plugin or theme conflicts or compatibility issues. Within conflicts, it names code incompatibility with the current WordPress version, JavaScript errors that stop a page loading, and deprecated functions.

    So a conflict is one of four possible causes, and the symptom does not say which. That matters for everything that follows. If you are staring at a broken page right now, read the white screen of death post first, because it covers the playbook for exactly that moment.

    This post is for the quieter situation. The site works. You want to know where trouble is most likely to start.
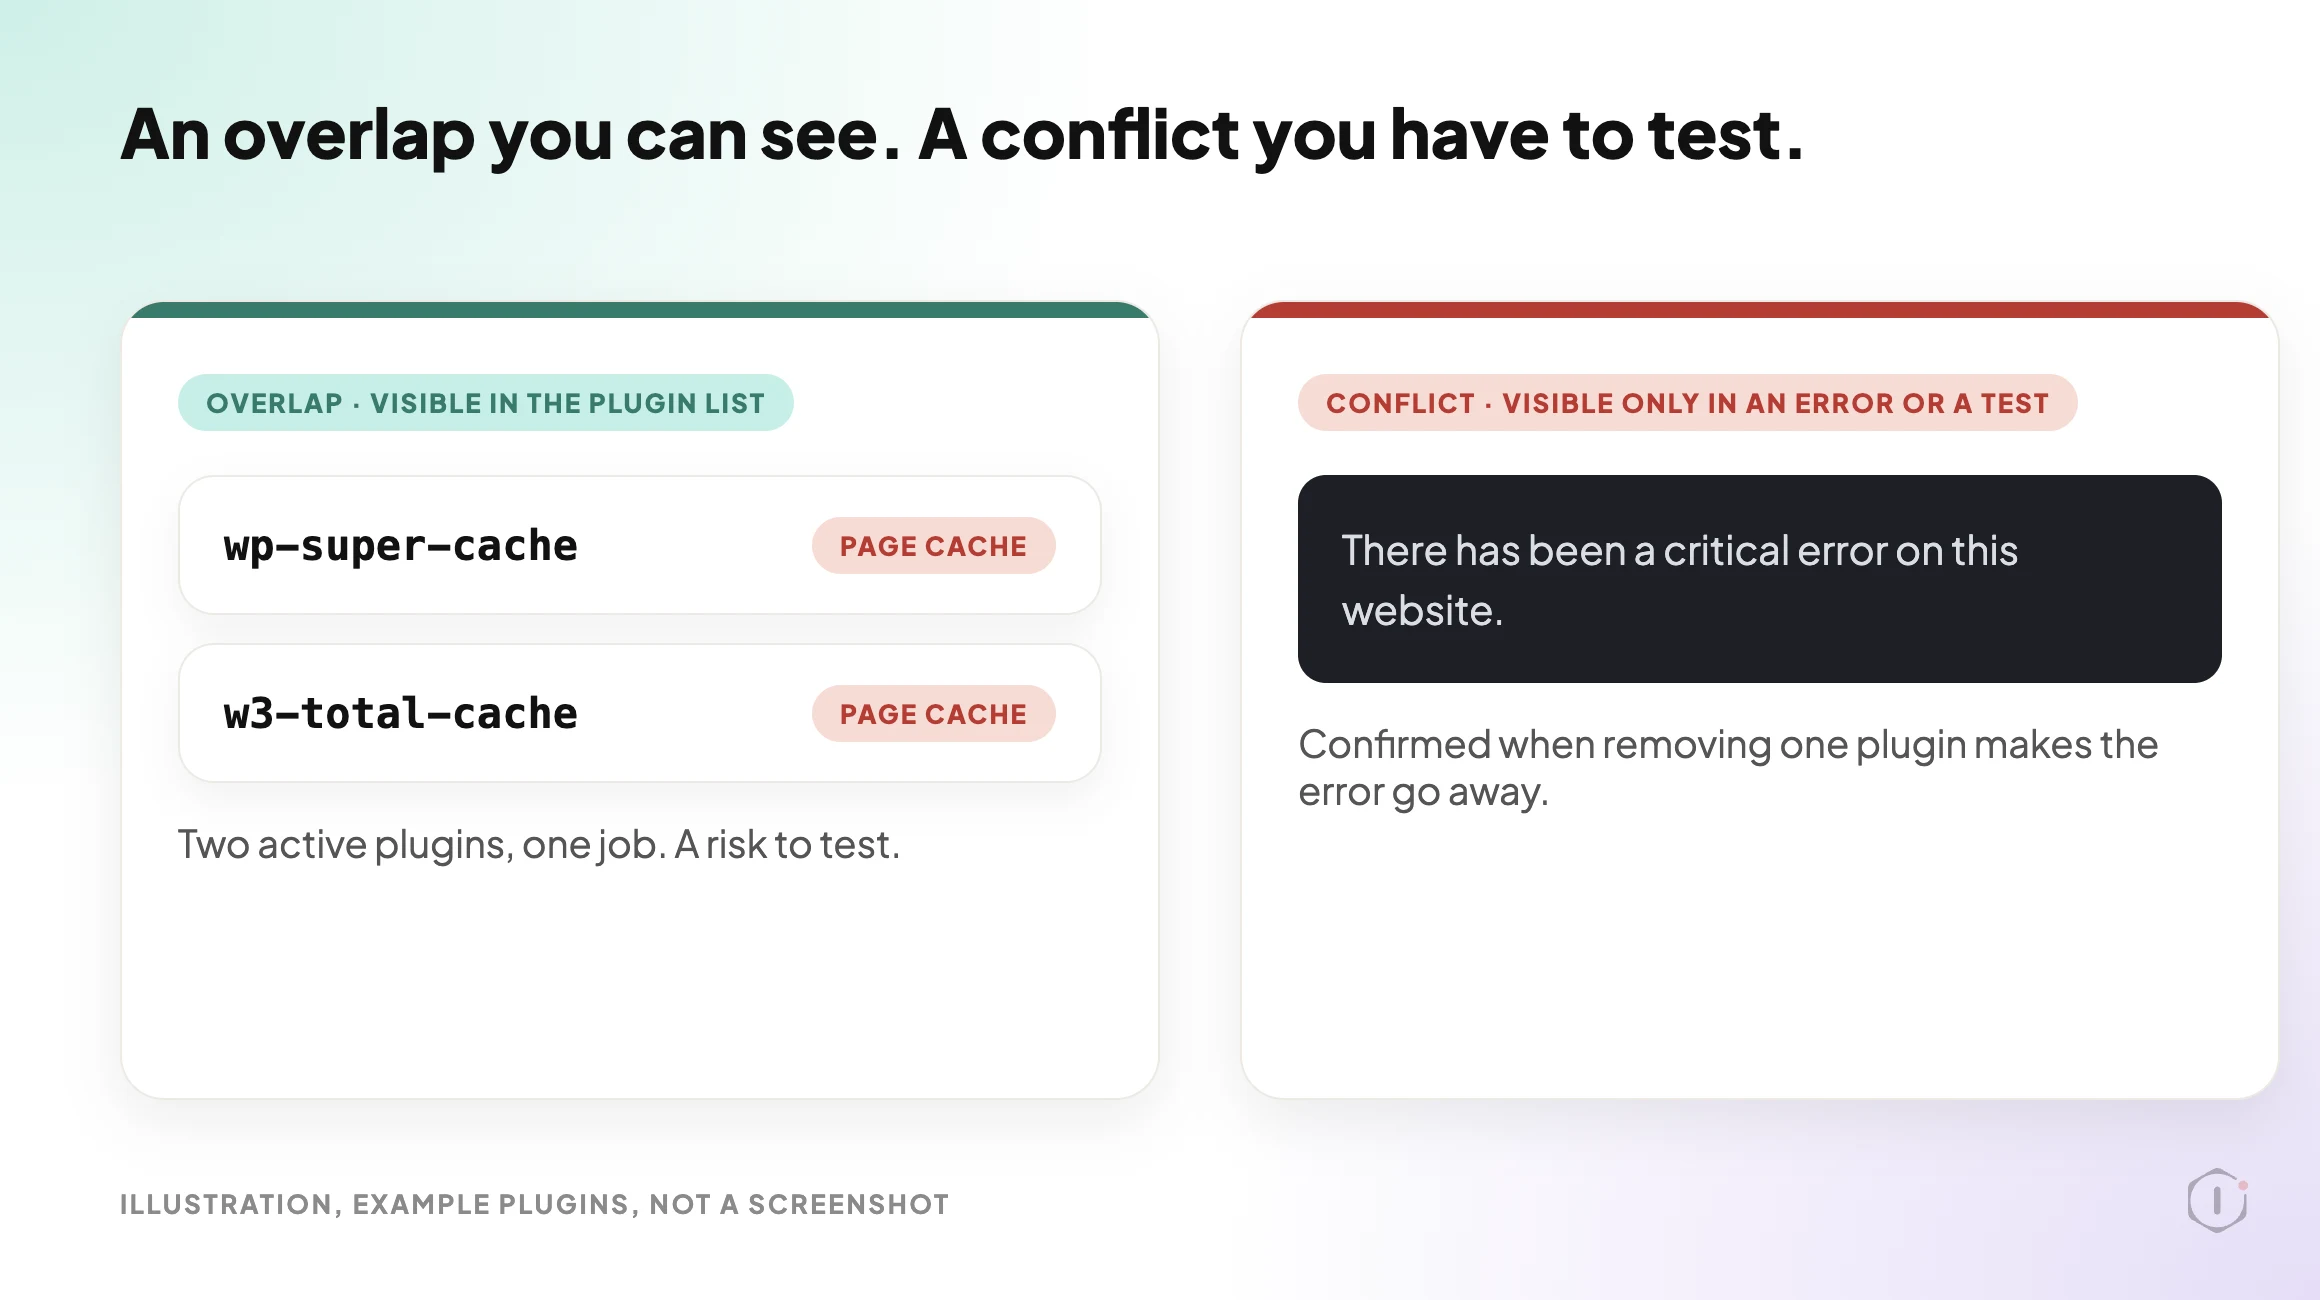
    Illustration comparing an overlap, two active page cache plugins visible in the plugin list, with a conflict, a critical error message that only an error or a test can confirm
    Two plugins on one job is a risk to test, not a proven conflict. Example plugins, not a real run.

    Overlap Is Not The Same As Conflict

    Two words get used as if they meant one thing. They do not.

    An overlap is two active plugins doing the same job. Two page cache plugins. Two SEO suites. Two backup plugins on separate schedules. You can see an overlap from the plugin list alone.

    A conflict is two pieces of code interfering with each other so that something breaks. You can only see a conflict from an error, a log, or a test that fails and then passes when one plugin is removed.

    Overlap is a sensible place to look first, because two plugins doing the same job can end up competing for the same files and settings. But it is only a place to look. Plugin A and plugin B can have nothing in common and still collide, and two plugins in the same job can sit side by side for years without a problem.

    The playbook is built around that gap. It reports overlaps and does not call them conflicts. The step instructions say so directly: say “overlap” or “risk”, never “broken” or “conflicting” as a fact, because the check reads the plugin list, not errors.

    That restraint is what makes the report usable. A report that cried “conflict” about every pair of plugins would train you to ignore it.

    The Playbook, Step By Step

    In the Protuno dashboard the playbook is called Plugin Conflict & Redundancy Check. It carries the Beta label, it has two steps, and it only reads. The public playbooks page lists it under Care with the same name and the same two steps, and says it needs no connector and sets no schedule: it runs when you start it.

    Both steps show Automatic backup as None and Approval checkpoint as Off in the dashboard. No step pauses to ask you anything.

    A short silent video walks through the same two steps.

    Silent video, illustration with example plugins, not a real run.

    Step 1: Plugin Inventory And Classification

    The first step reads the site’s plugin list twice: once for active plugins and once for inactive ones. Every call is a read. No plugin is activated, deactivated, updated, deleted or configured.

    Each plugin is then sorted into one job from a fixed table, by exact slug. The slug is the part of the plugin path before the first slash, so wordpress-seo/wp-seo becomes wordpress-seo.

    Three rules in this step are worth knowing before you read any report.

    • The table is closed. A plugin whose slug is not in the table is marked unclassified. The step is told never to infer a job from a plugin’s name or description.
    • Protuno’s own plugins are left out. The three connection plugins are listed as “Protuno connection” and are never classified or flagged.
    • The counts must add up. Classified plus unclassified plus Protuno connection must equal active plus inactive, and the step checks the sum before it answers.

    There is also a size limit. The reply from the plugin list is cut at 8,000 characters, which the step instructions estimate at about 75 plugins per status. If a list is cut, the step uses the complete items it has and records the inventory as partial. It never guesses the missing ones.

    The Fixed Table Of Jobs

    The table has thirteen jobs. Ten of them can produce an overlap finding, and each carries a severity.

    JobSeverity when two or more are active
    Page cacheHigh
    Security and firewallHigh
    SMTP and mailHigh
    SEO suiteMedium
    Asset optimisationMedium
    BackupMedium
    Image optimisationMedium
    Page builderMedium
    RedirectsLow
    Anti-spamLow

    Three more jobs are handled differently. Elementor add-on packs count as stacking when three or more are active, and that is rated low. Forms and analytics plugins are listed for information only, because several of each on one site is often normal.
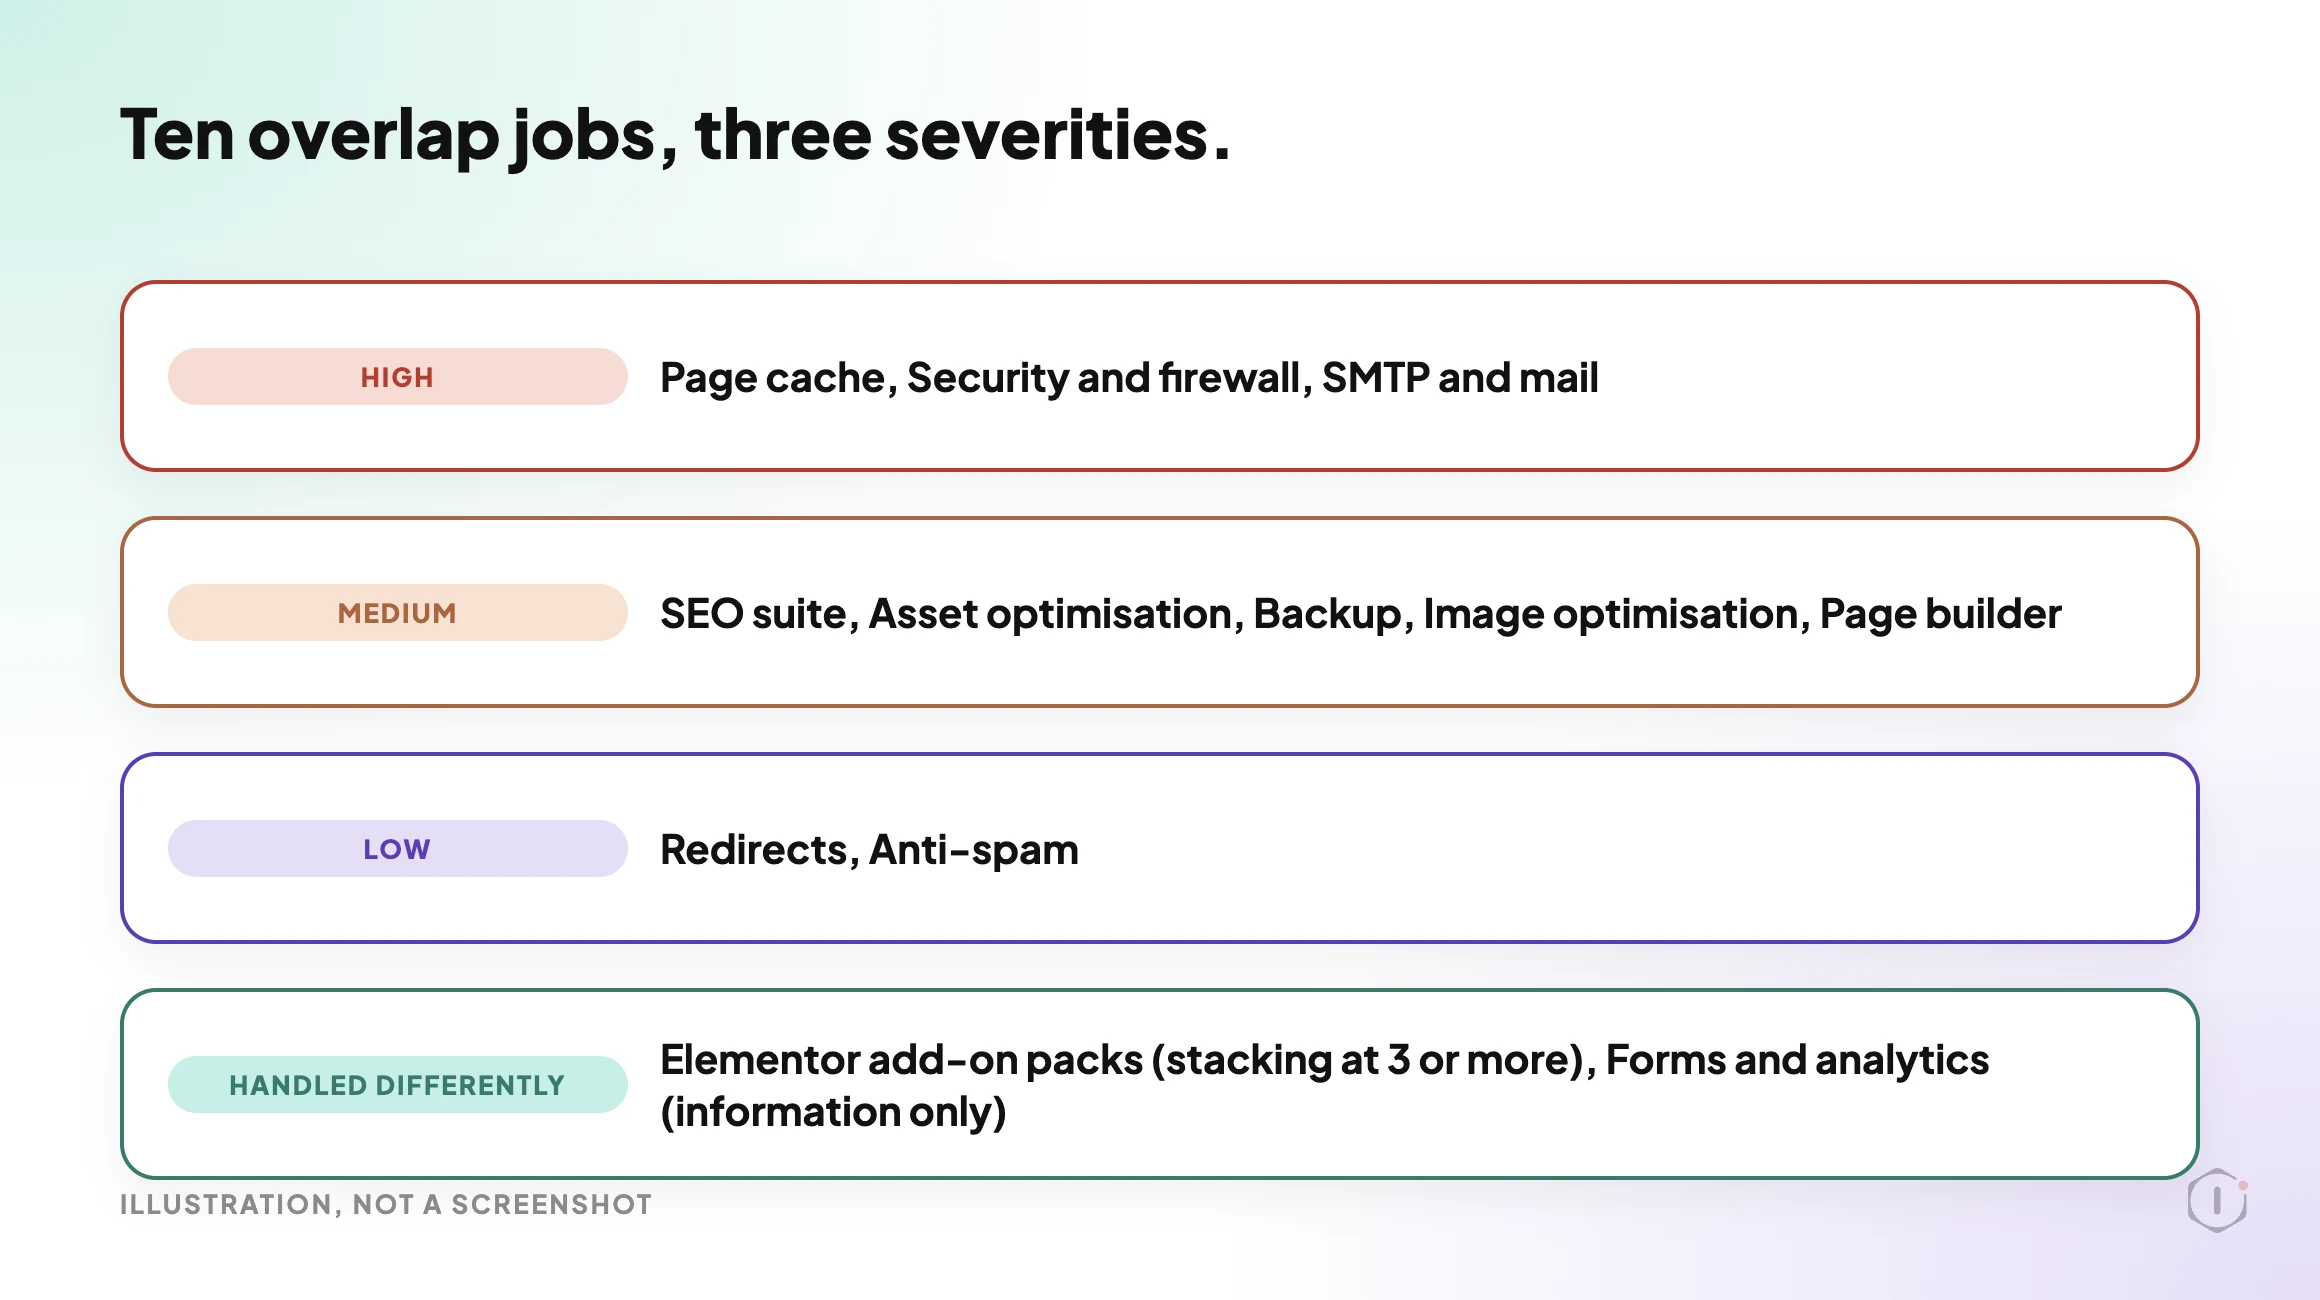
    Illustration of the ten overlap jobs grouped into high, medium and low severity, plus the stacking and information-only jobs
    The ten overlap jobs by severity, and the two that are handled differently. Illustration, not a screenshot.

    Step 2: Overlap And Conflict Report

    The second step makes no calls at all. It composes a report from the inventory, and if the inventory is missing or the first step failed, it stops with a broken-chain message rather than inventing one.

    It applies four findings and nothing else.

    1. Overlap. Two or more active plugins in the same job, rated by that job’s severity.
    2. Several installed. Two or more active forms or analytics plugins, listed under “For information” and not treated as a risk.
    3. Add-on stacking. Three or more active Elementor add-on packs, rated low, because of overlapping widgets and extra assets on every page.
    4. Inactive plugin. Every inactive plugin except Protuno’s own, rated low.

    Inactive plugins never count toward an overlap. The reason they still show up is different. Inactive code is still on disk, and the step’s own wording is that it can still be attacked. If a plugin is not needed, delete it from the Plugins screen. The same wording adds that deleting cannot be undone, so keep the zip or a backup.

    Why Each Overlap Matters

    For every job, the step has a fixed reason, so the report explains itself instead of only listing names.

    • Page cache: both try to own the cache and the advanced-cache.php file, so pages can go stale or break after an update.
    • Security and firewall: double login blocking and lockouts, and rules that can block each other.
    • SMTP and mail: both rewrite how mail is sent, and one can silently override the other. A separate post covers email deliverability.
    • SEO suite: duplicate titles, meta tags, sitemaps and schema.
    • Asset and image optimisation: double processing of the same files.
    • Backup: two schedules, double load and storage, and no clear answer on which one restores.
    • Page builder: two editors loading their assets.
    • Redirects and anti-spam: rules evaluated twice, which makes it harder to tell which one acted.

    Each finding names the plugins, gives the reason, and offers one safe next step: on staging, keep one, deactivate the other, then check the front end, forms and checkout.

    What The Report Looks Like

    The report has a fixed layout, so two reports from two sites can be read the same way.

    • Plugins read: the active and inactive counts, and whether the inventory is complete or partial.
    • Summary: overlaps by severity, inactive plugins, and unclassified plugins that were not assessed.
    • Overlaps: a table of severity, job, active plugins, why it matters, and the first step.
    • Add-on stacking, Inactive plugins and For information: each its own short section, or “none”.
    • Not checked: real runtime errors and hooks, each plugin’s own settings, must-use plugins, and every unclassified plugin.
    • Note: a line confirming it was a read-only check and nothing was changed.

    “No overlaps found” counts as a pass.

    A Five-Minute Version You Can Do By Hand

    You do not need a playbook to get the first half of this value. Open the Plugins screen and do this.

    1. Sort the installed plugins in your head into jobs: cache, security, SEO, backup, mail, images, redirects, spam, page builder.
    2. Write down any job that has two active plugins.
    3. Write down every inactive plugin and ask whether anyone needs it.
    4. Mark the overlaps by how much damage they could do. A doubled page cache or a doubled firewall is worse than a doubled redirect plugin.
    5. Pick one overlap. Test it on staging, not on the live site.

    If you test on staging, the staging drift post is about what drifts between staging and live, which matters before you trust a test result.

    The playbook applies the same table to every site you point it at, which is the real gain on a client portfolio. On a single site you own, the manual version is fine.

    What An Overlap Check Does Not Solve

    An overlap report is useful because it is narrow. Here is what it will not do.

    • It does not find conflicts between unrelated plugins. Plugins in different jobs can still collide, and the check cannot see it.
    • It does not read error logs. Logs are where a real error would show. A related post covers the debug log exposed check.
    • It does not judge plugins that are not in its table. They are listed as not assessed, and a re-run gives the same result, because the table is fixed.
    • It does not read plugin settings. Two caching plugins with caching switched off in one of them would still be reported as an overlap.
    • It does not see must-use plugins. The report says so under “Not checked”.
    • It does not fix anything. Fixing an overlap is the site owner’s decision, made on staging first.

    That last point is also a safety property. A tool that only reads and reports cannot break a site.

    If You Already Have A Real Conflict

    Then you need a test, not a report.

    WordPress has a supported way to run one. The Health Check and Troubleshooting plugin on WordPress.org describes a troubleshooting mode: a clean session where all plugins are disabled and a default theme is used, but only for your own user until you turn it off or log out. Everyone else keeps seeing the normal site. That is a safer way to answer the question “is it a plugin?” on a live site, because it does not change what the public sees.

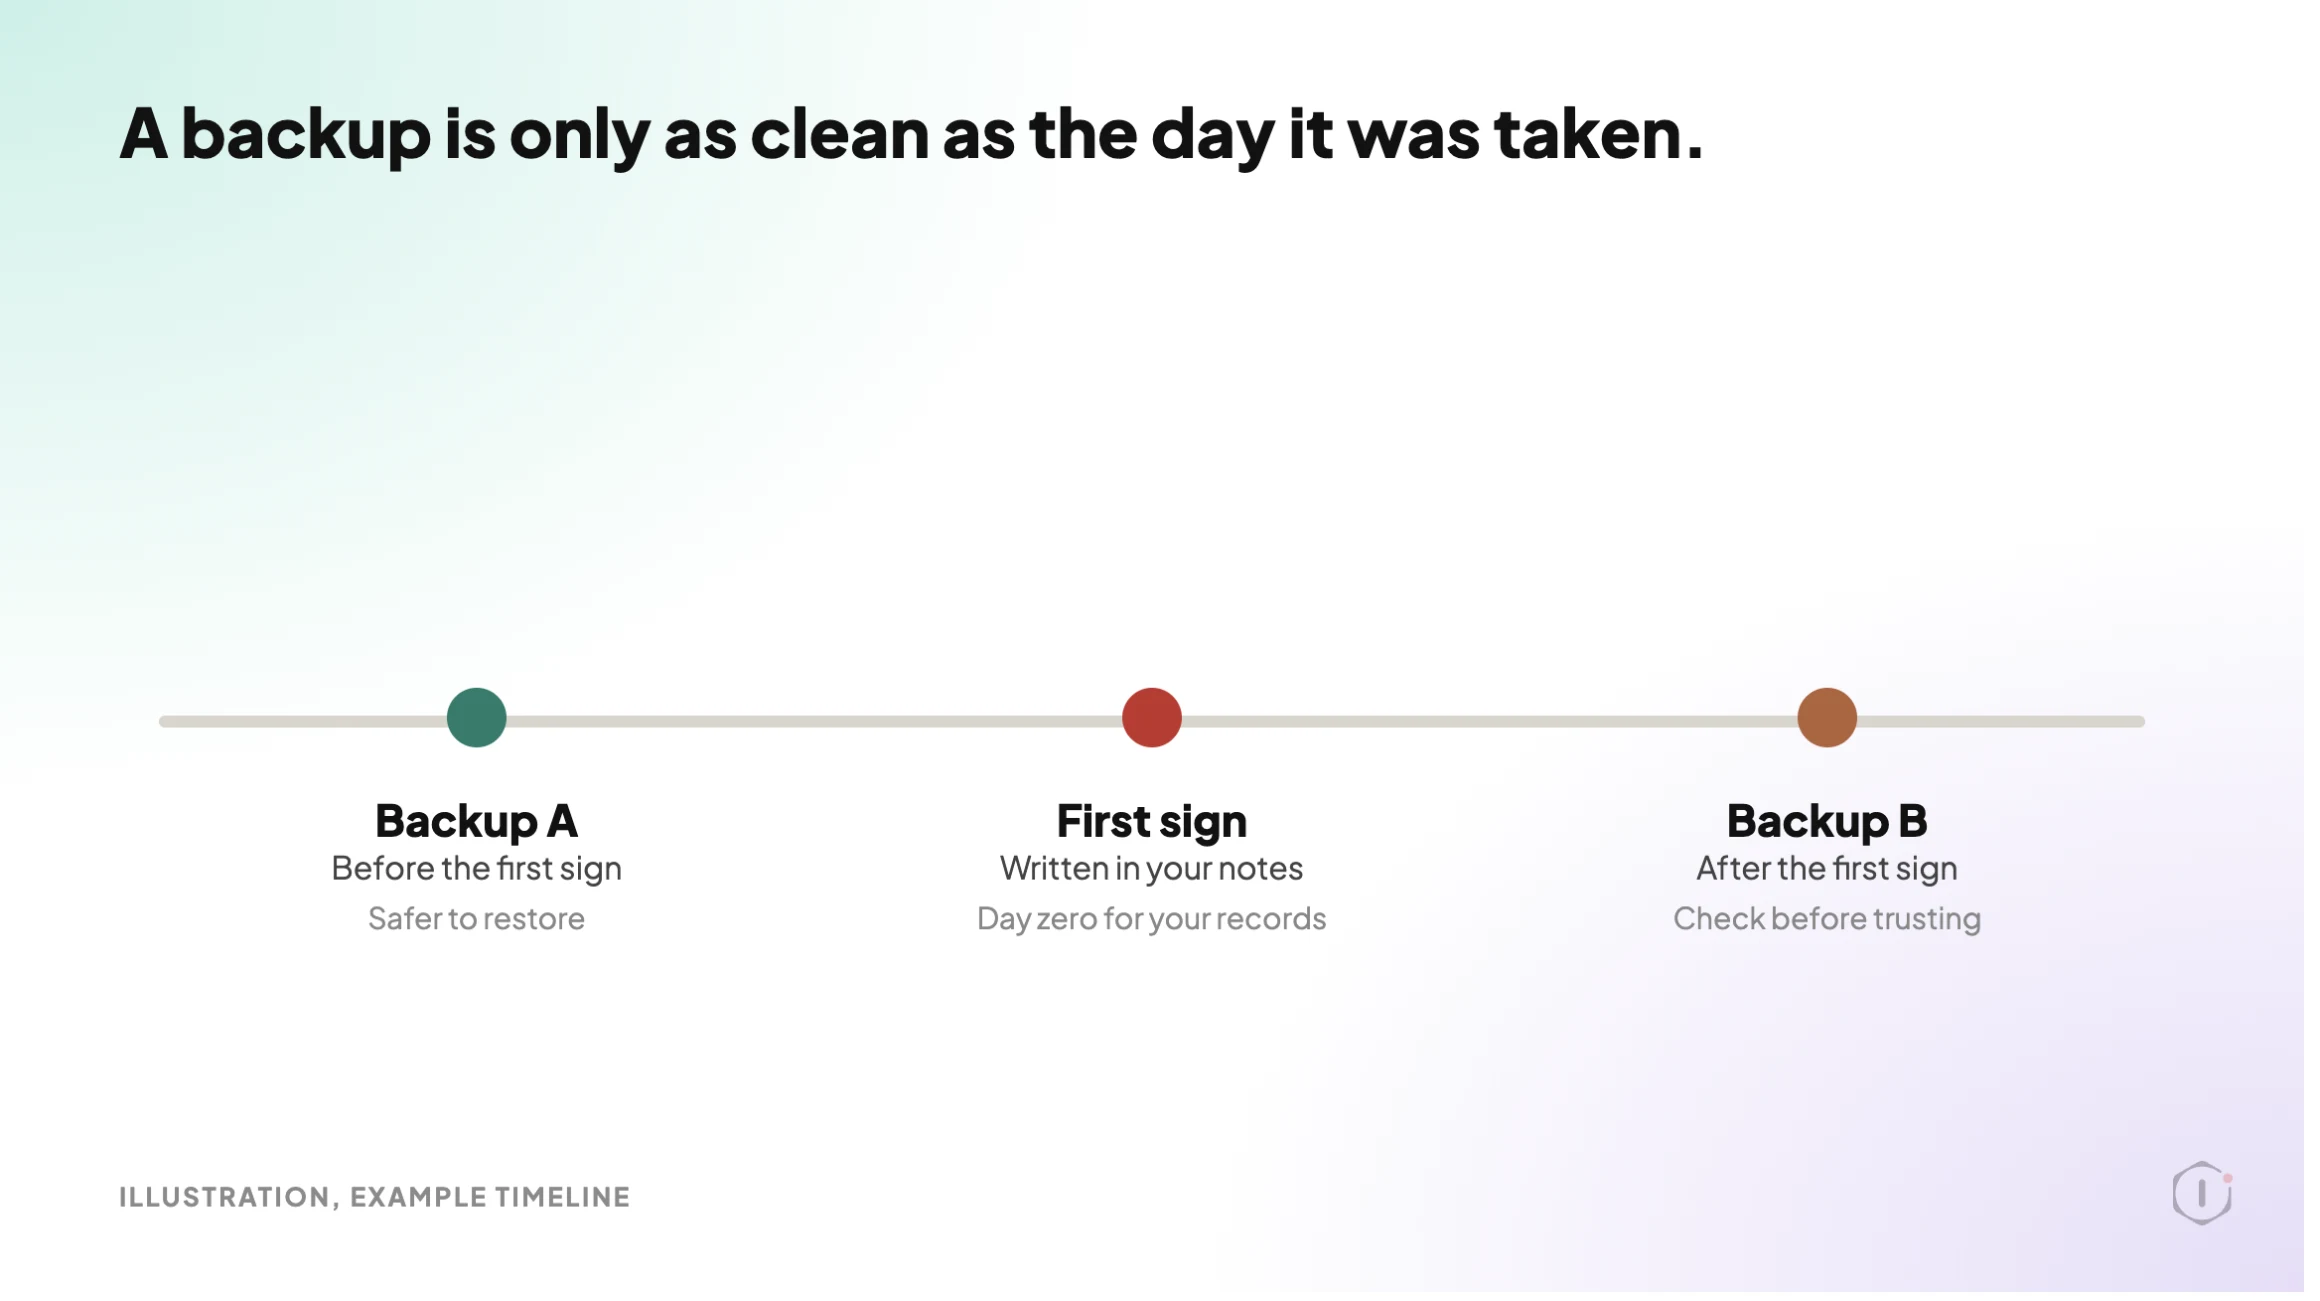
    The Learn WordPress lesson also starts the same way every careful guide does. Make a backup before changing anything, and use a staging site if you have one. If the broken thing is an update you just ran, the update process playbook post is a related read.

    When the cause is a plugin that has stopped receiving updates, the story is different: the premium plugin licenses post and the removed plugin risk post cover two ways a plugin can drift out of support without anything visibly breaking.

    Two Outside Views

    A tutorial and a forum thread. Neither is an endorsement, and neither describes the Protuno playbook.

    In a March 2026 video, Ephraim Creations works through a site that kept crashing and shows the manual route most people take. He switches every plugin off at once by renaming the plugins folder in the host’s file manager, confirms the dashboard loads, renames the folder back so the plugins return in a deactivated state, and then turns them on one at a time until the site breaks again. The video ends with a plug for his own WordPress course.

    On Reddit, an r/Wordpress thread titled “How do you figure out which plugin is causing a conflict when your site breaks?” starts with someone describing the manual method and what it costs:

    u201cThe only way I could figure out to diagnose it was the classic “deactivate all plugins, reactivate one at a time, keep reloading the broken page.”u201d

    Original poster, r/Wordpress, 16 April 2026

    An early reply pushes back on that approach:

    u201cWP_DEBUG, DevTools, server logs. Randomly deactivating plugins and hoping something happens is not how you troubleshoot issues.u201d

    Reply in the same thread, r/Wordpress, 16 April 2026

    The original poster answers that logs gave only generic JavaScript failures with no stack trace pointing at a plugin, and that bisecting never isolates the case where two plugins only break when both are active. That is exactly the situation where a list of overlaps gives you somewhere to start.

    Where Protuno Fits

    The Plugin Conflict & Redundancy Check playbook is the narrow, repeatable part of this problem. It sorts the plugin list into jobs, reports the overlaps, the stacked add-ons and the inactive plugins, and says what to test first on staging. It only reads.

    It sits beside the other checks. A related post on the vulnerability scanner is about installed plugins and known problems, which is a different question from whether two of them overlap. The playbooks page lists the playbooks as Protuno publishes them, and this one has its own page at Plugin Conflict & Redundancy Check.

    The Point

    A plugin list cannot prove a conflict. It can tell you where to look first.

    Read the overlaps by severity, test one on staging, and treat a quiet report as a good result. The next time a site shows that critical error, you will already know which pairs of plugins were worth suspecting.

    Which job has two active plugins on the site you manage right now?

    Sources And Further Reading

  • Find And Replace In WordPress: The Playbook, Step By Step

    Find And Replace In WordPress: The Playbook, Step By Step

    Your company changed its name. Your site did not hear about it.

    The old name is in a hundred places: titles, excerpts, old announcements, a footer line you wrote years ago. Finding them is easy. Changing them safely is where the trouble starts.

    Short answer: a find and replace is safe when it only touches plain text, shows you every change as before and after, and refuses to touch anything it cannot read in full. A phrase can also sit inside a link, a block setting or a shortcode, and changing it there can break the thing it belongs to. Protuno’s Find & Replace Text playbook works in two steps: one read-only step that plans, then one write step that waits for your approval and reads every change back.

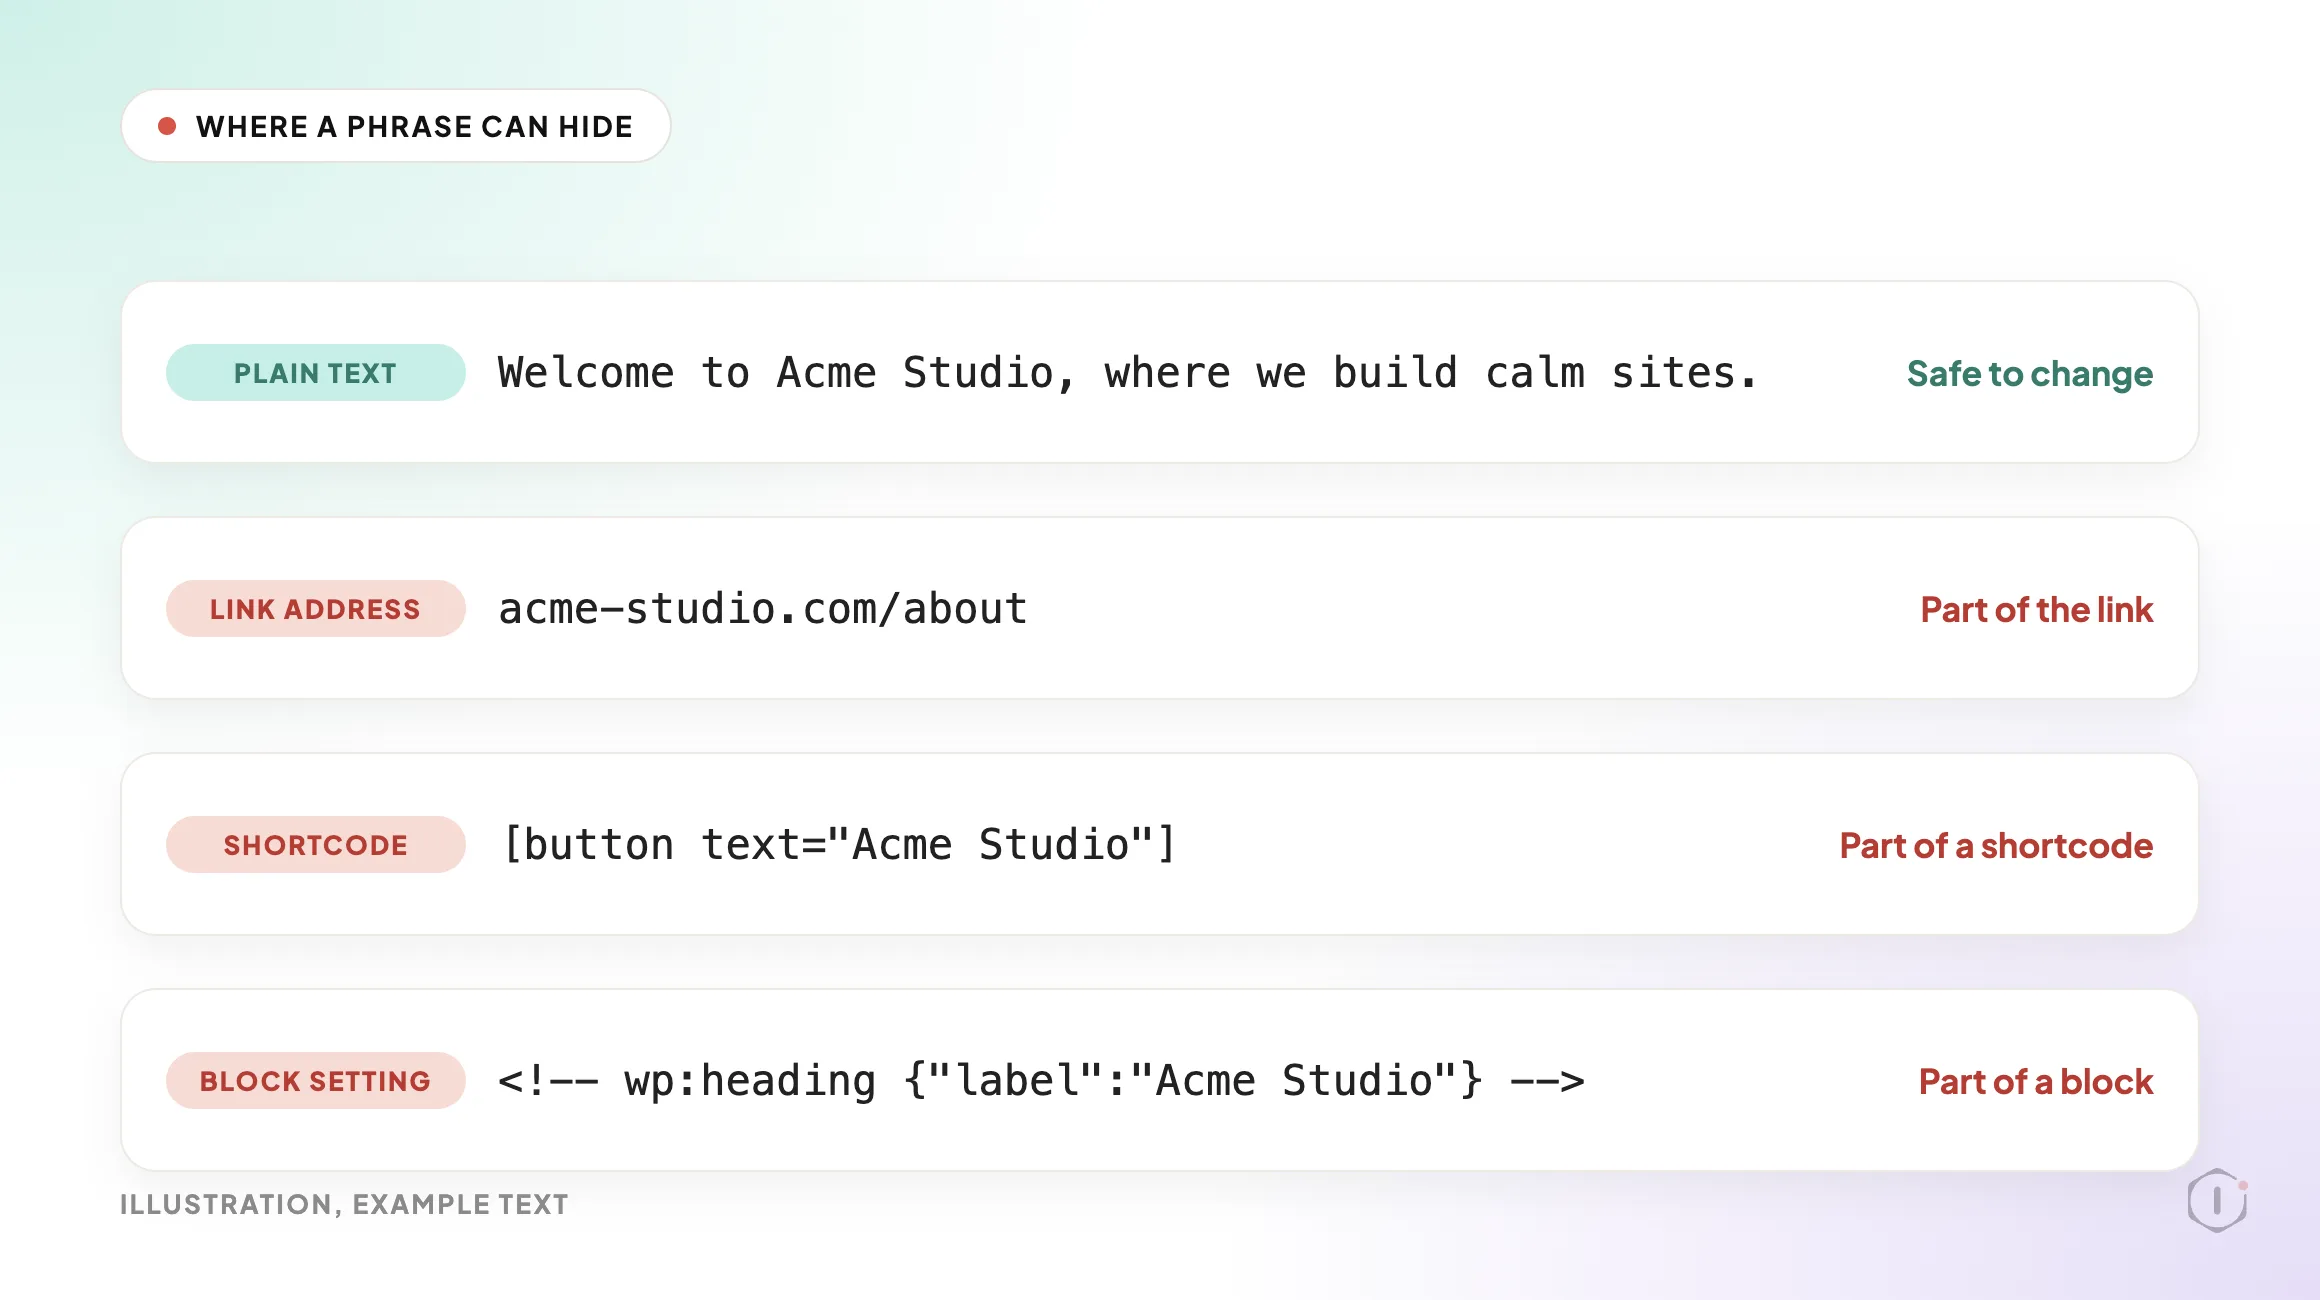
    Where a phrase can hide in a WordPress post

    What this post is, and is not: it is a practical walkthrough of how a Protuno playbook works and how to do the same job by hand. It is not a measured result from a real site, and it does not promise that every occurrence of a phrase on your site will be found. It explains what the playbook reads, what it changes, and what it deliberately leaves for a person.

    A phrase in a paragraph is text. A phrase in a link is part of the link.

    Why Search And Replace Goes Wrong

    The usual tool for this job is a search and replace plugin or a command. They are powerful, and that is the problem. A database-wide replace sees one big pile of text. It does not know that one match is a sentence and another match is the address of a page.

    Think about a rename from “Acme Studio” to “Acme Labs”. In a paragraph, the swap is exactly what you want. In a link address such as a URL that contains the old name, the same swap points the link at a page that does not exist. In a block comment that stores a setting, it can change a value the block expects to read back unchanged.

    Nothing warns you. The page still loads. The damage shows up later as a dead link or a block that quietly resets itself.

    A bulk replace is exactly the moment you want a verified backup. And scope matters too: a replace that runs everywhere also runs on menus, options and page builder data you never meant to touch.

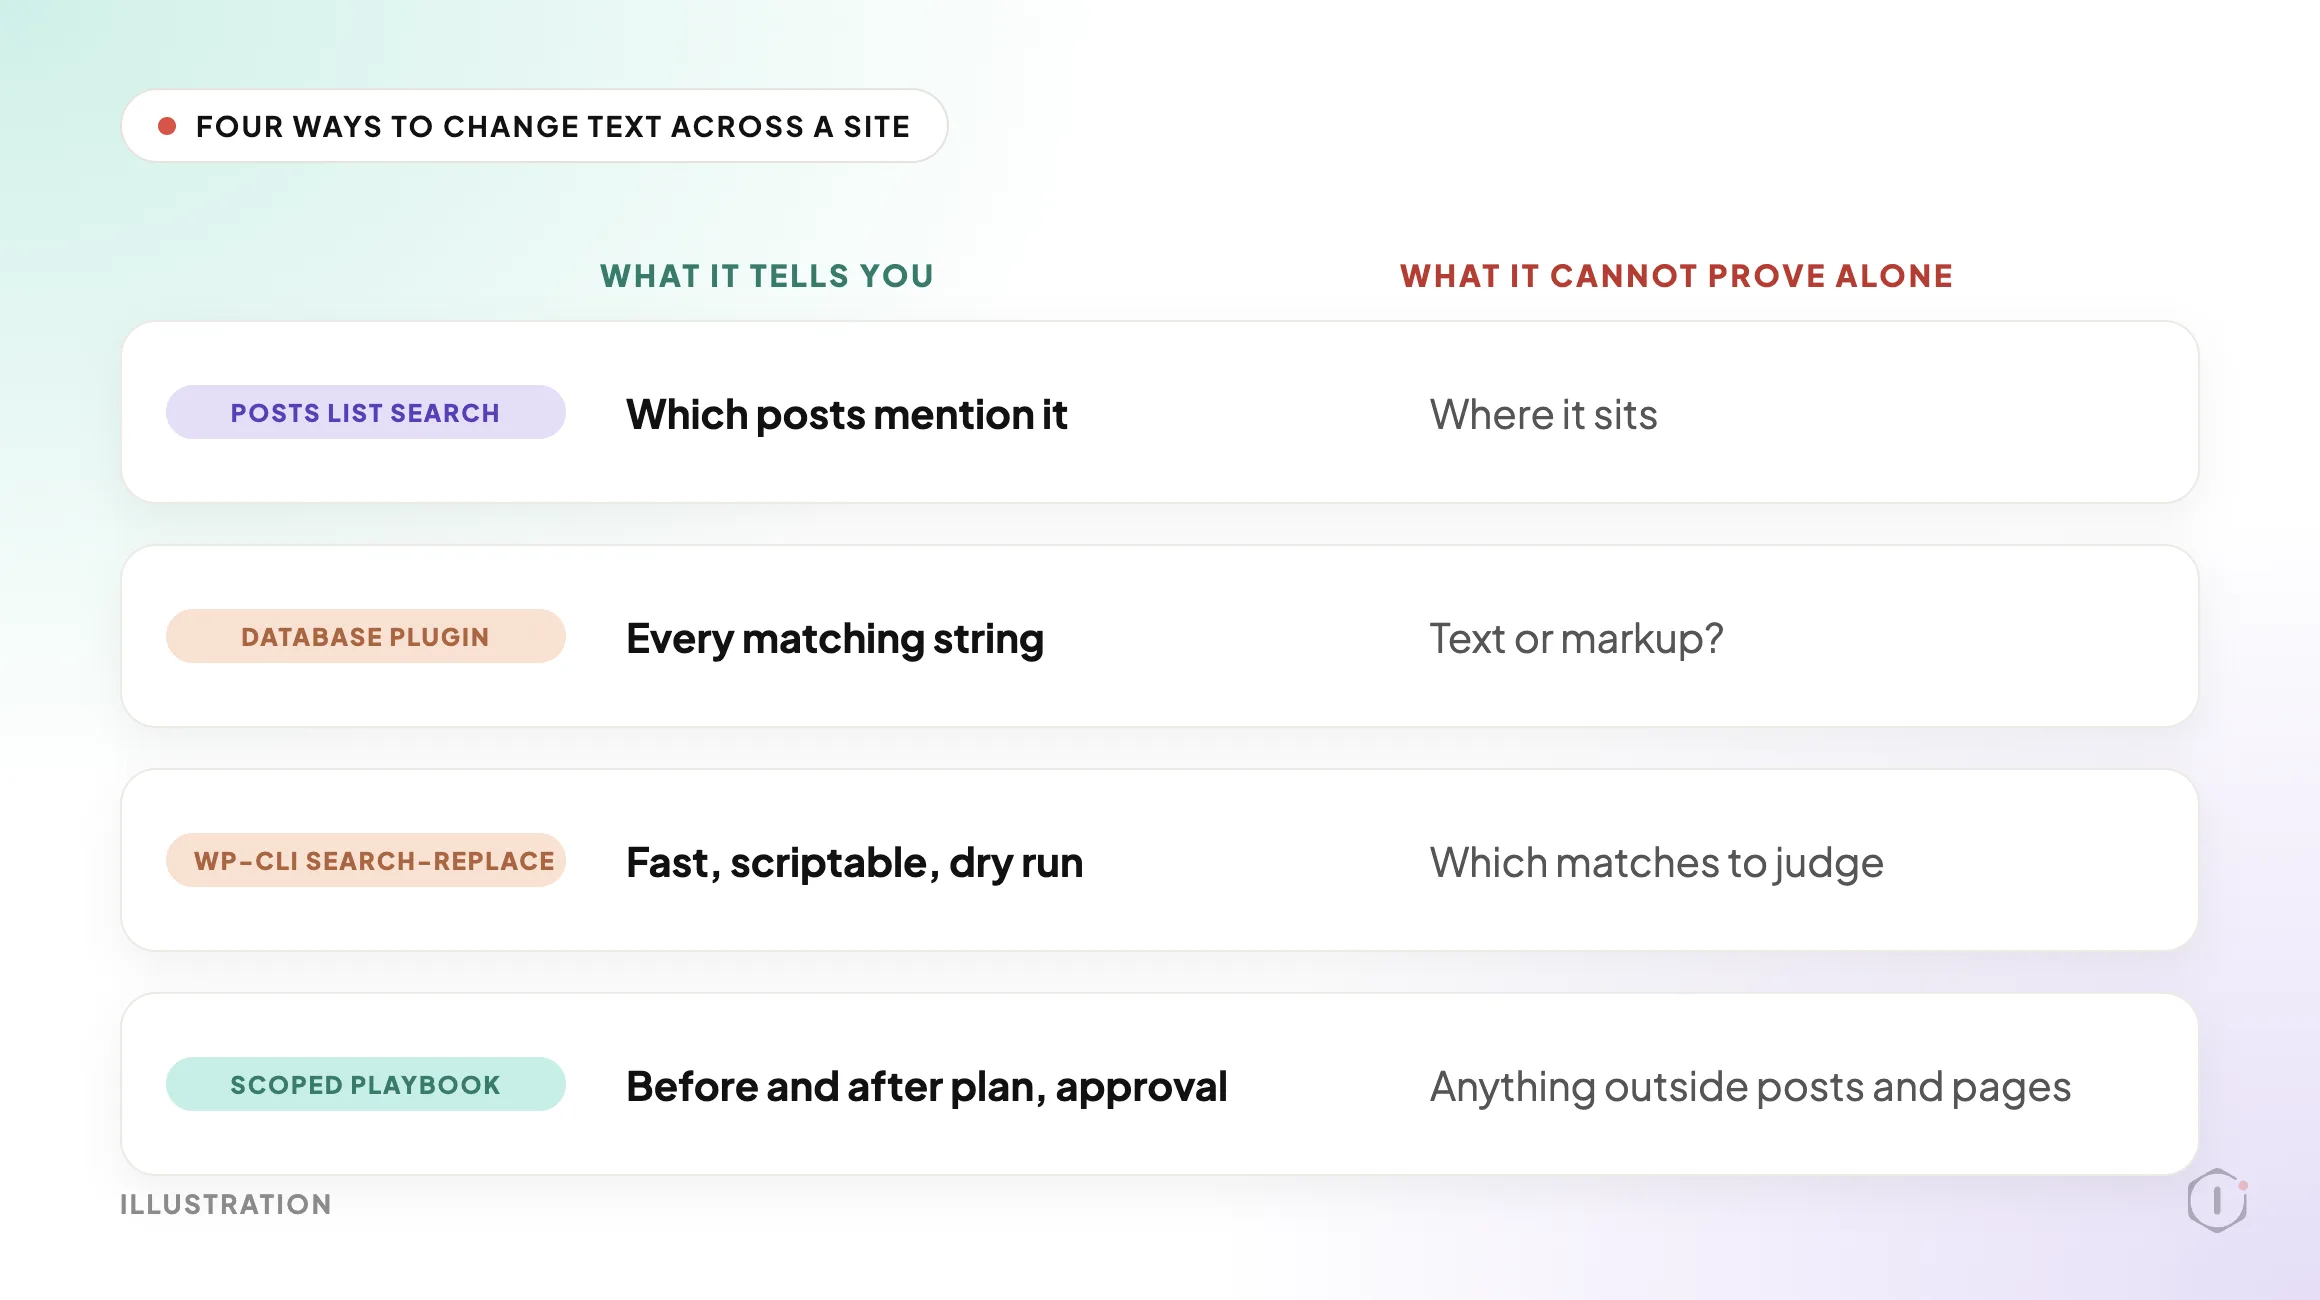
    Four Ways To Change Text Across A Site

    There are four common ways to change a phrase everywhere. Each one answers a different question.

    ViewWhat it tells youWhat it cannot prove alone
    The WordPress search box in the Posts listWhich posts mention the phraseWhere in the post it sits, or whether it is inside a link
    A database search and replace pluginEvery matching string in the tables you pickWhether a match was text, markup or a stored setting
    WP-CLI search-replaceA fast, scriptable replace, with a dry run you can ask forWhich matches a person should have judged first
    A scoped, approval-gated playbookA before and after plan for plain text in posts and pagesAnything outside posts and pages, which it leaves alone by design

    None of these is wrong. The WP-CLI search-replace command is well documented, and a plugin such as Better Search Replace is popular for a reason. The mistake is treating a tool that can change everything as if it were a tool that should.

    Four ways to find and replace, and what each one cannot prove

    What The Playbook Looks At

    Find & Replace Text is a Protuno playbook on the Care side of the public Playbooks page. In the dashboard’s Every Playbook list it sits in the Content group. It is marked Beta, it can change the site, and it has 2 steps. It needs no connector. It reads through the Protuno plugin.

    It works on one phrase that you choose, and it works as plain text. The scope is narrow on purpose:

    • Titles, excerpts and content of posts and pages.
    • Every exact match of your phrase.
    • Whether a match also sits inside block markup, an HTML tag or attribute, a shortcode or a link address.

    It never changes post meta, options, menus, widgets or page builder data. It changes at most 10 items per run, and a post that is too long to read in full is not changed at all.

    You set the phrase in the playbook’s Instructions, one option per line:

    Find: Acme Studio
    Replace with: Acme Labs
    Post types: post, page
    Fields: title, excerpt, content

    Only Find: and Replace with: are required. The phrase must be at least 4 characters. Replace with: may be empty, which removes the phrase. Post types and fields are optional, and by default the playbook uses both post types and all three fields. Matching is case sensitive and exact, so “acme studio” is a different string from “Acme Studio”. If either required line is missing, the playbook makes no changes and tells you which line to add.

    The Playbook, Step By Step

    Find & Replace Text is a Protuno playbook with a fixed sequence of two steps. The first step only reads the site. The second changes it, and only after you approve.

    #StepWhat it does
    1Scan And Snapshot MatchesFinds your phrase in posts and pages, plans each change as before and after, and records when each item was last modified. It writes nothing.
    2Apply And VerifyAfter you approve, replaces the phrase in each approved item, skips any item that changed since the scan, and reads each one back to confirm.

    Step 1 is read-only. The dashboard shows its Approval checkpoint as Off and its Automatic backup as None, which fits a step that writes nothing. Step 2 has the Approval checkpoint On: the run waits for your approval. Its Automatic backup also shows None, so the safety net here is the approval, the item-level before and after plan, and the recorded before-values, not a site snapshot.

    Order matters here. The plan comes before the change, and the approval sits between them. If the order were reversed, you would be approving a result after the fact.

    Step 1 does three things worth knowing:

    1. It searches posts and pages, including drafts, pending, private and scheduled items, and keeps the first 10 matches in ID order. Anything beyond that is reported as over this run’s limit.
    2. It reads each item in full. If the reply is cut short, or the content is longer than 6,000 characters, the item is reported as not checked because it is too long to read in full. A change is never planned from a partial read.
    3. It sorts every item into change, review by hand, or no change.

    An item goes into review by hand when the phrase also appears inside block markup, a tag or attribute, a shortcode or a link address. Even one such occurrence in any field is enough. Protuno lists it for you to fix yourself rather than guess.

    Step 2 is careful in a different way. It records when each item was last modified during the scan. Before it writes, it re-reads the item and compares. If the item was edited in the meantime, it skips it with the reason “changed since the scan”. If the phrase now sits inside markup or a link, or has gone, it skips that too.

    Then it writes only the fields that held the phrase, through Protuno’s content update route, which records each changed field’s before-value. After the write it reads the item back. An item counts as changed only when each written field no longer contains the phrase and contains the replacement as many times as the phrase appeared before.

    Watch The Walkthrough

    The video below follows the two steps in order, from the instruction lines to the plan, the approval and the read-back. It is an illustration built from the playbook’s step names and described behaviour. It shows no real site and no measured result.

    Illustration of the two steps, built from the playbook’s step names. It is not a run on a real site.

    What Find And Replace Does Not Solve

    A scoped replace is safe because it is narrow. That also means it leaves things alone.

    • It does not change post meta, options, menus, widgets or page builder data. If your old name lives in a menu label or a builder template, you fix it there.
    • It does not change an item where the phrase also sits in a link, block settings or a shortcode. Those go on the review by hand list.
    • It does not handle more than 10 items per run. A site with hundreds of matches needs several runs.
    • It does not read posts that are too long to read in full, and it says so.
    • In a scheduled run, step 2 is skipped, so a scheduled run never makes the change. A person starts the run and approves it.

    A tool that says what it did not cover is more useful than one that reports a clean sweep. The same thinking sits behind the permission model for agents: the smaller the reach, the easier it is to trust.

    Questions To Ask Your Current Tooling

    Whatever you use for bulk text changes, ask it these:

    • Does it show me every change as before and after, before anything is written?
    • Does it tell me when a match sits inside a link or a setting, or does it replace it anyway?
    • Can it limit itself to titles, excerpts and content, or does it search the whole database?
    • What happens if someone edits a post between the preview and the write?
    • Is the before-value of every changed field recorded, so I can undo it?
    • Does it read the result back, or does it assume the write worked?

    If the answer to most of these is “I am not sure”, you are relying on luck, and a rollback plan is worth having before the next bulk change.

    Which Check Are You Actually Running?

    If you need to knowEvidence to look atNext action
    Which posts mention the phraseSearch results from the Posts listOpen the posts that matter and read them
    Whether a match is plain textThe post in the code editor, or the plan from step 1Change plain text, review the rest by hand
    Whether the change landedA read-back of each written fieldConfirm the count of replacements matches the count of matches
    Whether you can undo itRecorded before-values for each changed fieldUse Rollback on the run in the app

    Rollback is part of the design. Every change the playbook makes is recorded with its before-value, field by field, and Roll back in the app undoes the changes it made.

    Fixing Findings In The Right Order

    When the plan comes back, do not treat every line the same way.

    PriorityWhat to do
    FirstRead the review by hand list. These are the matches the playbook refused to change, and they are where a blind replace would have caused damage.
    SecondRead the before and after snippets for the items marked to change. Look for a replacement that reads oddly in context.
    ThirdCheck the not checked list. Long posts need a manual pass.
    LastApprove the run once the plan reads the way you want.

    Two rules help:

    1. Have a restore point first. Step 2 shows no automatic backup, so take your own before approving anything on a site you care about.
    2. Re-check after the change. Open two or three changed pages and a page from the review by hand list. Read them as a visitor would.

    A Five-Site Audit You Can Do This Week

    You do not need the playbook to test your own process. Pick five sites you look after and, for each one, write down:

    • The phrase that changed most recently, such as a brand name, a product name or a price label.
    • How many posts and pages mention it, from the Posts list search.
    • How many of those mentions are inside a link or a shortcode.
    • Whether the site has a restore point you could use today.
    • Who would approve a bulk change, and where that approval is written down.

    Then decide, for each site, one of these:

    • Fix now: the matches are plain text and a restore point exists.
    • Test first: copy the site to staging and try the replace there. See staging drift for why staging and live can disagree.
    • Replace by hand: the matches sit inside links or settings.
    • Leave it: the old phrase is harmless, and you note who decided and when.
    • Investigate: matches show up in places you did not expect, such as old drafts.

    Why Old Text Quietly Comes Back

    A bulk replace is a one-time event, but old wording finds ways back in: a teammate pastes from an old document, or a reusable block still holds the old name. That is why the playbook reports what it left alone. If you want to keep content tidy in other ways, the Disable Comments playbook and the image alt text audit follow the same read first, change second pattern, and the broken link audit is a useful follow-up after any large text change.

    Two Outside Views

    A tutorial and a forum thread. Neither is an endorsement.

    Extreme How To’s video walks through a plugin route: install Better Search Replace, type the text or URL to find and the replacement, pick the wp_posts table, run a test, then run the replace. The test step is the part worth copying. It is also where the plugin route stops: the plugin counts matches in a table, and it does not say which ones are plain text and which sit inside a link or a block.

    A short tutorial on finding and replacing a URL or text in WordPress with a search and replace plugin, including a dry run before the real change.

    Extreme How To’s, “How to find and replace URL or text WordPress [2026 Full Guide]” on YouTube, 14 Aug 2026

    On Reddit, an r/Wordpress thread is titled as a migration that still cannot update every reference to a local address. I could not read the replies, so this post does not summarise them. The title alone shows the shape of the problem: after a move, old addresses survive in places a simple text search does not reach, which is why a replace needs a plan before it needs a button.

    “Migrating from Studio still can’t update all references to local”

    r/Wordpress, “Migrating from Studio still can’t update all references to local”

    Where Protuno Fits

    Protuno’s Super Agents page describes the Care agent, Wren, as the one that runs updates behind a restore point and watches the jobs that quietly stop. This playbook is one of the Care playbooks that can change a site, so it asks first.

    The pattern is the same every time. Protuno plans the change, shows it to you, waits for you, then writes only what you approved and reads it back. You can see every step written out on the Playbooks page and meet the agents on the Agents page.

    The fields it works with, title, excerpt and content, are the same ones the WordPress REST API reference for posts documents.

    Sources And Further Reading

    The Point

    A find and replace should be boring. You pick a phrase, you see what will change, you approve it, and you check that it worked.

    The risk was never the swap. It was the swap in the wrong place.

    So when you last changed a phrase across a site, did you know which matches were text and which were part of something else?

  • Disable Comments In WordPress: The Playbook, Step By Step

    Disable Comments In WordPress: The Playbook, Step By Step

    You switched comments off. Your site still takes them.

    That is the quiet trap in WordPress. One checkbox sounds like a site-wide switch, and it is not one. If you want to disable comments WordPress-wide, that single setting is not enough.

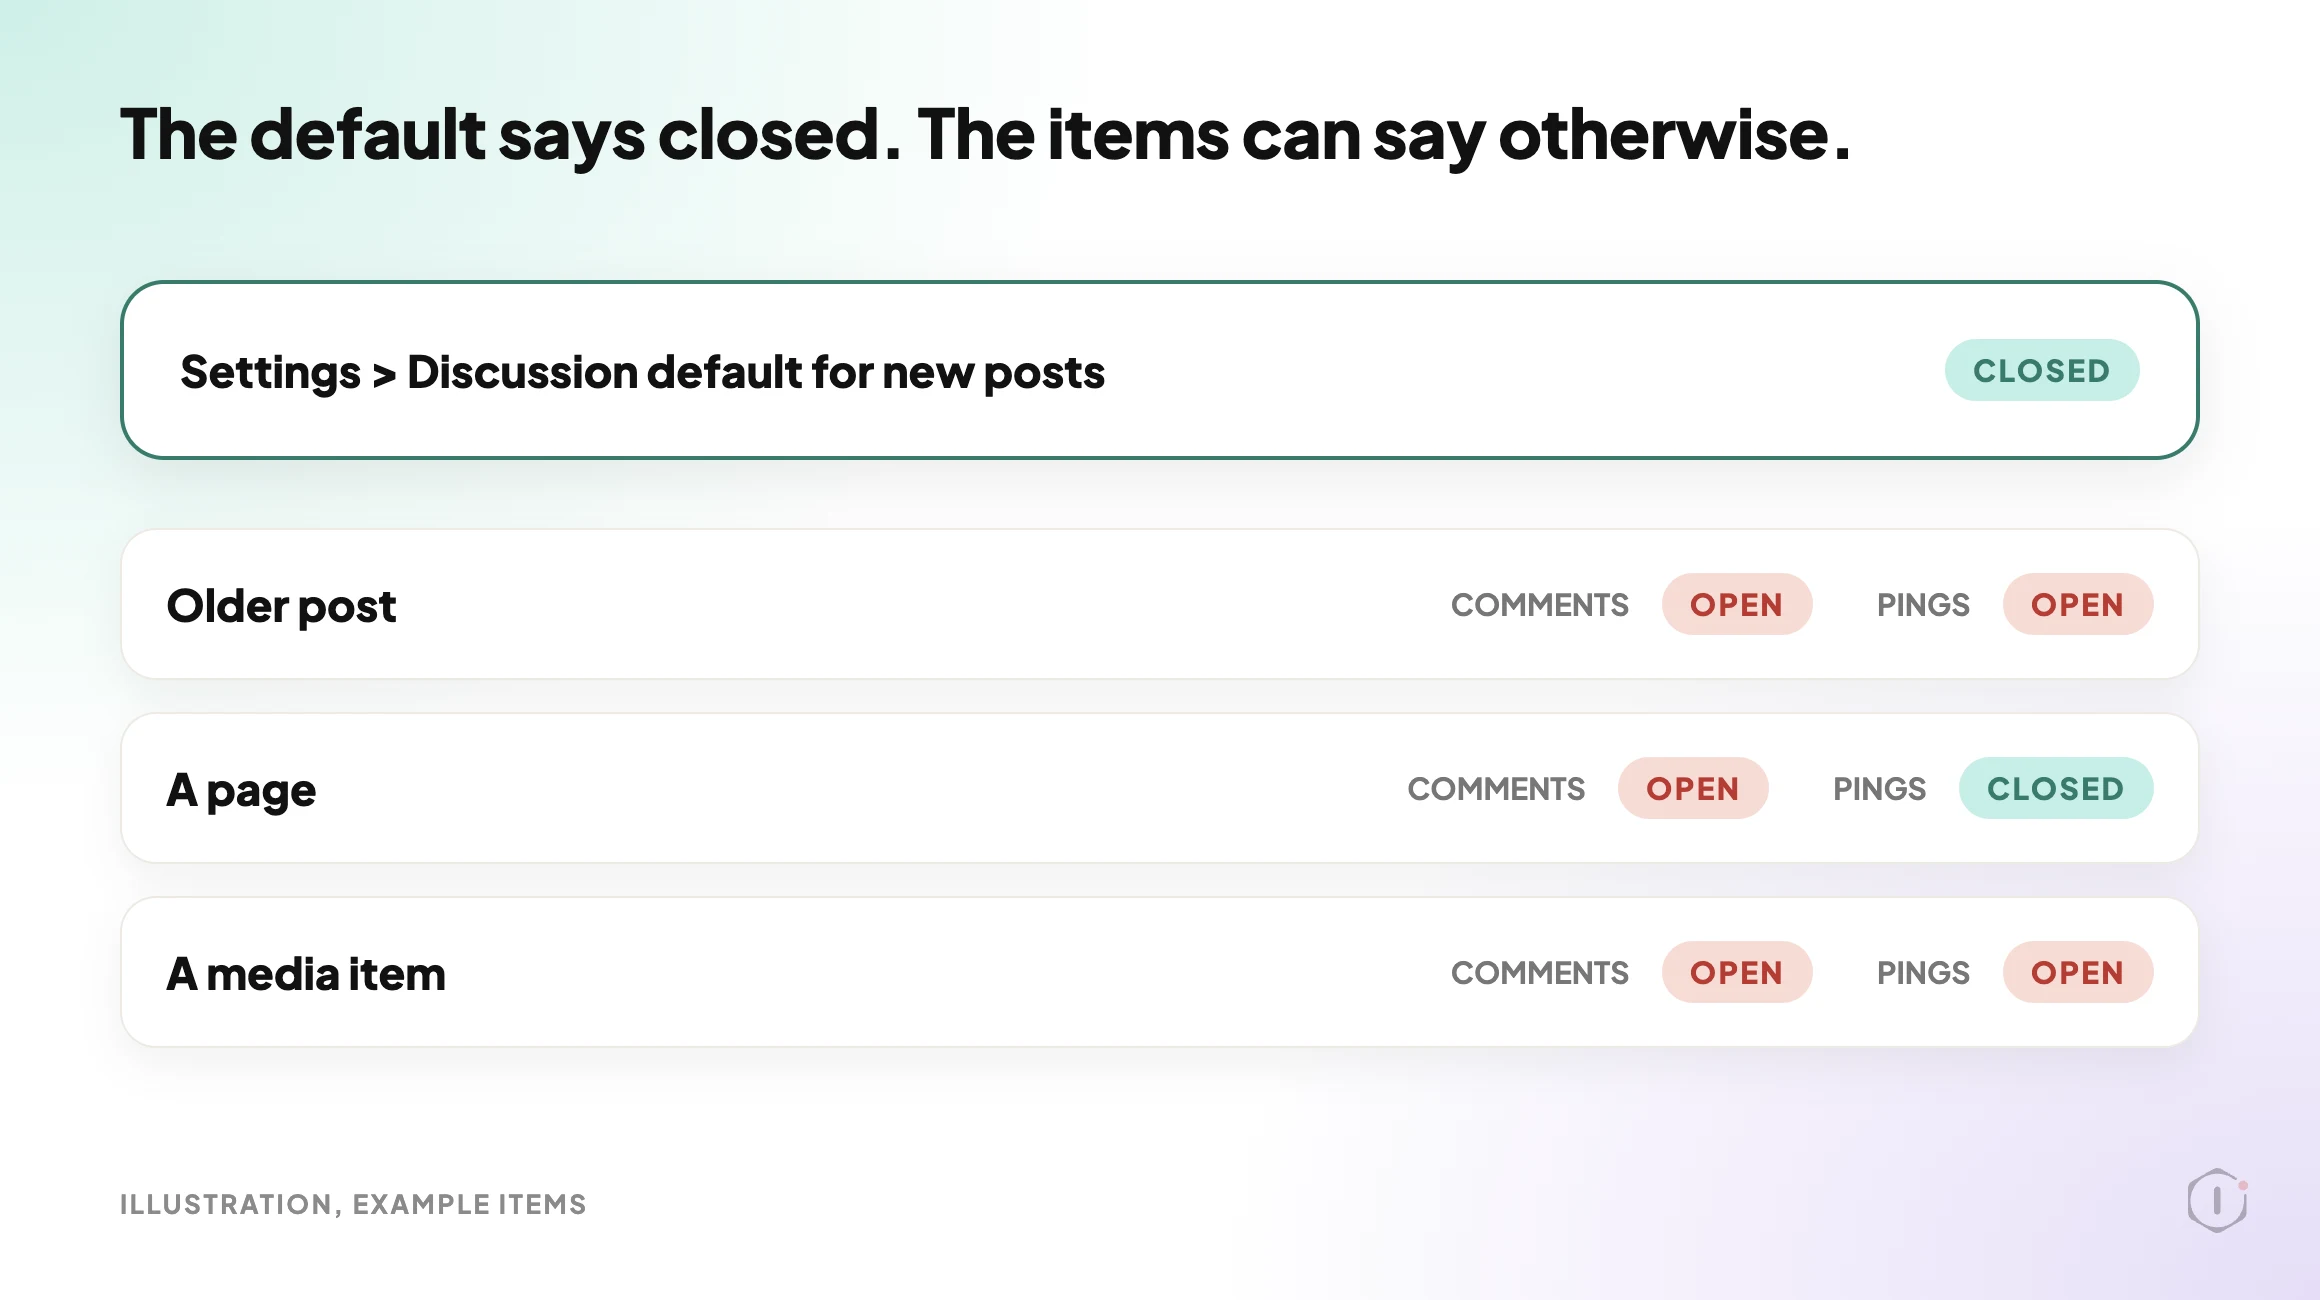
    Short answer: the Settings > Discussion checkbox only sets the default for posts you write from now on. Every older post, page and media item keeps its own comment and ping setting. To really close comments, you need to close the defaults and the existing items, and keep the comments you already have untouched. Protuno’s Disable Comments playbook does exactly that in two steps: one read-only step that plans, then one write step that waits for your approval.

    Where comments can still be open on a WordPress site

    What this post is, and is not: it is a practical walkthrough of how a Protuno playbook works and how to do the same check by hand. It is not a measured result from a real site, and it does not promise that a closed item will never receive a spam attempt. It explains what the playbook reads, what it changes, and what it refuses to touch.

    A setting is a default. An item is a fact.

    Why The Settings Checkbox Falls Short

    Open Settings > Discussion in WordPress and you will find the box that says people can post comments on new posts. WordPress’s own documentation words it carefully: it is the setting for new articles, and individual articles can override it.

    That wording matters. The box is a template that gets copied onto each new post at creation time. Posts that already exist are not rewritten when you change the template.

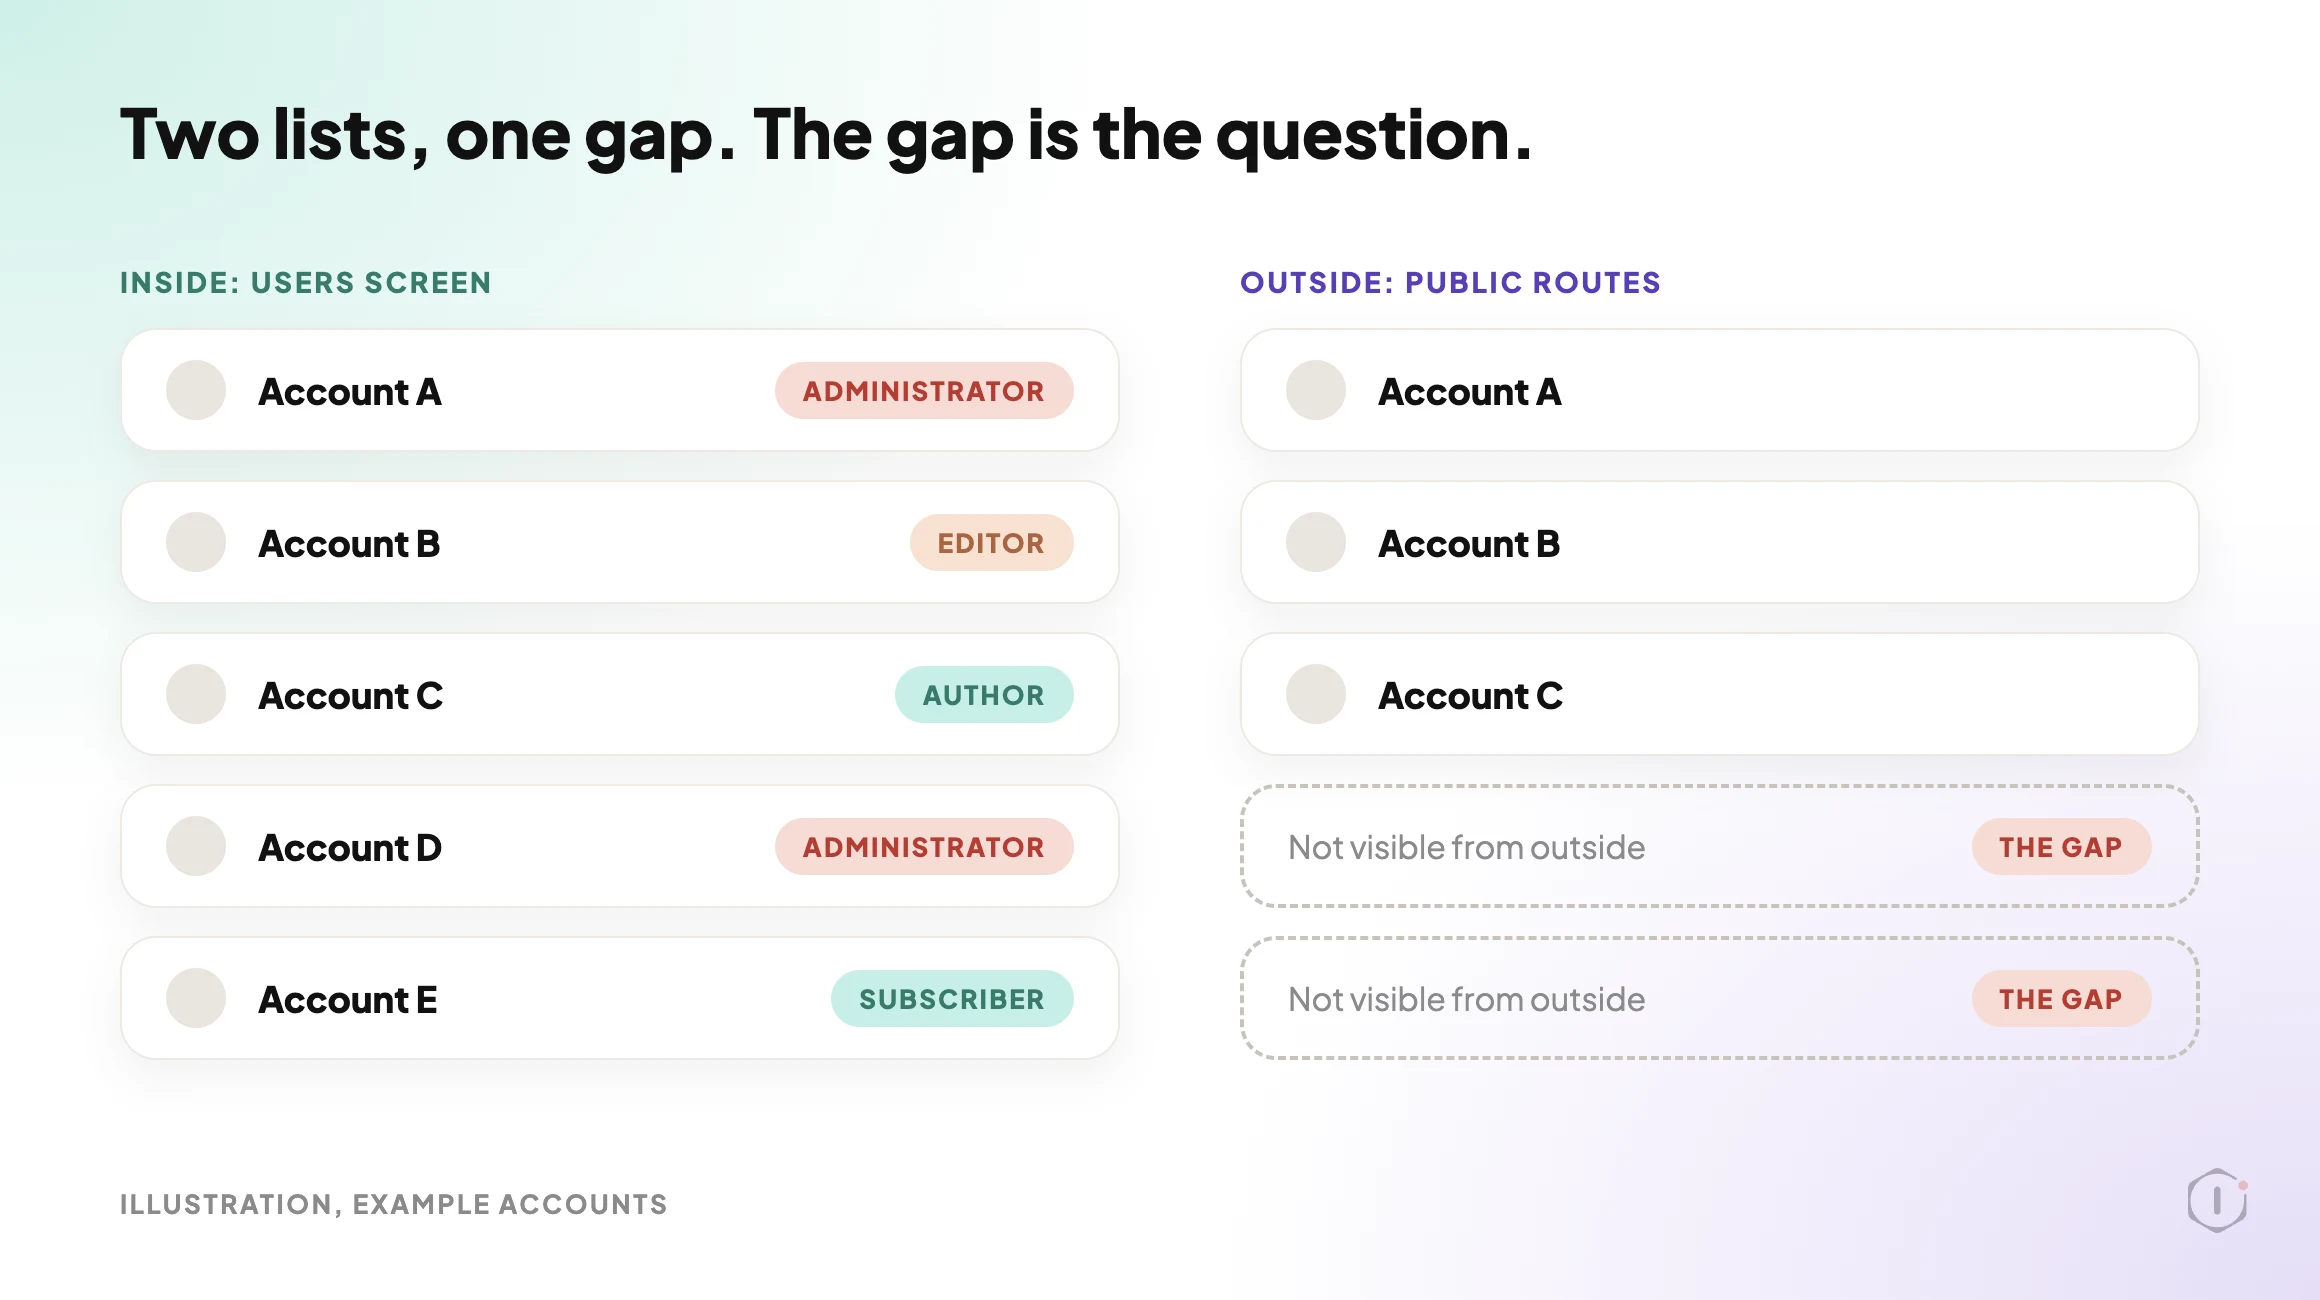
    So a site that turned comments off two years ago can still have a hundred older posts with comments open. Spam bots do not care which setting you changed last. If you have ever had to clear a flood of junk, you have met the result. We covered the cleanup side in WordPress Spam Comments: The Playbook, Step By Step. This post is about closing the door instead of mopping the floor.

    There is a second, easier-to-miss setting. Comments and pings are separate switches. A post can have comments closed and still accept pings, the link notifications other sites send. WordPress’s documentation lists them as two different options. Pings are the same family of traffic as xmlrpc.php, so closing comments but leaving pings open leaves half the door ajar.

    Four Ways To Look At The Same Problem

    There are four common ways people turn comments off. Each one answers a different question.

    ViewWhat it tells youWhat it cannot prove alone
    Settings > Discussion defaultNew posts will start with comments closedWhether any existing post is still open
    Bulk edit in the Posts listThe posts you selected are now closedPages, media items, and posts you did not select
    A plugin that removes comments sitewideThe comment feature is hidden or blocked in the siteWhether the stored setting on each item changed, and how you undo it
    Auto-close after a number of daysOld posts close on a schedulePosts newer than the cut-off, and pages and media

    None of these is wrong. They answer different questions, and the mistake is treating the first one as if it answered all of them.

    The part people forget is media. WordPress can keep a comment status on attachment pages too, so an old image can be a place where comments are open even when no post looks open. A hand check that only looks at the Posts screen never sees it.

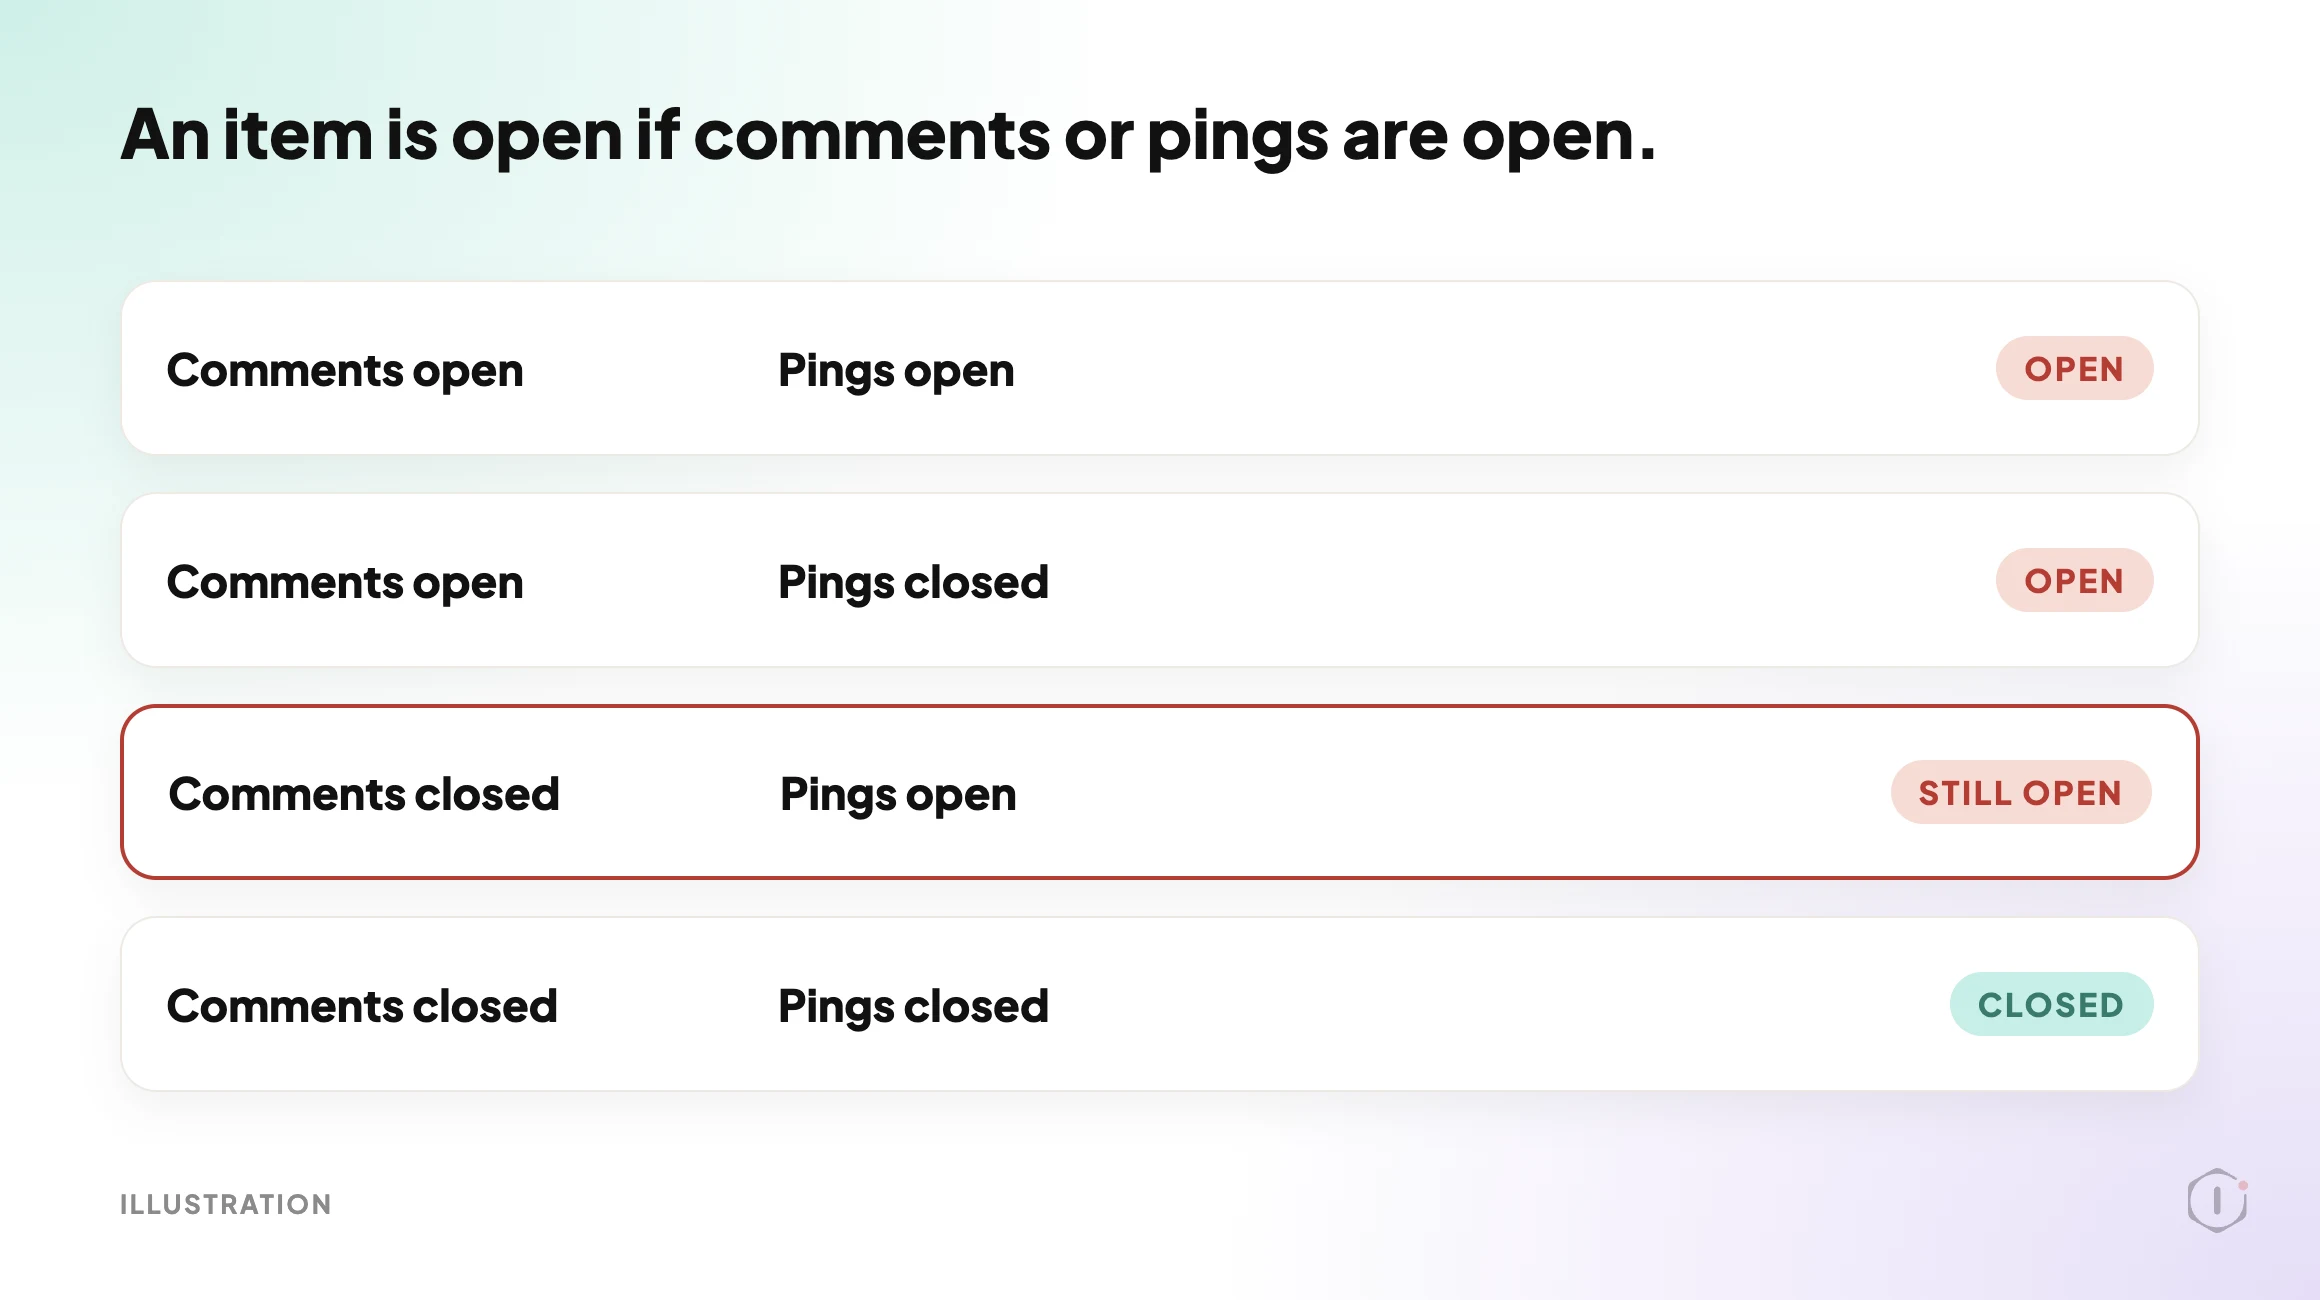
    An item is open if either comments or pings are open

    What The Playbook Looks At

    Disable Comments is a Protuno playbook in the Content group of the Every Playbook list. It is marked Beta and shown as Can Write, with 2 steps. You will find it in the dashboard’s Every Playbook list, not on the public playbooks page.

    It is built around one rule that is worth reading twice. The playbook only closes comments and pings. It changes two Discussion defaults, and each item’s comment status and ping status. It never deletes, approves, unapproves or edits a comment, and it never touches any other field.

    That scope is the reason it is safe to describe. A tool that can “manage comments” is a broad promise. A tool that can only flip two switches on a list you approved is a small one.

    The Playbook, Step By Step

    Disable Comments is a Protuno Content playbook with a fixed sequence of two steps. The first only reads the site. The second changes it, and only after you approve.

    #StepWhat it does
    1Comments Baseline And SnapshotReads the two Discussion defaults, counts open and closed posts, pages and media, counts existing comments, and plans up to 25 items to close. Writes nothing.
    2Apply Comment ClosuresAfter approval, closes the defaults and the planned items, reads every change back, and checks that the comment count has not changed.

    Here is how each step works, based on the step instructions shown in the dashboard.

    Step 1: Comments Baseline And Snapshot

    This step is 100 percent read-only. It begins with the before-values: whether new posts accept comments, and whether they accept pings.

    Then it reads posts, pages and media, newest first, 100 per page, asking only for the id and the two status fields. Drafts, private, pending and scheduled posts are included, not just published ones. The instructions cap the read at 5 pages per type.

    An item counts as open when its comment status is open, or its ping status is open. The instructions call out one case by name: pings open with comments closed is still open. WordPress’s default “Sample Page” is often exactly like that.

    It also counts existing comments, page by page, and writes down the number. That count is the control for step 2.

    Finally it builds the close list: open items in the order posts, then pages, then media, newest first, at most 25. Each item’s current values are written beside it, so the change can be undone later. The step ends with a plan block that step 2 reads, and nothing else.

    Step 2: Apply Comment Closures

    The dashboard shows this step with an approval checkpoint turned on, which means the run waits for you. Step 1 has no checkpoint because it only reads.

    After you approve, the step does the following, in this order:

    1. If either default is open, it closes both defaults. Nothing else is sent in that settings call.
    2. It re-checks the planned items. An item that is already closed or missing is skipped, not rewritten.
    3. It closes each remaining item, changing only the comment status and the ping status. Each item’s previous values are recorded.
    4. It reads everything back. An item only counts as closed when the read-back shows both comments and pings closed.
    5. It counts comments again and compares with step 1. The count must match, or the step fails.

    The order is the point. The re-check protects against a plan that went stale while you were reading it. The read-back protects against a write that quietly did not stick. The comment recount is the proof that nothing was deleted along the way.

    The report ends with three honest tables: the defaults with before and after values, the items closed, and anything skipped or failed. It says plainly that the Discussion defaults are not covered by rollback, so it tells you the before-values to set them back by hand. The items are covered by rollback, and the report says so.

    The clip above is an illustration of the two steps and their order, built from the playbook’s real step names. It is not a recording of a run and it shows no results.

    What Disable Comments Does Not Solve

    A two-switch playbook has edges. Here they are, so nobody is surprised.

    • It does not delete or moderate comments. Existing comments stay as they are. If you want spam cleared, that is a different job, covered in WordPress Spam Comments.
    • It closes up to 25 items per run. A site with a few hundred open items needs several runs. The plan says how many remain open after each one.
    • It reads a limited window. Step 1 reads at most 5 pages of 100 per type, newest first. On a very large site, treat the first runs as a start, not a full census.
    • It does not remove the comment form from your theme. A closed item stops accepting new comments. How your theme displays a closed notice is a theme matter.
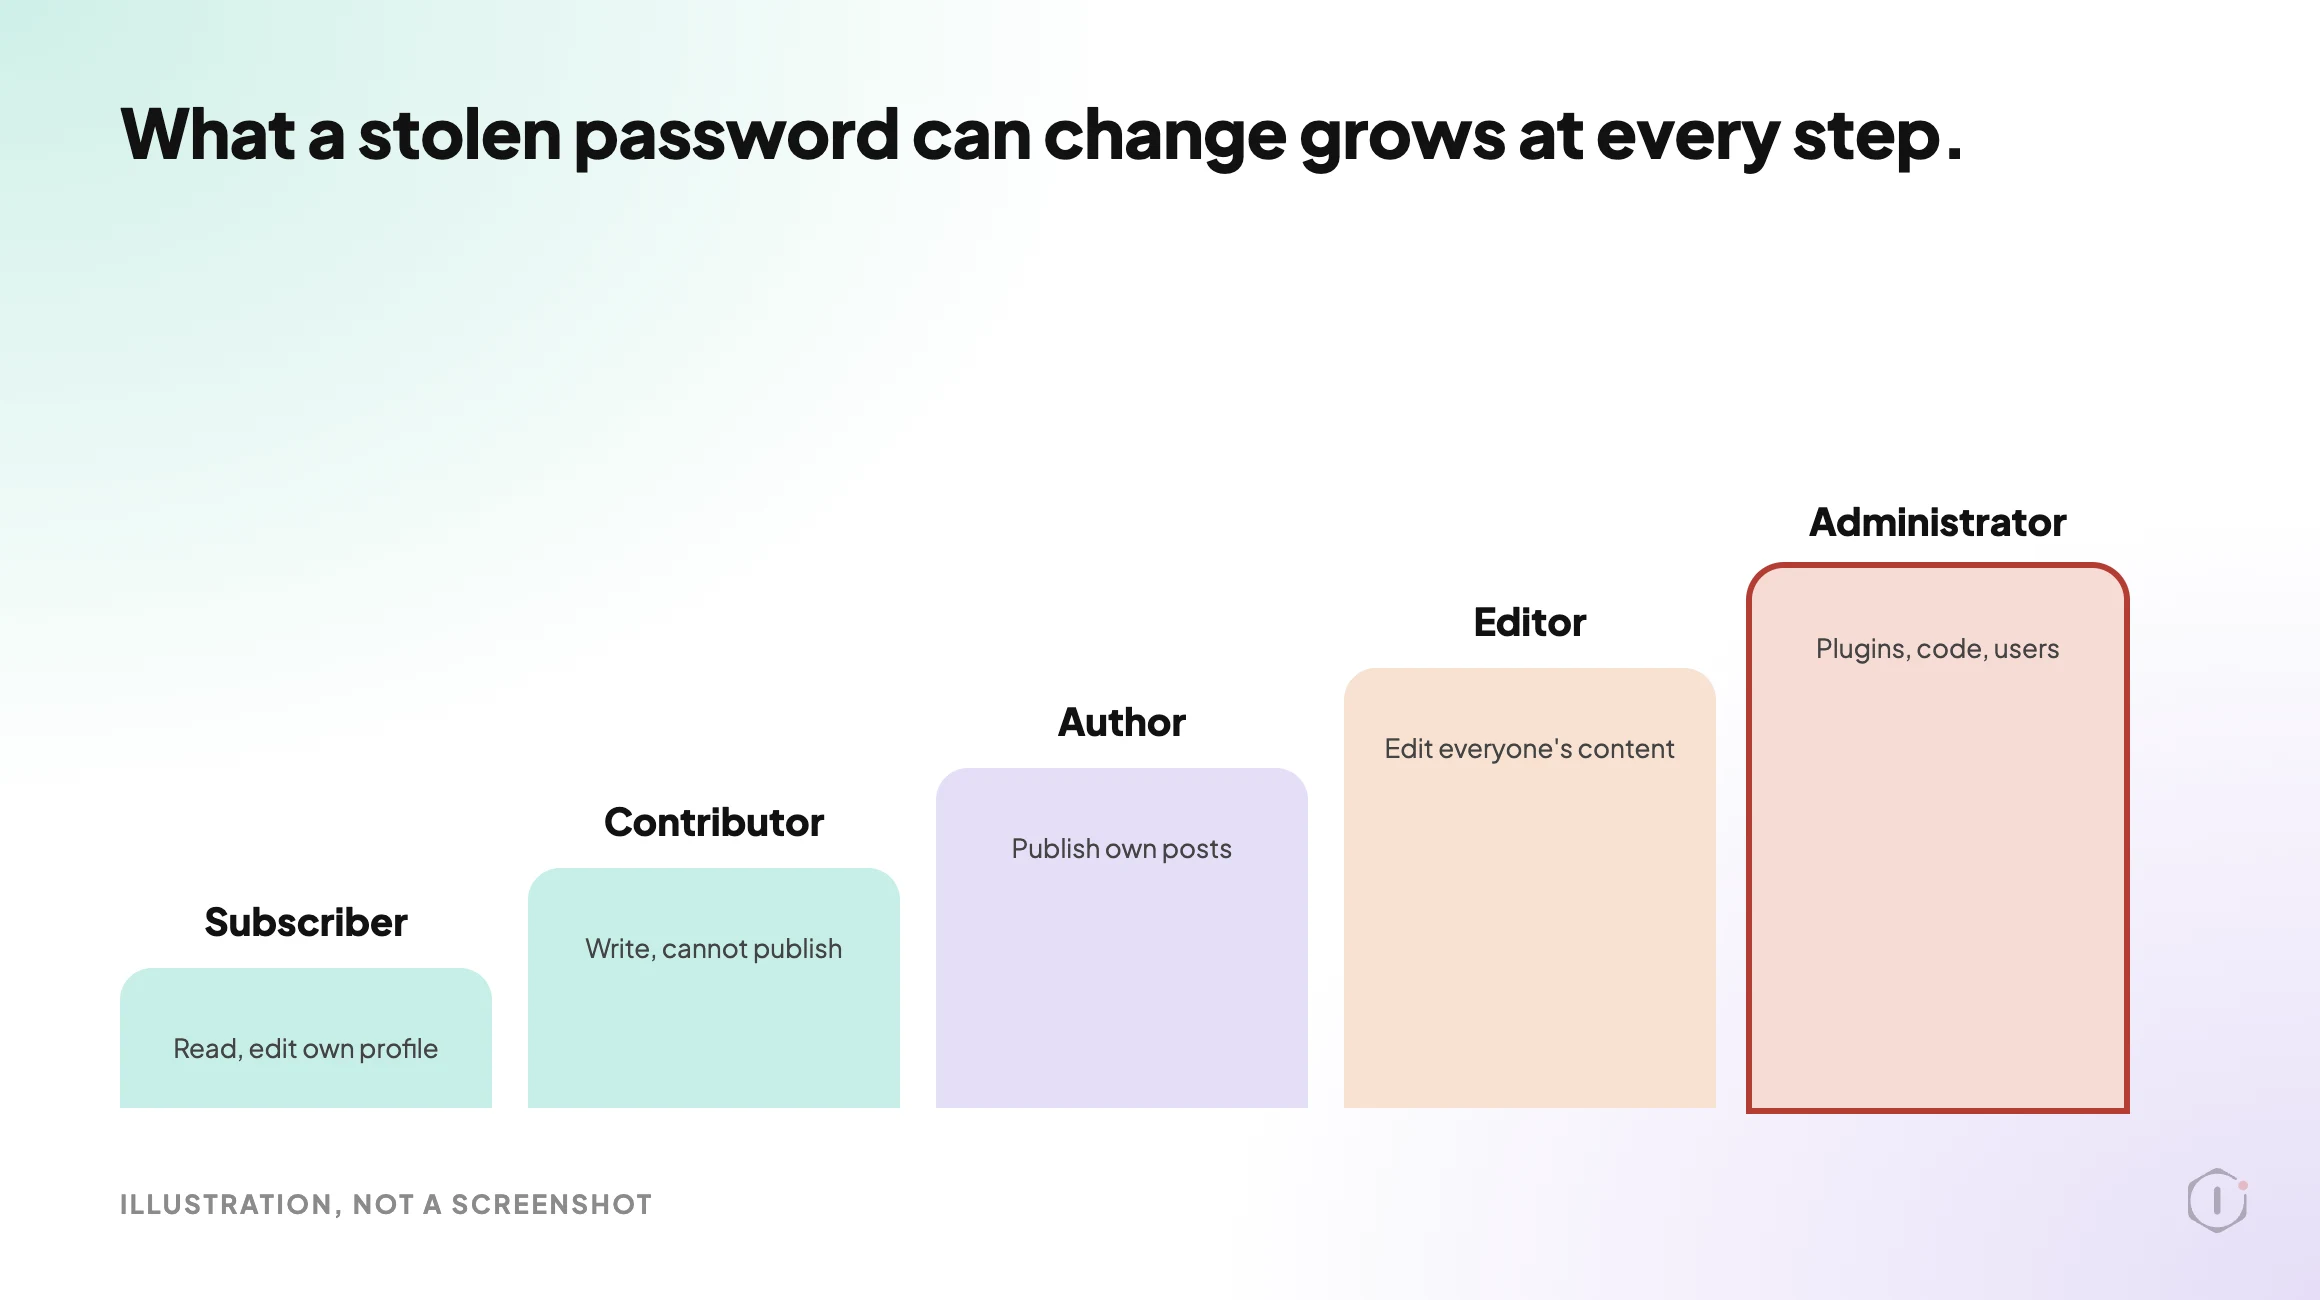
    • It does not stop spam signups or other abuse. If bots register accounts, that lives elsewhere. See WordPress User Roles for the access side.
    • The defaults are not rolled back by Rollback. Only the item changes are. The report gives you the before-values.
    • It has no automatic backup of its own. The dashboard shows Automatic backup as None for both steps. The safety net is the recorded before-values and Rollback for items. Take your own restore point first if the site matters.

    A Small Test You Can Run Today

    You do not need Protuno to see the problem. WordPress exposes each public post’s comment and ping status in its REST API. Try this on your own site:

    # Replace example.com with your domain
    curl -s "https://example.com/wp-json/wp/v2/posts?per_page=100&_fields=id,comment_status,ping_status"
    curl -s "https://example.com/wp-json/wp/v2/pages?per_page=100&_fields=id,comment_status,ping_status"
    curl -s "https://example.com/wp-json/wp/v2/media?per_page=100&_fields=id,comment_status,ping_status"

    Write down, for each type:

    • how many items returned "comment_status":"open"
    • how many returned "ping_status":"open" with comments closed
    • how many are closed on both

    Then compare with Settings > Discussion. If the setting says closed and your list still shows open items, you have just seen the gap this playbook exists for.

    Three cautions. This only sees what the public API shows, so private and draft items are missing from it. Each call returns at most 100 items, so if you get exactly 100 back, there are more. And counting open items tells you what exists, not whether anyone is using it.

    Questions To Ask Your Current Tooling

    If you already use a plugin or a bulk action to turn comments off, ask it plainly:

    • Does it change the stored setting on each existing item, or only hide the form?
    • Does it cover pages and media, or only posts?
    • Does it close pings as well as comments?
    • Can you see the before-values, and can you undo item changes?
    • Does it prove that your existing comments are untouched afterwards?
    • Does it wait for you before it writes?

    A good answer to the last two matters most. A write that cannot be undone and cannot show what it did is the kind of write you should not run on a client site.

    Which Check Are You Actually Running?

    If you need to knowEvidenceNext action
    Will new posts accept comments?Settings > DiscussionClose the default
    Are existing posts open?Each item’s comment statusClose items, with a way back
    Are pings still open?Each item’s ping statusClose pings with comments
    Did anything get deleted?Comment count before and afterCompare the two numbers
    Did the change actually stick?A read-back after the writeOnly trust the read-back

    Fixing Findings In The Right Order

    If your check finds open items, here is a sensible order.

    PriorityFindingWhy
    1Open defaultsEvery new post inherits them, so the problem grows
    2Open posts with the most trafficThey are the likeliest spam targets
    3Pages that accept commentsOften forgotten, rarely meant to be open
    4Media items with comments openInvisible from the Posts screen
    5Pings open with comments closedSame family of traffic, easy to miss

    Two practical rules apply whatever tool you use:

    1. Take a restore point first. The playbook records before-values, but a backup of the database is still the cleanest way back. See WordPress Rollback After An Update for what a rollback can and cannot undo.
    2. Re-check after the change. Run the same count again and compare. If the numbers did not move, the write did not land.

    A Five-Site Audit You Can Do This Week

    Pick five sites you look after. For each one, record:

    • the Discussion default for comments and for pings
    • the count of open posts, pages and media
    • the count of existing comments
    • whether comments are actually wanted on this site

    Then decide for each site:

    • Fix now: comments are not wanted and items are open.
    • Test first: comments are used on some posts, so list which and close only the rest.
    • Replace: a plugin hides the form but items stay open underneath.
    • Remove: a comment plugin you no longer need.
    • Accept with owner and date: comments stay open on purpose, with a named person and a review date.
    • Investigate: the numbers do not match what the owner expects.

    The decision that is easy to skip is the last one. “Open on purpose, owned by someone, reviewed on a date” is a perfectly good answer. “Open because nobody noticed” is not.

    Why Comment Settings Go Stale

    Comment settings drift for ordinary reasons. A new plugin imports old posts with comments open. A theme change adds a feature that re-enables them. A migration copies content but not the default. A team member publishes a page from a template that was built years ago.

    None of it is dramatic. It is just that a setting you checked in March says nothing about the post you published in June.

    That is why it helps to treat this as a check you repeat, not a task you finish. The Settings screen answers one question once. The items answer it again every time something new is created.

    Two outside references show how this looks in practice. A YouTube tutorial covers turning off comments on WordPress posts, and an r/Wordpress thread asks whether comments should stay in core at all.

    A short tutorial on turning off comments on WordPress posts.

    Entrepreneurs Skool, “Disable Comments On WordPress Posts” on YouTube, 28 Aug 2026

    “There is no single “turn off comments” switch. It’s a dance of around 7 setting hooks, last time I checked.”

    r/Wordpress, “Move Comments to a plugin in 8.0”, September 2026

    The video title promises an easy fix. The Reddit reply explains why that is only half true: the setting is spread across several places, which is the gap the two steps above are built to cover.

    Where Protuno Fits

    Protuno is a set of Super Agents for WordPress, each running playbooks against your connected sites. Disable Comments is one of the playbooks in the Content group, available in the dashboard. Other playbooks are listed at protuno.com/playbooks, and the agents are at protuno.com/agents.

    This one changes the site, so it needs the Protuno plugin connected. It plans first, you approve, and it writes only the two comment fields. A human decides every change, and the playbook reports what it did in plain tables.

    If you also care about the other side of tidy access, see WordPress Security Audit for the wider read-only picture.

    The Point

    Closing comments is not one click. It is a default, a list of items, and a proof that nothing was deleted.

    The only honest report is the one that shows the before, the after, and a read-back in between.

    When did you last count how many of your old posts still take comments?

  • Premium Plugin Licenses: The Updates That Stop Quietly

    Premium Plugin Licenses: The Updates That Stop Quietly

    A lapsed license does not break a site.

    It does something quieter: it stops the updates.

    Short answer: A premium plugin keeps running after its license ends, but WordPress plugin updates from the vendor, including security fixes, can stop arriving. To find out where you stand, list every installed plugin, work out where each one gets its updates from, read the license record each vendor’s system left on the site, and sort every plugin into a clear state. When a state cannot be read, call it unknown. Never call it fine. That is the order the Premium License Expiry playbook in the Protuno dashboard follows, and it is a check you can run by hand.

    What this post is, and is not: A practical way to find out which premium plugins on a site have lost their update feed, and how to word what you find. It is not a ranking claim, not legal advice about licensing, and not a result from a real run: no playbook was run for this post, and every visual is a labelled illustration. The step names and rules come from the playbook as the Protuno dashboard shows it. The playbook is Beta and read only.

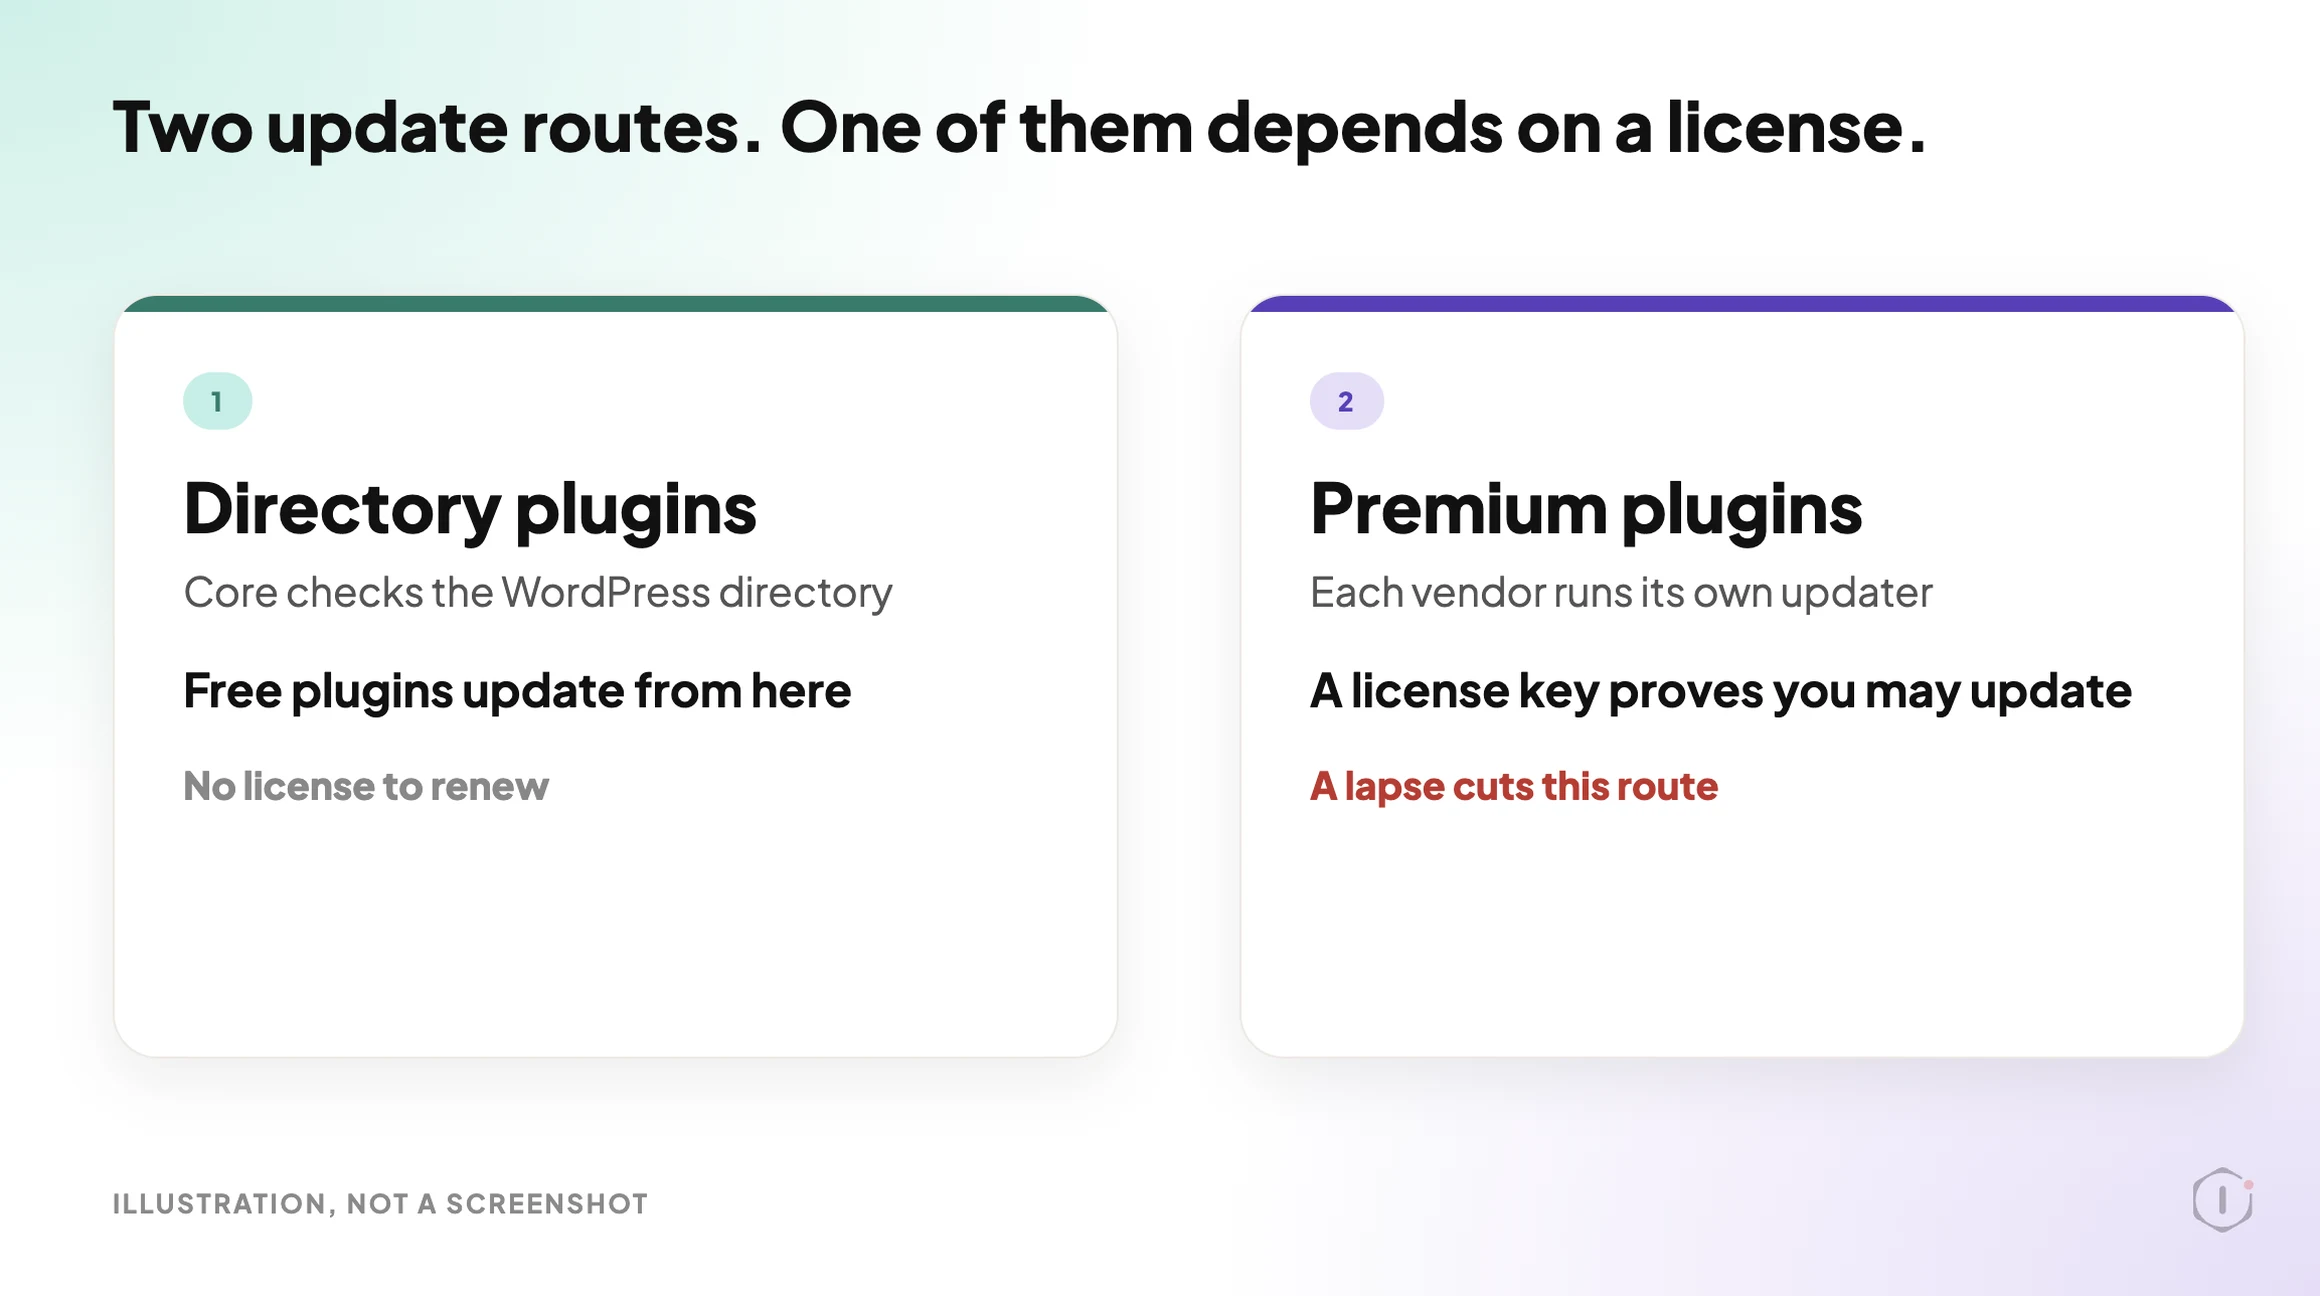
    Free plugins from the WordPress directory update from one place. Paid plugins update from many.

    Illustration of two update routes on one WordPress site: free plugins updating from the directory, and premium plugins updating through each vendor's own license
    Two update routes on one site. A lapsed license cuts the second one.

    Why A Lapsed License Is Easy To Miss

    Nothing visible happens on the day a license expires. The plugin still loads. The pages still render. The client sees no difference.

    What changes is the supply. A WooCommerce.com subscription, for example, is described by WooCommerce as giving you access to product updates and support for the duration it covers, billed annually or every two years. When that period ends without a renewal, the entitlement goes with it.

    Freemius describes licenses in similar terms: they control access to premium features based on the plan, the billing cycle and the number of allowed activations. Easy Digital Downloads Software Licensing works through its own license records too. Each vendor keeps a different record, in a different place, in a different shape.

    That is the real problem. There is no single license screen for a WordPress site. There is one screen per vendor, and nobody opens six of them on a Tuesday.

    The risk is not the expiry itself. It is the length of time between a security fix being published and anyone noticing the plugin never received it. WordPress 7.1.3, a security release with 7 security fixes, came out on 6 October 2026. Core has its own update path. A premium plugin with a lapsed license may get nothing from its vendor.

    Three Places A Plugin Gets Its Updates

    SourceHow the site learns about updatesWhat a lapse looks like
    The WordPress directoryCore checks the directory and records what it findsNot a license issue. A plugin pulled from the directory is a different problem
    The vendor’s own updaterThe plugin asks the vendor’s server, using a license keyThe key stops working. The plugin runs, and the update offer disappears or fails
    No updater at allNothing feeds itThe plugin was installed from a zip and never checks for anything

    The third row is the dangerous one, because it looks exactly like a healthy site. A plugin that has no updater does not show an error. It just never shows an update.

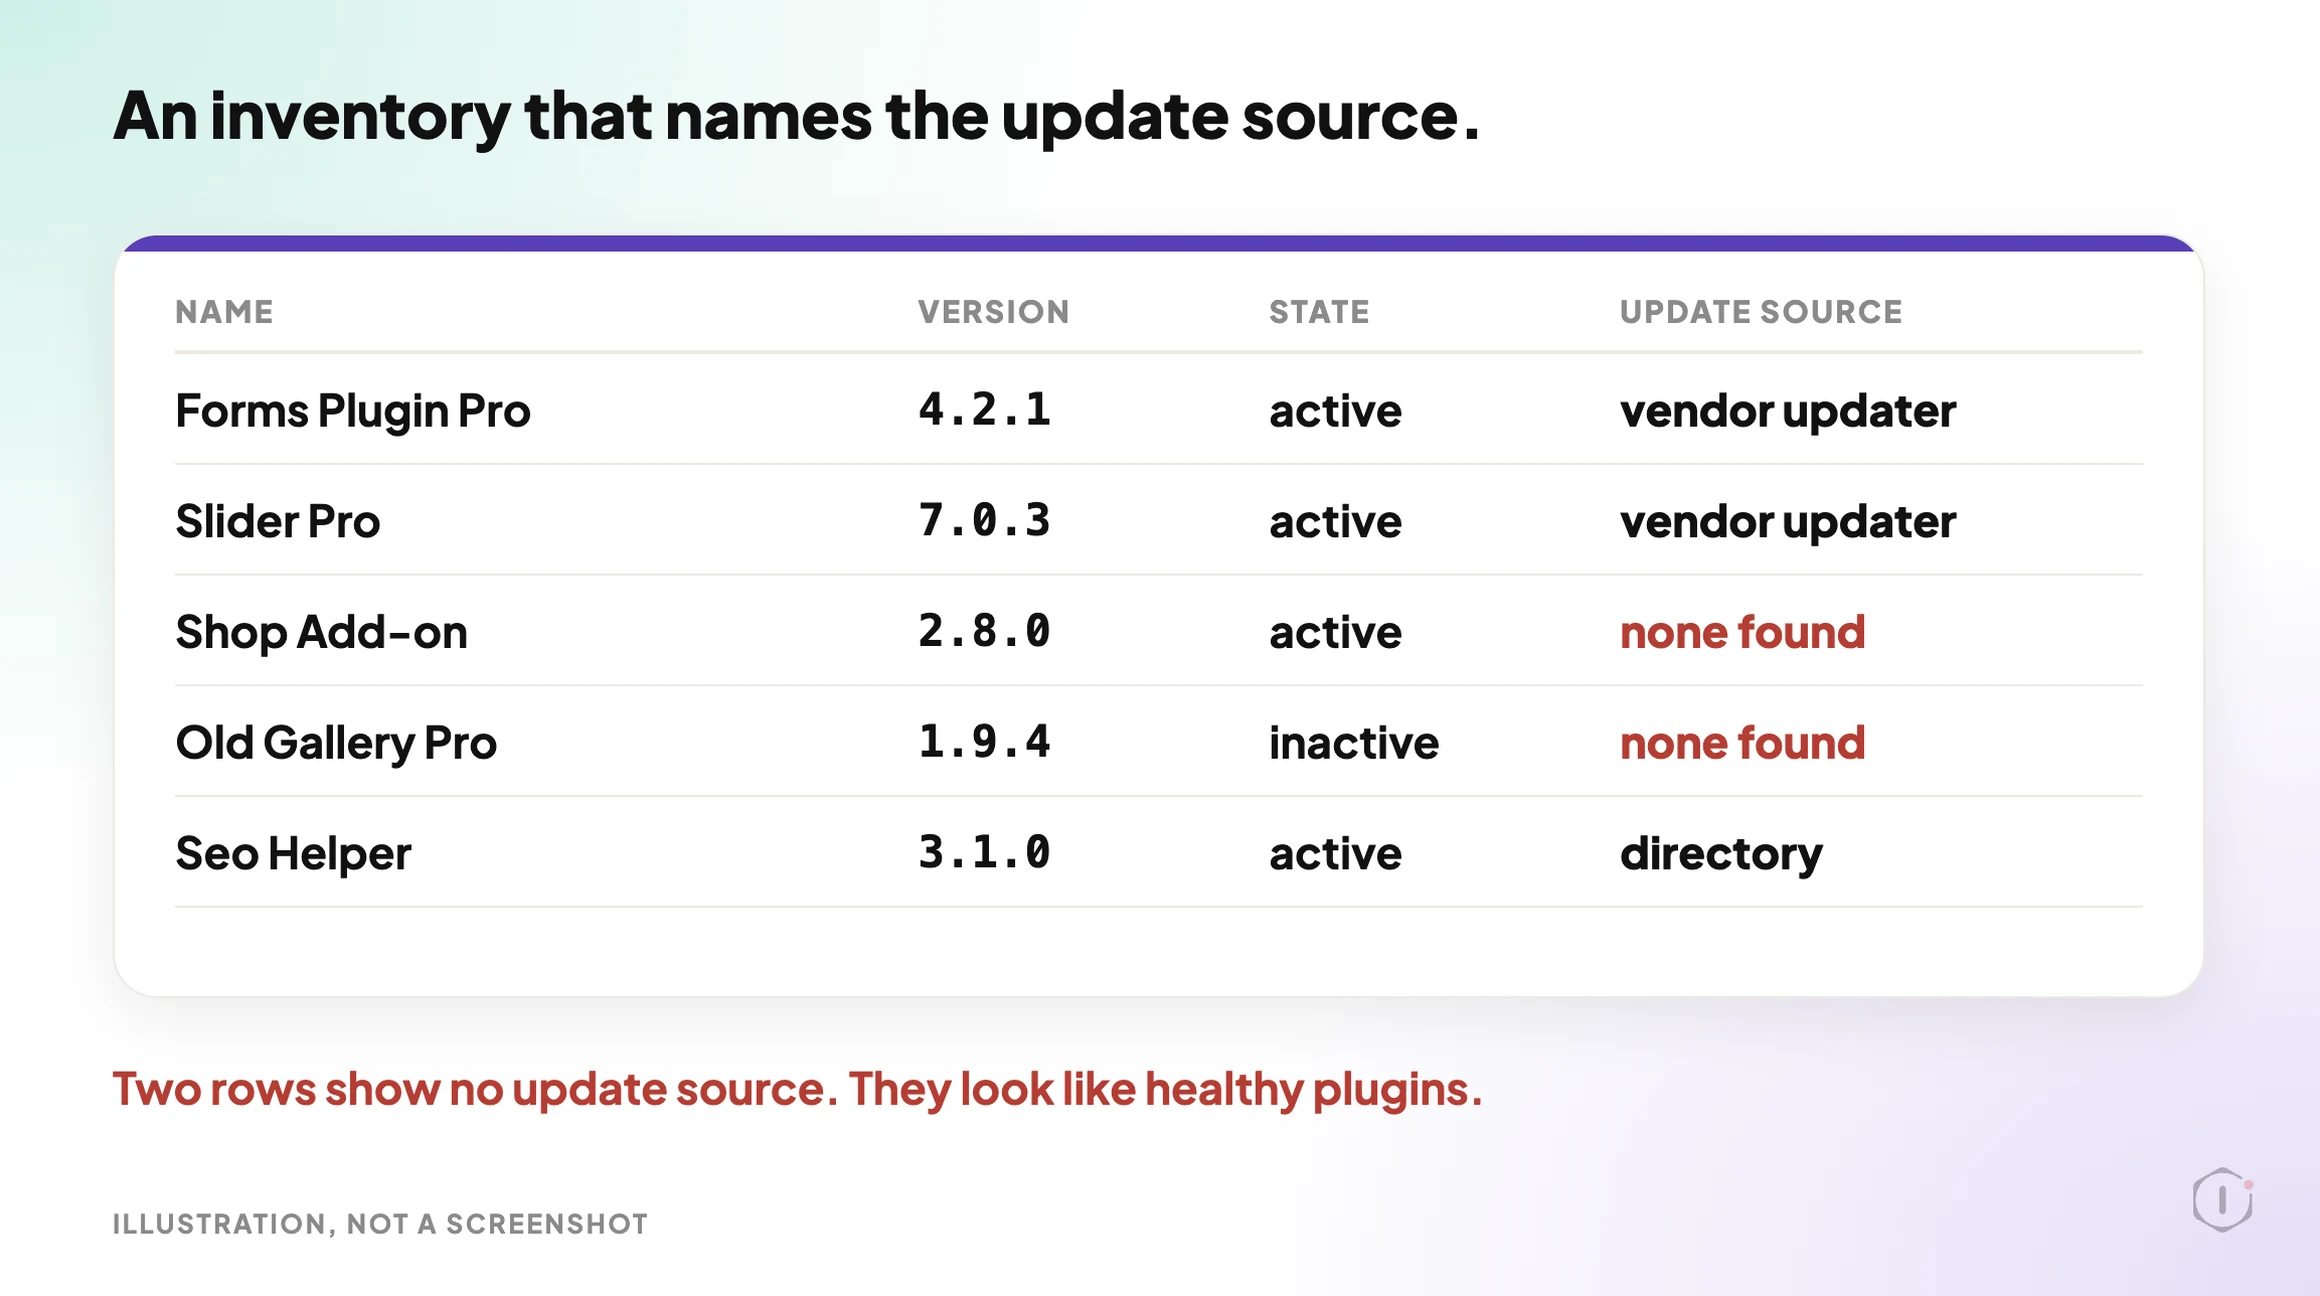
    Illustration of an inventory table with each plugin's name, version, active state and update source, two rows showing no update source
    An inventory that names the update source makes the silent rows visible.

    A Small Test You Can Run Today

    Open the plugin list on one site. For each plugin you did not get from the WordPress directory, write down:

    • The plugin name and version.
    • Whether it is active.
    • Which company sells it, and where you log in to see its license.
    • The expiry date that account shows, or “no account found”.
    • Whether the Updates screen has ever offered an update for it.

    Then ask one blunt question of every row: if this vendor published a security fix this morning, would this site hear about it?

    A rough way to see what WordPress itself knows about a site’s plugins, from a terminal with WP-CLI:

    wp plugin list --fields=name,version,status,update

    The update column shows what the site currently believes. It cannot tell you why a plugin shows nothing. A blank can mean up to date, or it can mean nothing is checking. That ambiguity is the whole point of this post.

    The Playbook, Step By Step

    Premium License Expiry is a Protuno Maintenance playbook. In the Protuno dashboard it carries a Beta label, is read only and runs seven steps, plus a Brief and Schedule screen. The public playbooks page lists a playbook with the same job under the shorter name License Expiry, described as warning before a paid plugin stops receiving security updates, and shows four steps. This post follows the dashboard’s names and seven steps. Check which version your account shows.

    #StepWhat it does
    1Enumerate Plugins And Update SourcesMakes one read-only call that lists every installed plugin with its name, version, active state and update source. A plugin that is installed but absent from the update records has no updater feeding it. It stops if the core plugin and update records cannot be read
    2Scan EDD LicensesReports the cached Easy Digital Downloads license records that really exist in the site’s options: a prefix, a status, an expiry and whether a key is present. No records is a normal, clean result. It never prints a key
    3Scan Freemius LicensesReports the cached Freemius license state: module, plan, expiry date, and whether it is lifetime or expired. A lifetime license is never reported as expired
    4Scan WooCommerce SubscriptionsReports whether the site is connected to WooCommerce.com, and for each subscription its product, expiry date, and whether it is active, expiring or expired
    5Classify Each PluginGives every plugin one class, with a confidence level and the evidence behind it
    6Optional Live License RecheckMakes no remote call. It needs an approval that a playbook has no interactive step for, and a vendor store address that standard WordPress options do not store. It will not guess one
    7License Expiry ReportTurns the classes into one report with a status of ok, warn or stopped, headlining the dangerous states first

    The order is the safety. Nothing is written at any step, and nothing is called healthy because it was not found broken.

    A 30-second walk-through of the seven steps. All example values are illustrations, not a real run.

    Seven Classes, And What Each One Means

    ClassPlain meaning
    validA license record was read and it is current
    expiring-soonA record was read and the expiry is close
    expired-still-runningThe license has ended, the plugin is still active. Updates are off, but the plugin works
    lapsedThe license has ended in a way the record marks as lapsed
    lifetimeA record was read and it has no expiry
    nulled-suspectA signal that may point to an unlicensed or tampered copy. Worded as “possible unlicensed or nulled copy (confidence: low, medium or high), needs verification”
    unknownThe state could not be determined

    Two of these deserve a pause.

    unknown is the honest class. The playbook’s rule is that an ambiguous or absent status is unknown, never valid, and that a vague match is never asserted as valid. A plugin the system cannot read gets reported as “unknown (not determined)”. It does not get the word fine.

    nulled-suspect is the class that can do harm if it is worded carelessly. A weak signal, for example a name with “Pro” in it and no entry in the update records, is not evidence of anything. Many paid plugins never appear in those records until their own updater has run. So every nulled-suspect line carries a confidence level, and a low-confidence line is a prompt to verify, never an accusation.

    What The Report Treats As Urgent

    FindingConfidenceHow it is treated
    expired-still-runningHigh, because a license status was actually readHeadline. The plugin works, but security updates are off
    lapsed or expiring-soonRead from a recordWarning
    nulled-suspectMedium or highWarning, worded as a possible unlicensed copy that needs verification
    nulled-suspectLowListed under “Needs verification”. Never urgent
    unknownNot determinedReported as unknown. Does not change the status

    For a low-confidence line, the advice is deliberately mild: open the plugin’s own license or settings page and confirm the license is active. If it is, there is nothing to do. The report does not tell you to remove, replace or switch a plugin on a weak signal.

    The status follows the same logic. The report is warn when any plugin is expired-still-running, lapsed or expiring-soon, or when a nulled-suspect has medium or high confidence. Low-confidence rows alone leave the status at ok, because otherwise every site whose connector plugin updates itself would be flagged.

    What A License Check Does Not Solve

    • Whether the plugin is any good. A valid license on an abandoned plugin is still an abandoned plugin. Our post on what a removed plugin leaves behind covers that side.
    • Whether a plugin has a known vulnerability. A license is about the update supply. Matching installed versions against vulnerability data is a different check, covered in vulnerability monitoring.
    • Vendor records the site does not keep. The playbook reads cached records on the site for Easy Digital Downloads, Freemius and WooCommerce.com. A vendor with its own system, or an account that only lives on the vendor’s server, is not covered by those steps.
    • A live answer from the vendor. Step 6 makes no remote call. What you get is what the site last recorded, not today’s answer from the vendor’s server.
    • Renewals. It reports. It never renews, updates or changes a license.
    • Sites that cannot run PHP. If the check cannot read the site’s own records, it says so and stops. It does not infer a license state from anything else.

    Which Check Are You Actually Running?

    If you need to knowThe evidenceNext action
    Whether a paid plugin is still being updatedThe update source and the license record, side by sideRenew, or plan a replacement
    Whether an installed plugin has a known security holeVersion against vulnerability dataRead the vulnerability monitoring approach
    Whether an update is safe to applyA backup, a test and a rollback pathSee how a safe update playbook is written down
    Whether the license cost belongs in the care planThe number of paid plugins and their renewal datesSee care plan economics

    A Five-Plugin Audit You Can Do This Week

    Pick five premium plugins across your busiest client sites. For each, record:

    1. The vendor and the account that owns the license. Is it your account, the client’s, or a former developer’s?
    2. The expiry date, or “not found”.
    3. The date of the last update the site actually received.
    4. Whether the plugin is active and whether anything depends on it.
    5. Who gets the renewal email, and whether that address still works.

    Then pick one outcome per plugin: renew now, move the license to the right owner, replace the plugin, leave it with a dated note, or confirm the license state with the vendor.

    The fifth question is the one that bites. A renewal notice that goes to a former contractor’s inbox is how a license lapses without anyone deciding to let it. Writing the owner and the renewal date into the maintenance contract is a small change that closes it.

    If A License Has Already Lapsed

    Do these in order:

    1. Take a backup, and make sure it restores.
    2. Check whether the vendor has published updates since the license ended.
    3. Renew, or schedule the plugin’s replacement.
    4. After renewing, re-read the Updates screen and confirm the offer comes back.
    5. Test the update on a copy before applying it live.

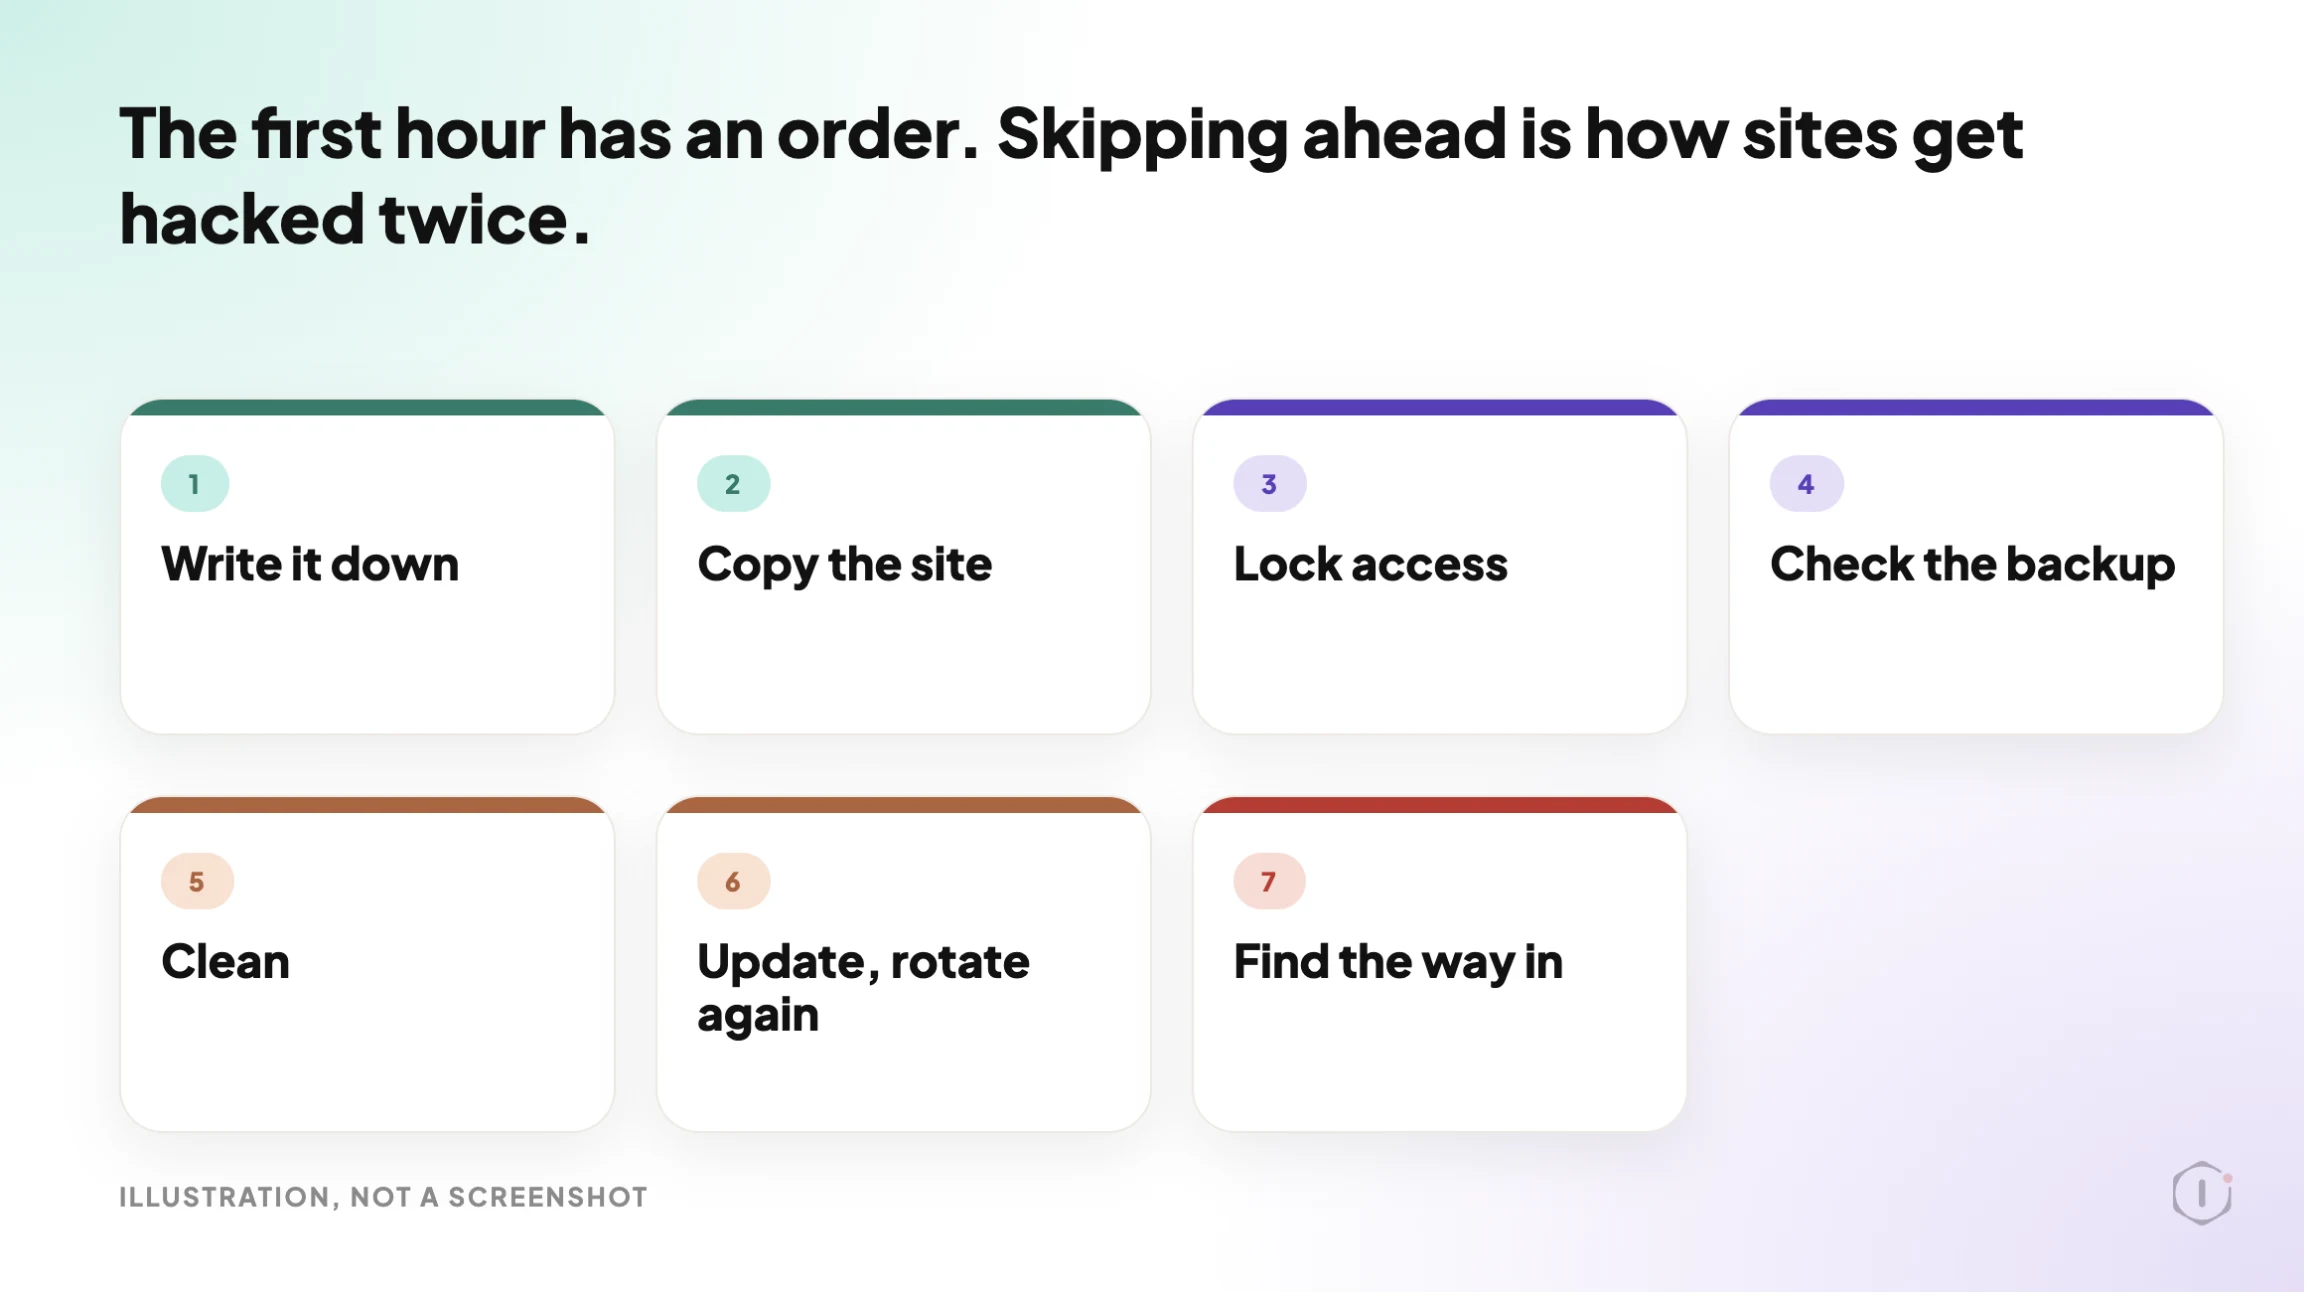
    If an update goes wrong, a clear undo is what matters. Our post on what an automatic rollback really reverses is a good test of any undo claim. If you suspect a plugin has already been used against the site, start with the first hour after a hack and ignore this post.

    Two Outside Views

    A tutorial and a forum thread. Neither is an endorsement.

    Presslyte’s tutorial on updating WordPress plugins safely walks through a five-step routine: back up, review, update one plugin, check the site and repeat. It also says that if the update source or support status is unclear, you should stop and verify it before going on.

    A beginner tutorial on updating WordPress plugins safely: back up, review, update one plugin, check the site and repeat.

    Presslyte, “How to Update WordPress Plugins Safely” on YouTube, 2 Sep 2026

    On Reddit, an r/Wordpress thread asks whether people wait for Black Friday to buy yearly plugin licenses, and the replies talk about monthly versus annual plans, lifetime deals and whether a first-year discount is worth it. It is a useful reminder that every yearly license is also a renewal date someone has to own.

    “A lot of plugin vendors discount only the first term, and year two renews at full price.”

    r/Wordpress, “Are you waiting for BlackFriday/CyberMonday with plugin purchases?”, September 2026

    Where Protuno Fits

    In the Protuno dashboard, Premium License Expiry sits with the Care playbooks. It is a Beta playbook that only reads, so it does not change a plugin, renew a license or print a key. It needs the Protuno plugin on the site first, and on the one connected site in the dashboard it is not switched on, so there is no run to show here.

    It does not decide whether to renew, and it does not replace asking the vendor. If a site is behind on core, update it first: WordPress 7.1.3, a security and maintenance release, came out on 6 October 2026.

    Sources And Further Reading

    The Point

    A lapsed license does not announce itself. The plugin keeps working, and the updates stop.

    List every plugin, find where each one gets its updates, read the license records, and write unknown when you cannot tell.

    Which premium plugin on your busiest site has no renewal date written down anywhere?

  • WordPress 404 Errors: Which Ones Actually Cost You

    WordPress 404 Errors: Which Ones Actually Cost You

    A client opens a plugin dashboard and sees 4,000 logged 404 errors. They forward the screenshot with one line: “is this bad?”

    The honest answer is that the number on its own means almost nothing. A 404 log is not a defect list. It is a list of requests, and requests come from everywhere: a scanner probing for /wp-admin/setup-config.php, a dead link in a five year old forum post, a typo in an email newsletter, a page the client deleted on purpose last week, and one URL that used to receive real visitors every day.

    Those five things have nothing in common except a status code.

    Short answer: sort 404 errors by what they were connected to, not by how many there are. A URL that had organic traffic, has an external backlink, or is still linked from your own navigation costs you something real and needs a decision. A URL that only ever appeared in bot logs costs you nothing and should stay a 404. Redirect the first group to the closest genuine equivalent, leave the second group alone, and use 410 for pages you deliberately removed.

    What this post is, and is not: this is a triage routine for a 404 log you already have, using data from your own analytics, your own Search Console property and a crawl of your own site. It is not a claim that fixing 404s raises rankings on its own, and it does not measure how any search engine weighs a 404 against a 410.

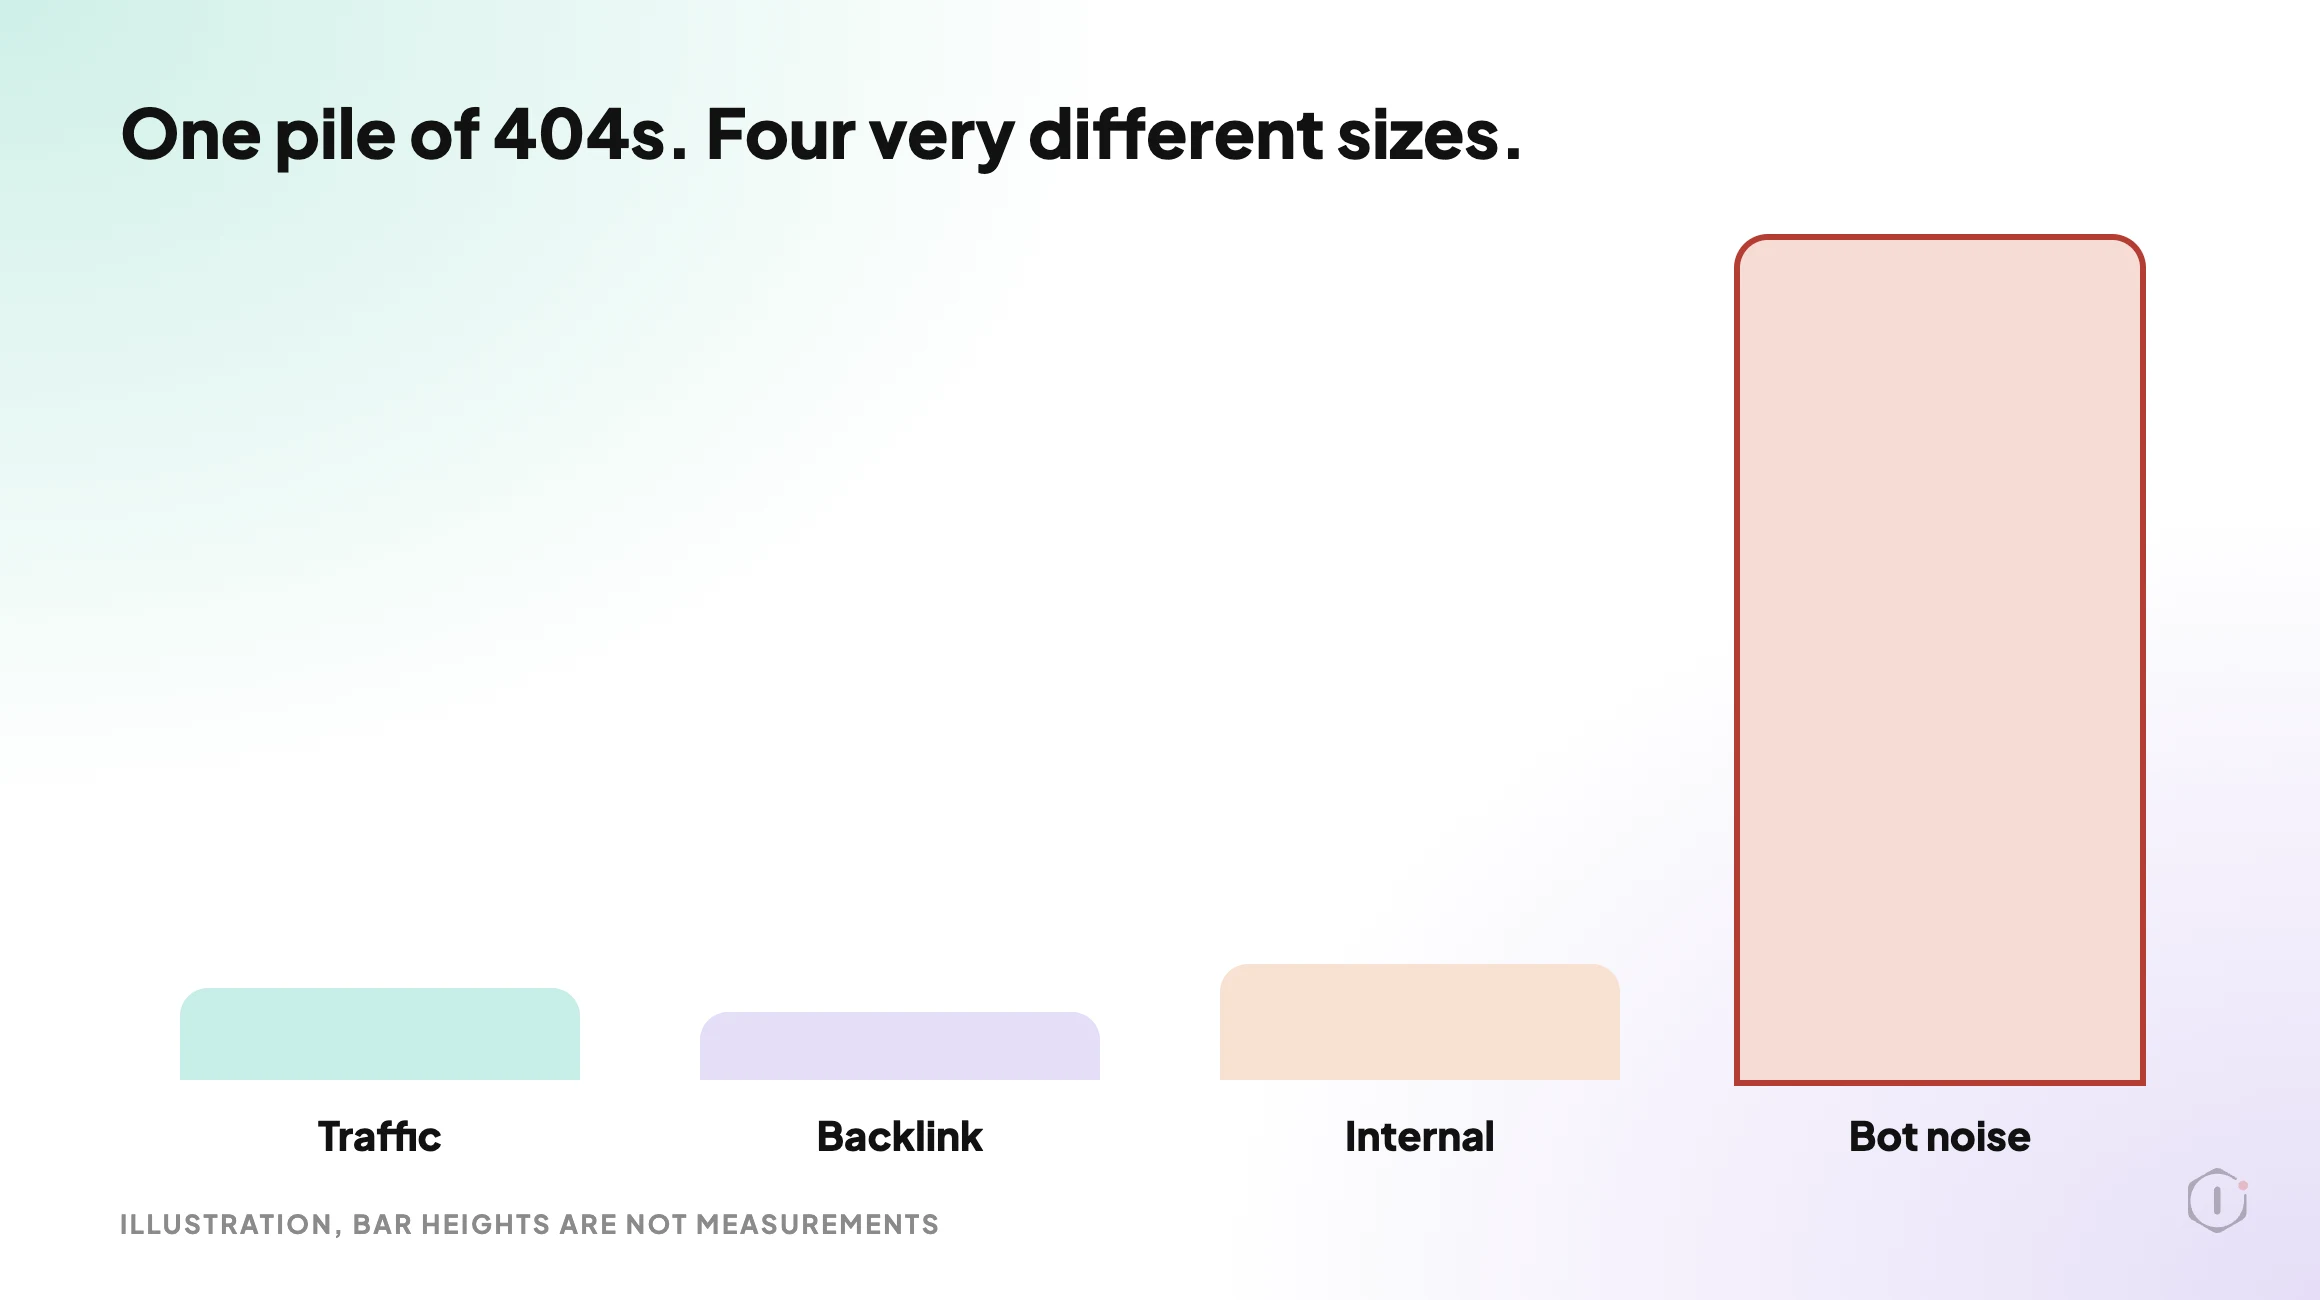
    Diagram sorting a pile of WordPress 404 errors into four buckets, with bot noise as the largest group by a wide margin.
    Illustration. The pile is big. The part that costs you anything usually is not.

    Why The Count Is The Wrong Number

    A 404 is the correct response to a request for something that does not exist. The status code is doing its job. Treating every one as a defect means treating your server’s correct behaviour as a bug.

    The count feels alarming because 404 logging plugins record everything, including traffic that was never going to be a visitor. Vulnerability scanners walk a list of known paths against every WordPress site they can reach. A site with no inbound links at all will still pick up thousands of 404s a month from that alone.

    Compare two lines from the same log:

    /wp-content/plugins/revslider/temp/update_extract/

    /2024/03/our-pricing-changed/

    The first is a scanner. Nobody linked to it, no human requested it, and redirecting it only adds a rule your server evaluates on every request from then on.

    The second was a real page. If it had traffic or links, it is losing both right now. That is one of the four thousand, and it is the whole job.

    Part of this is already handled for you. WordPress tries to guess the intended address for a missing URL by matching the slug, which is what redirect_guess_404_permalink() does. So a lazy typo in a post slug can resolve without a rule. A deleted page, a changed permalink structure or a renamed category usually cannot, and those are the ones to look for.

    The Four Buckets

    Every 404 in your log belongs in one of four buckets. Sort in this order and stop as soon as a URL qualifies.

    BucketTestCost if ignoredAction
    Had organic trafficThe URL appears in analytics or Search Console data for the period before it brokeLost sessions and any conversions on that pathRedirect to the closest genuine equivalent
    Has external backlinksAnother site links to itLost referral traffic and a wasted inbound linkRedirect, even if traffic was low
    Linked internallyYour own pages, menus, sitemap or templates still point at itVisitors hit a dead end and crawlers waste requestsFix the link at the source, then decide on a redirect
    Bot noiseNone of the above applyNothingLeave it as a 404

    The order stops you overthinking. A URL with a backlink gets a redirect whether or not it ever had traffic, because the link is an asset you already own. A URL with no traffic, no links and no internal references is not a problem to solve, however many times it appears.

    The fourth bucket will usually be the overwhelming majority. That is the expected result, not a sign you checked wrong.

    Getting The Data For Each Test

    Each bucket needs a different source, and none of them is the 404 plugin itself.

    Traffic history. Your analytics property holds the before picture. Export the landing pages that received organic sessions over a window long enough to cover the period before the URL broke, then intersect that list with your 404 list. Anything in both is bucket one. If analytics was reinstalled or duplicated at some point, the numbers for that period may be wrong in ways that are easy to miss, which the duplicate Google Analytics tag post covers.

    Backlinks. This is the one piece you cannot derive from your own site. You need a backlink source, and the result will be incomplete whichever one you use, because no index sees every link. Treat the result as a floor, not a total.

    Internal links. This one you can answer completely, and you should, because it is the only bucket that is entirely your own doing. Crawl your own site and collect every internal link that returns a 404. The WordPress crawl audit post is about what only a crawler can find, which is exactly this job. A crawl also exposes the opposite failure, pages that exist but nothing links to, which the orphan pages post covers.

    Sitemap entries. A 404 listed in your sitemap is a specific and avoidable mistake, because you are actively submitting a dead URL for crawling. Pull the sitemap, request each URL and flag every non-200 response. The sitemap audit post has the commands.

    The links you control are the easy half of this. The broken link checker post explains why a plain 404 check also misses soft 404s and redirect chains, so this post leaves those two alone.

    410 Versus 301, And When To Use Neither

    Once a URL is in a bucket you have three options, and the choice is less about search engines than most arguments about it suggest.

    ResponseMeansUse it when
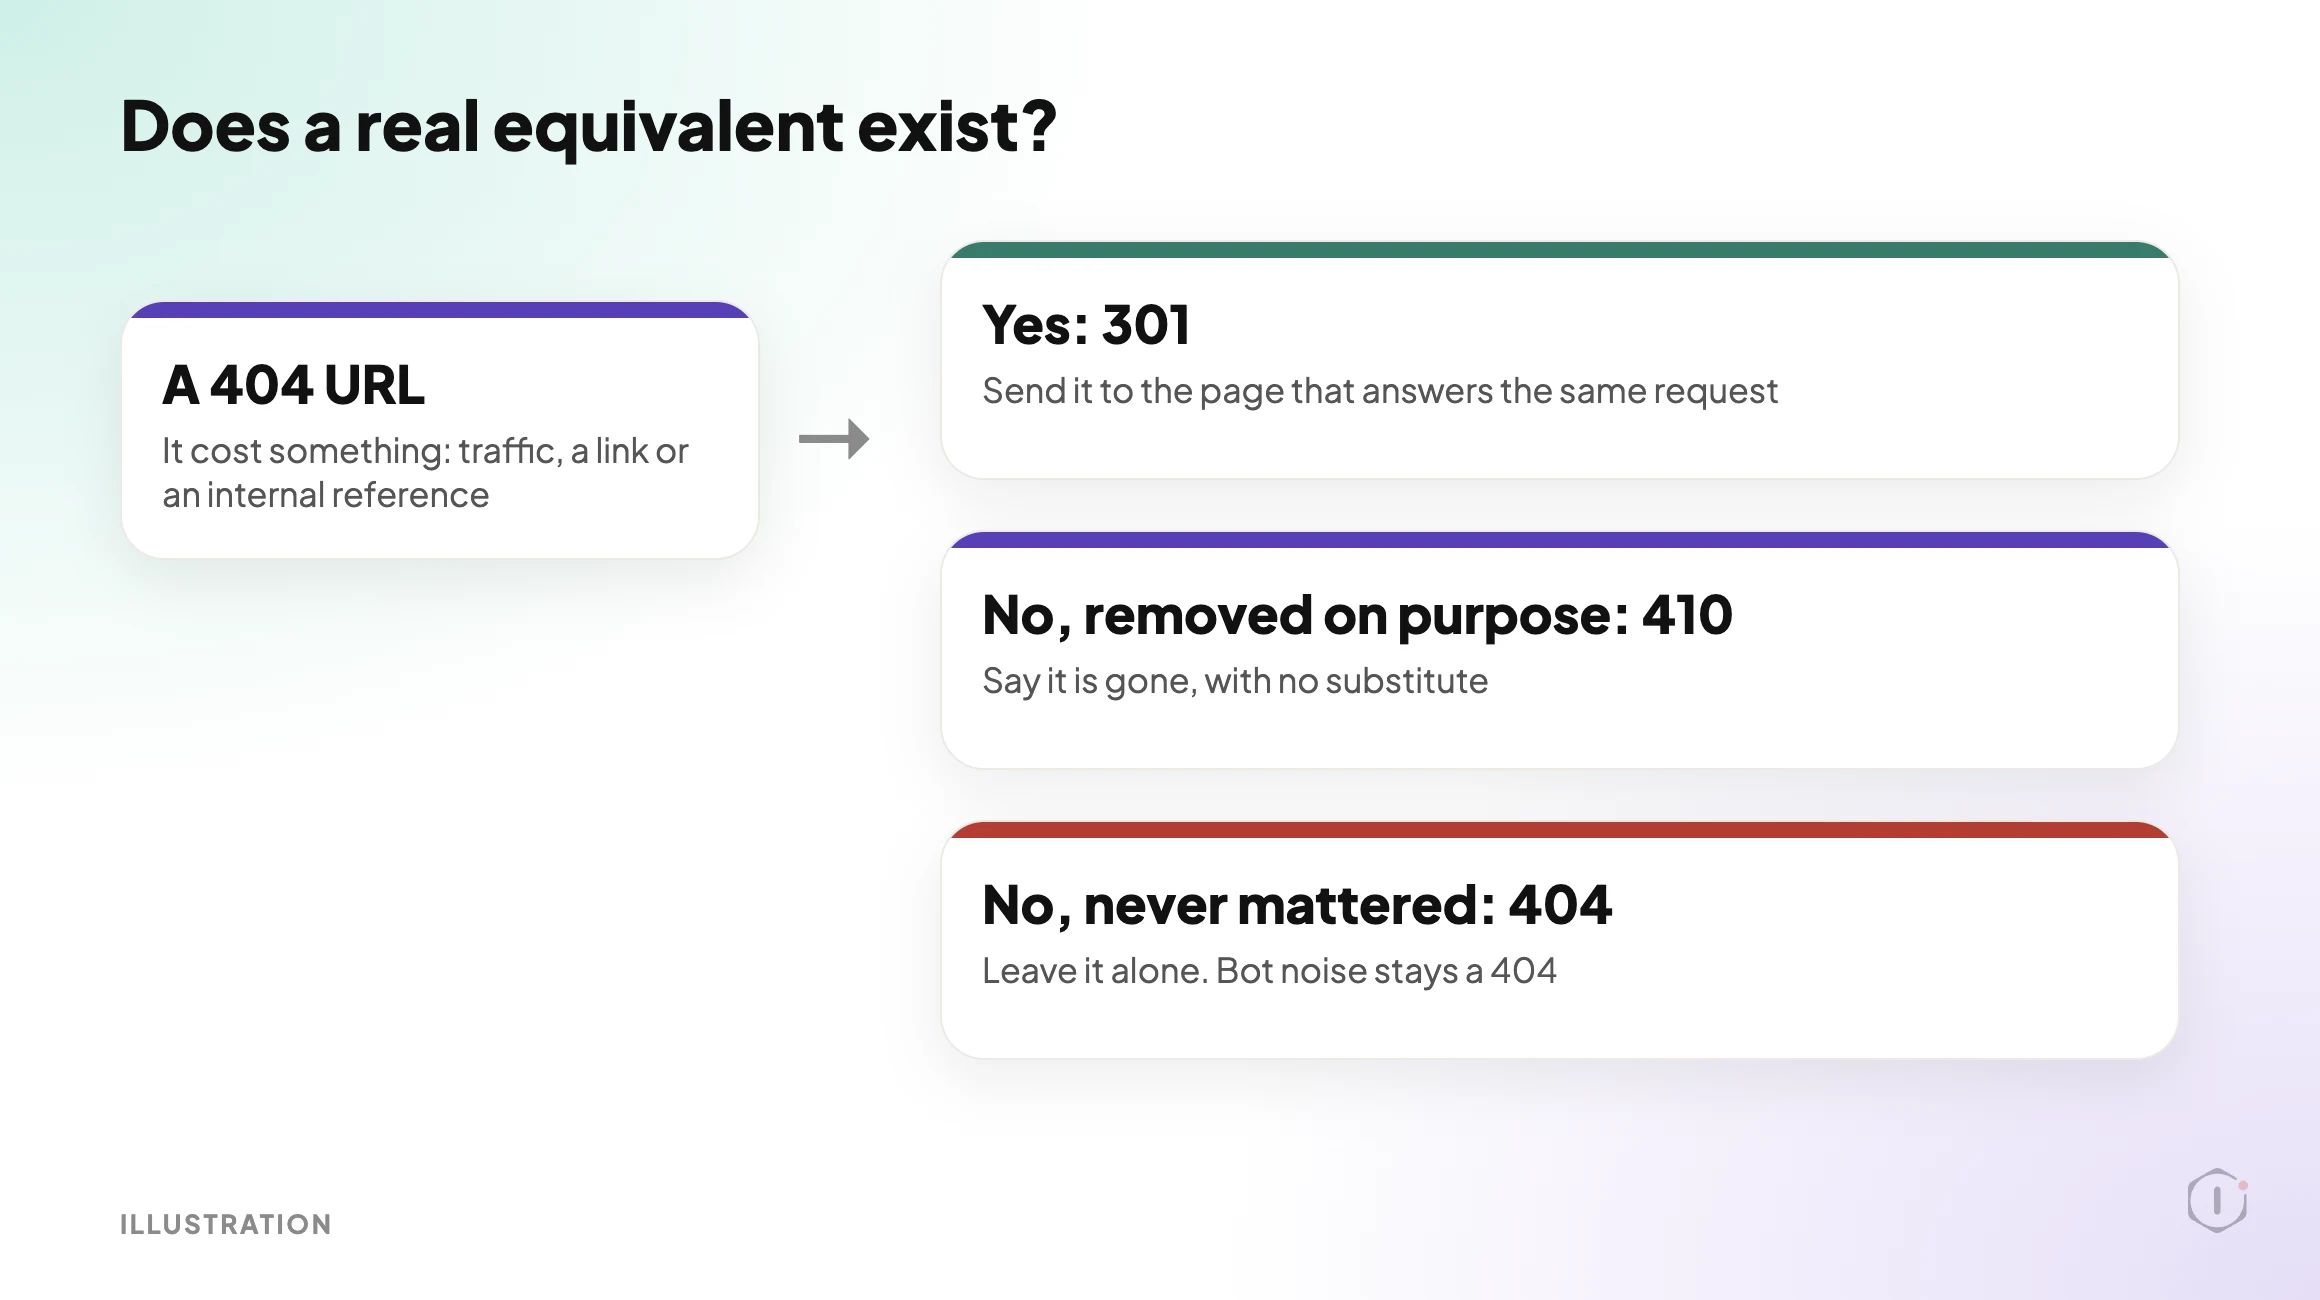
    301This has permanently moved hereA genuine equivalent exists for what the visitor wanted
    410This is gone on purpose and is not coming backYou deliberately removed the page and there is no equivalent
    404This does not existEverything else, including all bot noise

    The rule that keeps this clean: a 301 is a promise that the destination answers the request the visitor made. Redirecting a deleted product page to your homepage does not do that. The visitor wanted a product and got a homepage, which is a dead end wearing a 200 status code. It is worse than the 404, because the 404 at least told the truth. Google’s own 301 redirect guidance is about pointing to the new location of the same content.

    So the test for a redirect is not “do I have somewhere to send this”. It is “does that destination give the visitor the thing they came for”. If no page does, use 410 for deliberate removals and leave the rest as 404.

    The MDN reference for 410 Gone describes it as a deliberate, permanent removal, and suggests 404 when you do not know whether the removal is permanent. That is a good rule of thumb. A 410 is a cleaner statement than a 404 that could be a temporary failure. It is not required, and a site that only ever uses 404 is not broken.

    Decision diagram choosing between a 301 redirect, a 410 response and leaving a WordPress URL as a 404.
    Illustration. Three outcomes. Most URLs take the third branch.

    One habit to avoid: mass redirecting everything in your log to a single destination. It turns a readable report into noise, adds rules that run on every request, and when you later redirect something properly you risk building a chain of hops instead of a single one.

    A walkthrough of the Redirection plugin: installing it, setting up 301 redirects and tracking 404s in its error log.

    JOSHUA, “How to Fix 404 Errors Using the Redirection WordPress Plugin (Easy Guide)” on YouTube, 10 Jul 2026

    “…I am thinking of changing the response to “410 Gone” to see if they go away permanently.”

    r/TechSEO, “404 Not Found or 410 Gone?”, October 2026

    Both are about the same decision. The video covers the mechanics of setting a redirect up in a plugin, and it does not tell you which URLs deserve one. The thread is a working question about whether answering 410 clears long-gone URLs out of Search Console, and the line quoted above is the one this post answers: did the URL ever cost anything, and is there a real equivalent?

    The 404 Log Is A Security Signal Too

    Scanner paths are not an SEO problem. They are still information.

    A sharp rise in requests for paths that never existed on your site means someone is probing. You do not need to act on each line, but you should record the rise and compare it with what changed that week. If it lines up with a plugin install or a published vulnerability, that is worth a look. The security monitoring playbook post is the place to start for that side of it.

    Keep the two uses apart. If scanner volume and real regressions feed the same alert, the volume will bury the regression every time.

    Monitoring It Without Drowning In It

    Triage once and you have cleaned up a backlog. The useful version catches the next one within days instead of at the next audit.

    Two signals are worth watching, and they are not the same signal.

    The first is a URL that used to return 200 and now returns 404. That is a regression, and it is the only 404 event that deserves an alert. You detect it by holding a list of your own known-good URLs and requesting them on a schedule, not by watching the log.

    The second is a rise in 404s against URLs that never existed. That is scanner activity, covered above.

    A small test you can run today:

    • Export the URLs from your sitemap and from your main navigation.
    • Request each one and record the status code, the final URL after redirects and the date.
    • Re-run it after every core, theme or plugin update, and after any permalink change.
    • Treat any URL that moved from 200 to 404 as an incident, and everything else as housekeeping.
    # status and final URL for one address
    curl -s -o /dev/null -L -w "%{http_code} %{url_effective}\n" https://example.com/pricing/

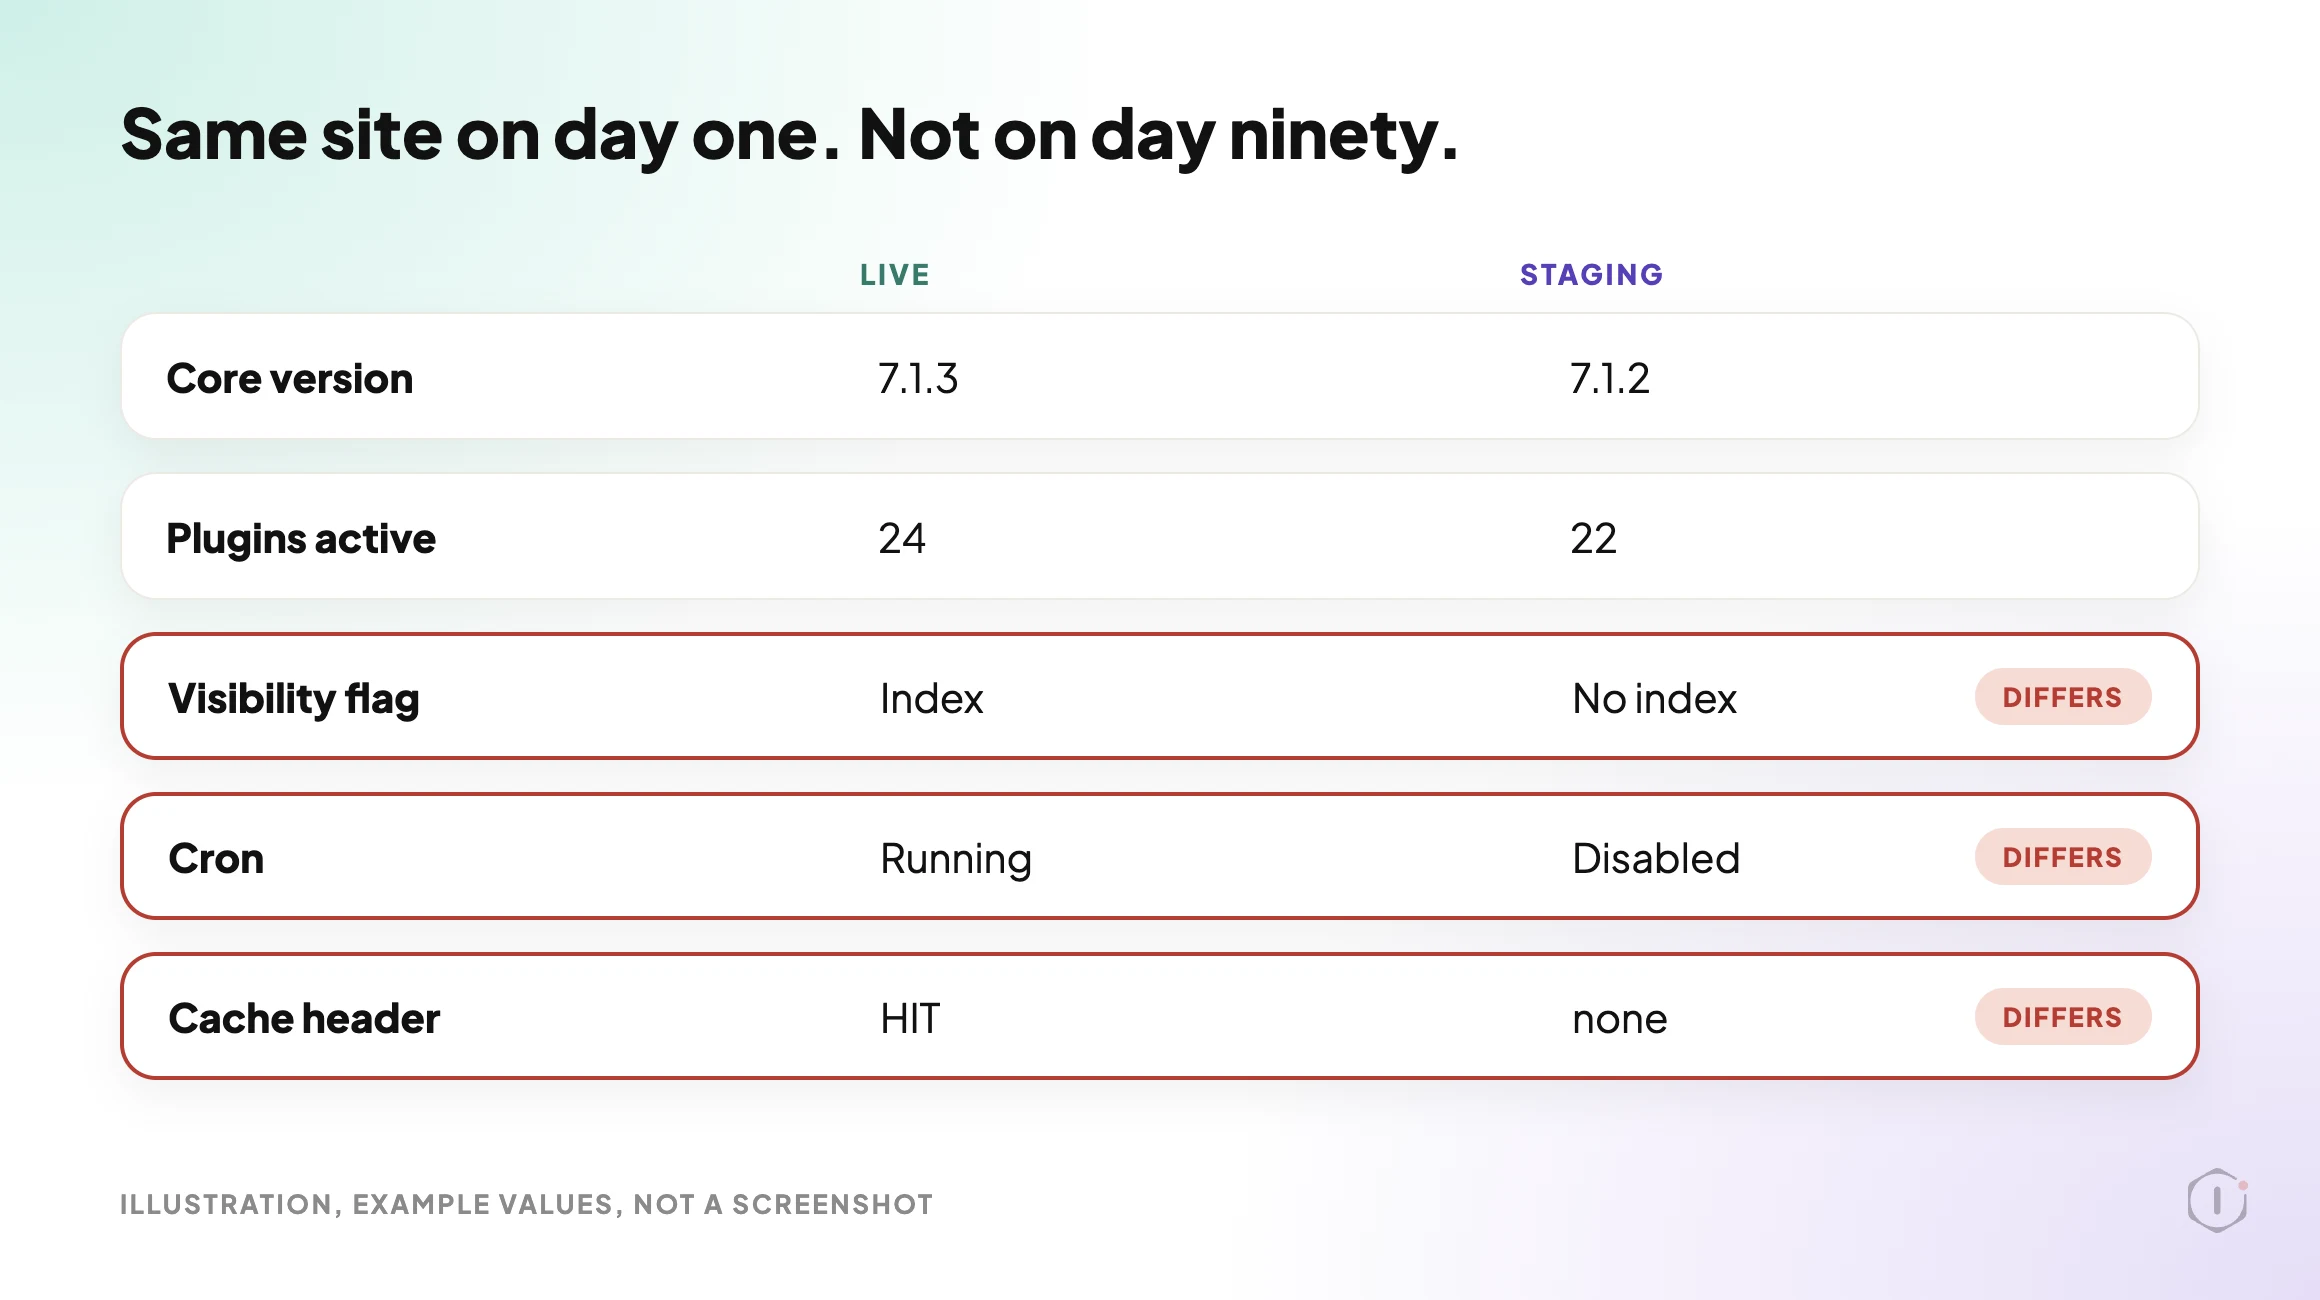
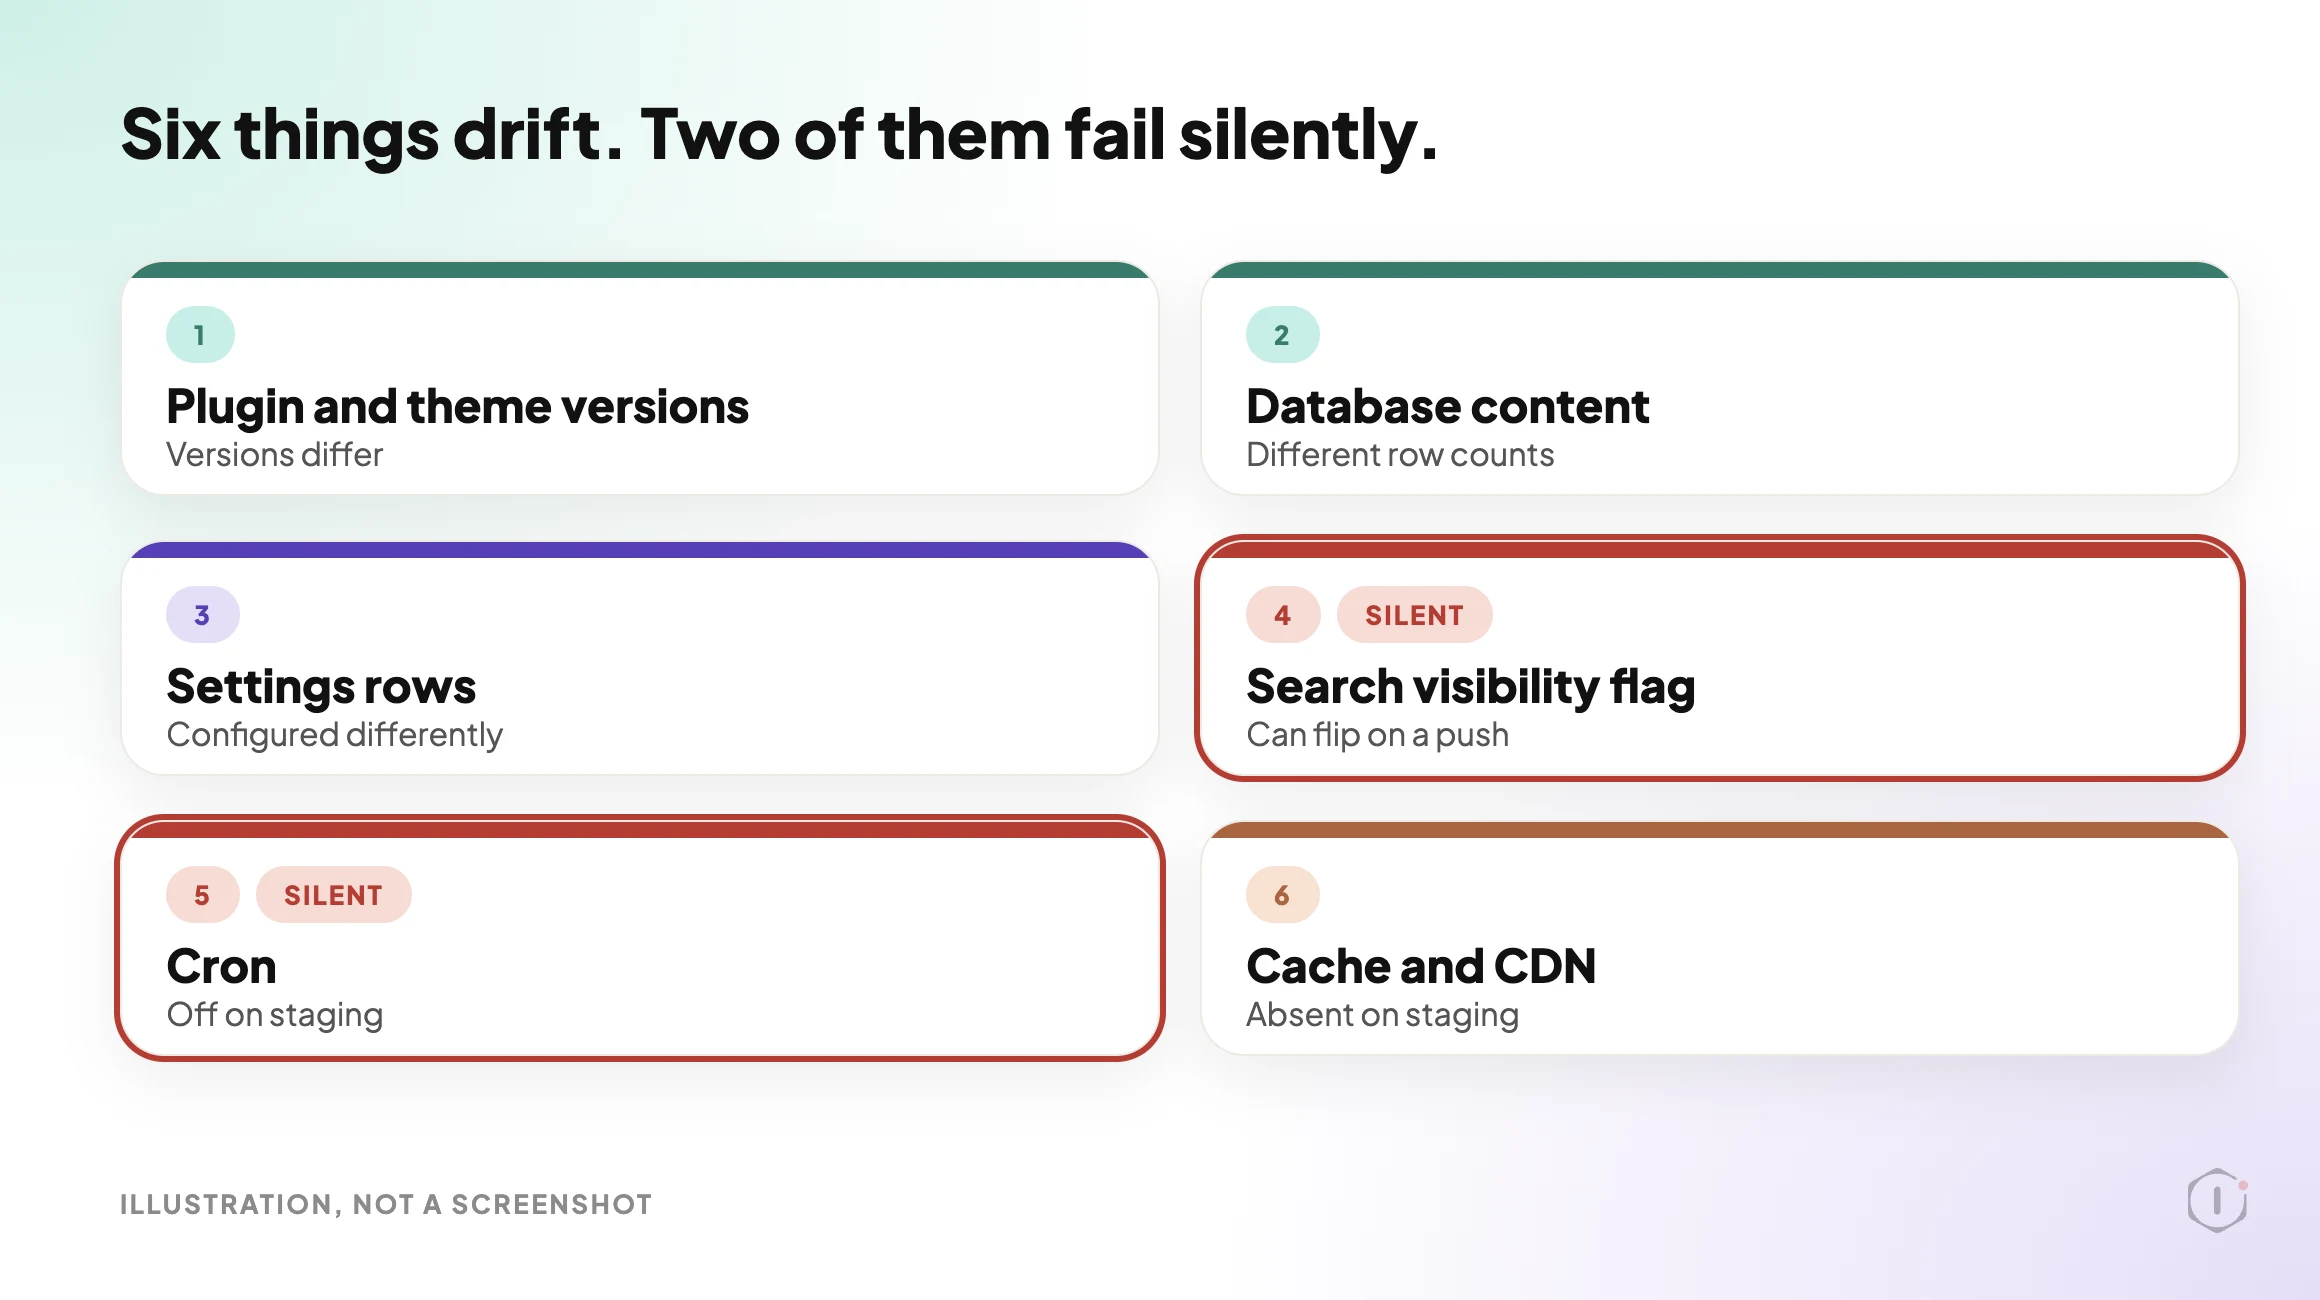
    Staging drift is a common cause of the 200 to 404 jump, because a permalink or plugin setting that differs between staging and live changes which URLs exist.

    What 404 Triage Does Not Solve

    Sorting your 404s is housekeeping with a clear payoff. It is not an SEO strategy, and it proves little on its own.

    It cannot tell you whether:

    • the page that was removed should have been removed, which is a content decision nobody can make from a status code;
    • the redirect you added serves the visitor’s intent, since a 301 to a loosely related page still fails the person who clicked;
    • a ranking change followed the fix, because too many other things move at once to attribute it;
    • your backlink data is complete, since every index is partial;
    • the traffic a broken URL used to get would return if you restored it, as demand may simply have moved on; or
    • a URL returning 200 is actually working, because a page that renders nothing but returns 200 passes every status check you run.

    That last one is the real gap. Every test here is built on the status code. Catching a page that answers 200 and shows nothing needs a check that looks at what the page contains. Google describes these as soft 404s in its HTTP status code documentation.

    The other limit is scope. This routine is about URLs that are gone. It says nothing about URLs that exist, are reachable and are still not doing anything useful.

    Fixing In The Right Order

    1. Take a restore point first, so a bad redirect rule can be undone.
    2. Fix internal links at the source. A redirect that hides your own broken link is a patch, not a fix.
    3. Redirect the traffic and backlink URLs one to one, each to its closest genuine equivalent.
    4. Remove dead URLs from the sitemap.
    5. Mark deliberate removals as 410.
    6. Re-request every changed URL and confirm one hop, then re-run the known-good list.

    Sources And Further Reading

    For the wider technical review this belongs to, see the Technical SEO Audit playbook post and the playbooks page.

    How Many Of Your Sites Have A 404 Log Nobody Has Read?

    Most agencies have a 404 log on every site and a triage habit on none of them, because the counts are large and the signal is buried.

    Pick three sites. For each one, pull the unique 404 URLs, intersect them with analytics and a crawl, and write down two numbers: how many had any cost attached, and how many were scanner noise.

    So, on the sites you run: when a client next asks whether four thousand 404s is bad, can you answer with the handful that actually cost them something, or only with the four thousand?

  • WordPress On-Page SEO Checklist, Step By Step

    WordPress On-Page SEO Checklist, Step By Step

    A green score is an opinion about one version of a post.

    It is not a reading of the page a visitor or a crawler actually receives.

    Short answer: Check one post at a time, in a fixed order. Find out which plugin owns the title and description. Read what is stored. Read what the live page serves. Compare both against a short list of limits: title, description, one H1, alt text, internal links and schema. Write each fix as a before and after. Change only what you can undo, then read it back. That is a WordPress on-page SEO checklist you can run by hand, and it is the same order the AI SEO Optimiser playbook in the Protuno dashboard follows.

    What this post is, and is not: A practical checklist for one post at a time, with the limits we use and the reasons for them. It is not keyword research, not a ranking promise and not a result from a real run: no playbook was run for this post, and every visual is a labelled illustration. The step names and rules come from the playbook as the Protuno dashboard shows it. The playbook is Beta.

    An audit tells you what is wrong. A diff tells you exactly what changed.

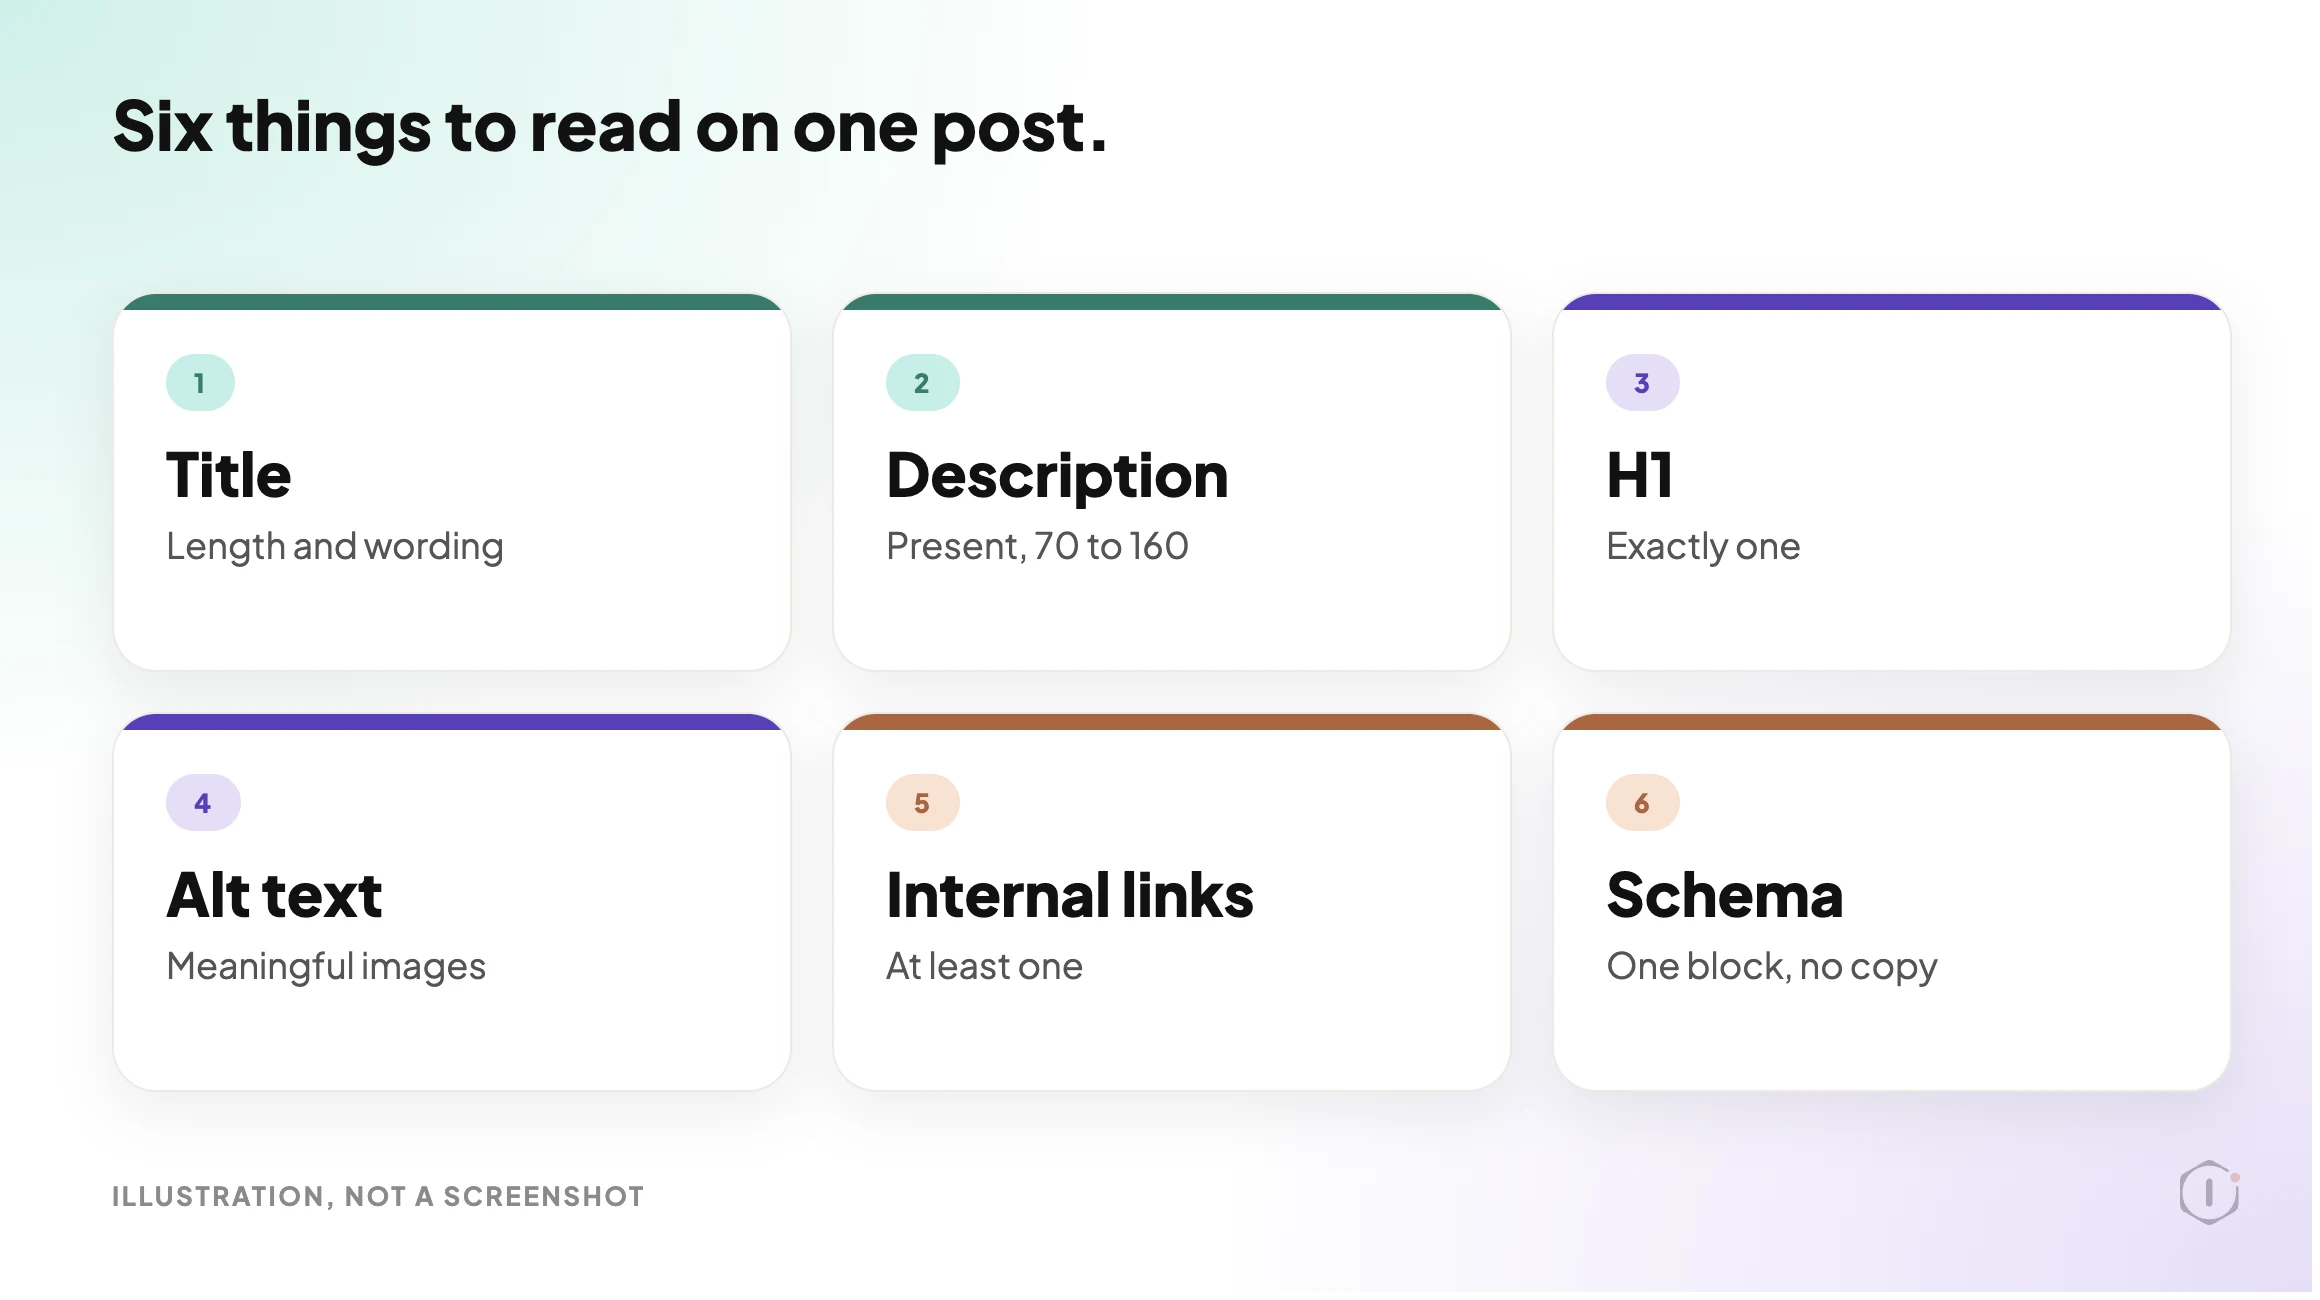
    Illustration of the six on-page checks on one WordPress post: title, description, H1, image alt text, internal links and schema
    Six things to read on one post. Everything else is a different job.

    Why A Green Score Is Not A Checklist

    An editor score is built from the post as you are writing it. The page that goes out is built later, by your theme, your plugins and your cache.

    That gap is where on-page problems hide. A theme can print its own H1. A second plugin can output a different title tag. A caching layer can serve last week’s version. The score cannot see any of that.

    Google adds another layer. Its documentation says title links are created automatically from several sources: the title element, the main visual title, heading elements such as the H1, og:title tags, anchor text and more. The title you type is one input, not the verdict.

    Snippets work the same way. Google says they are primarily created from the page content, and that it sometimes uses the meta description when it describes the page better. So a description is a pitch you offer, not a result you control.

    A good check looks at what is served, and says what it cannot see.

    Three Places The Same Post Lives

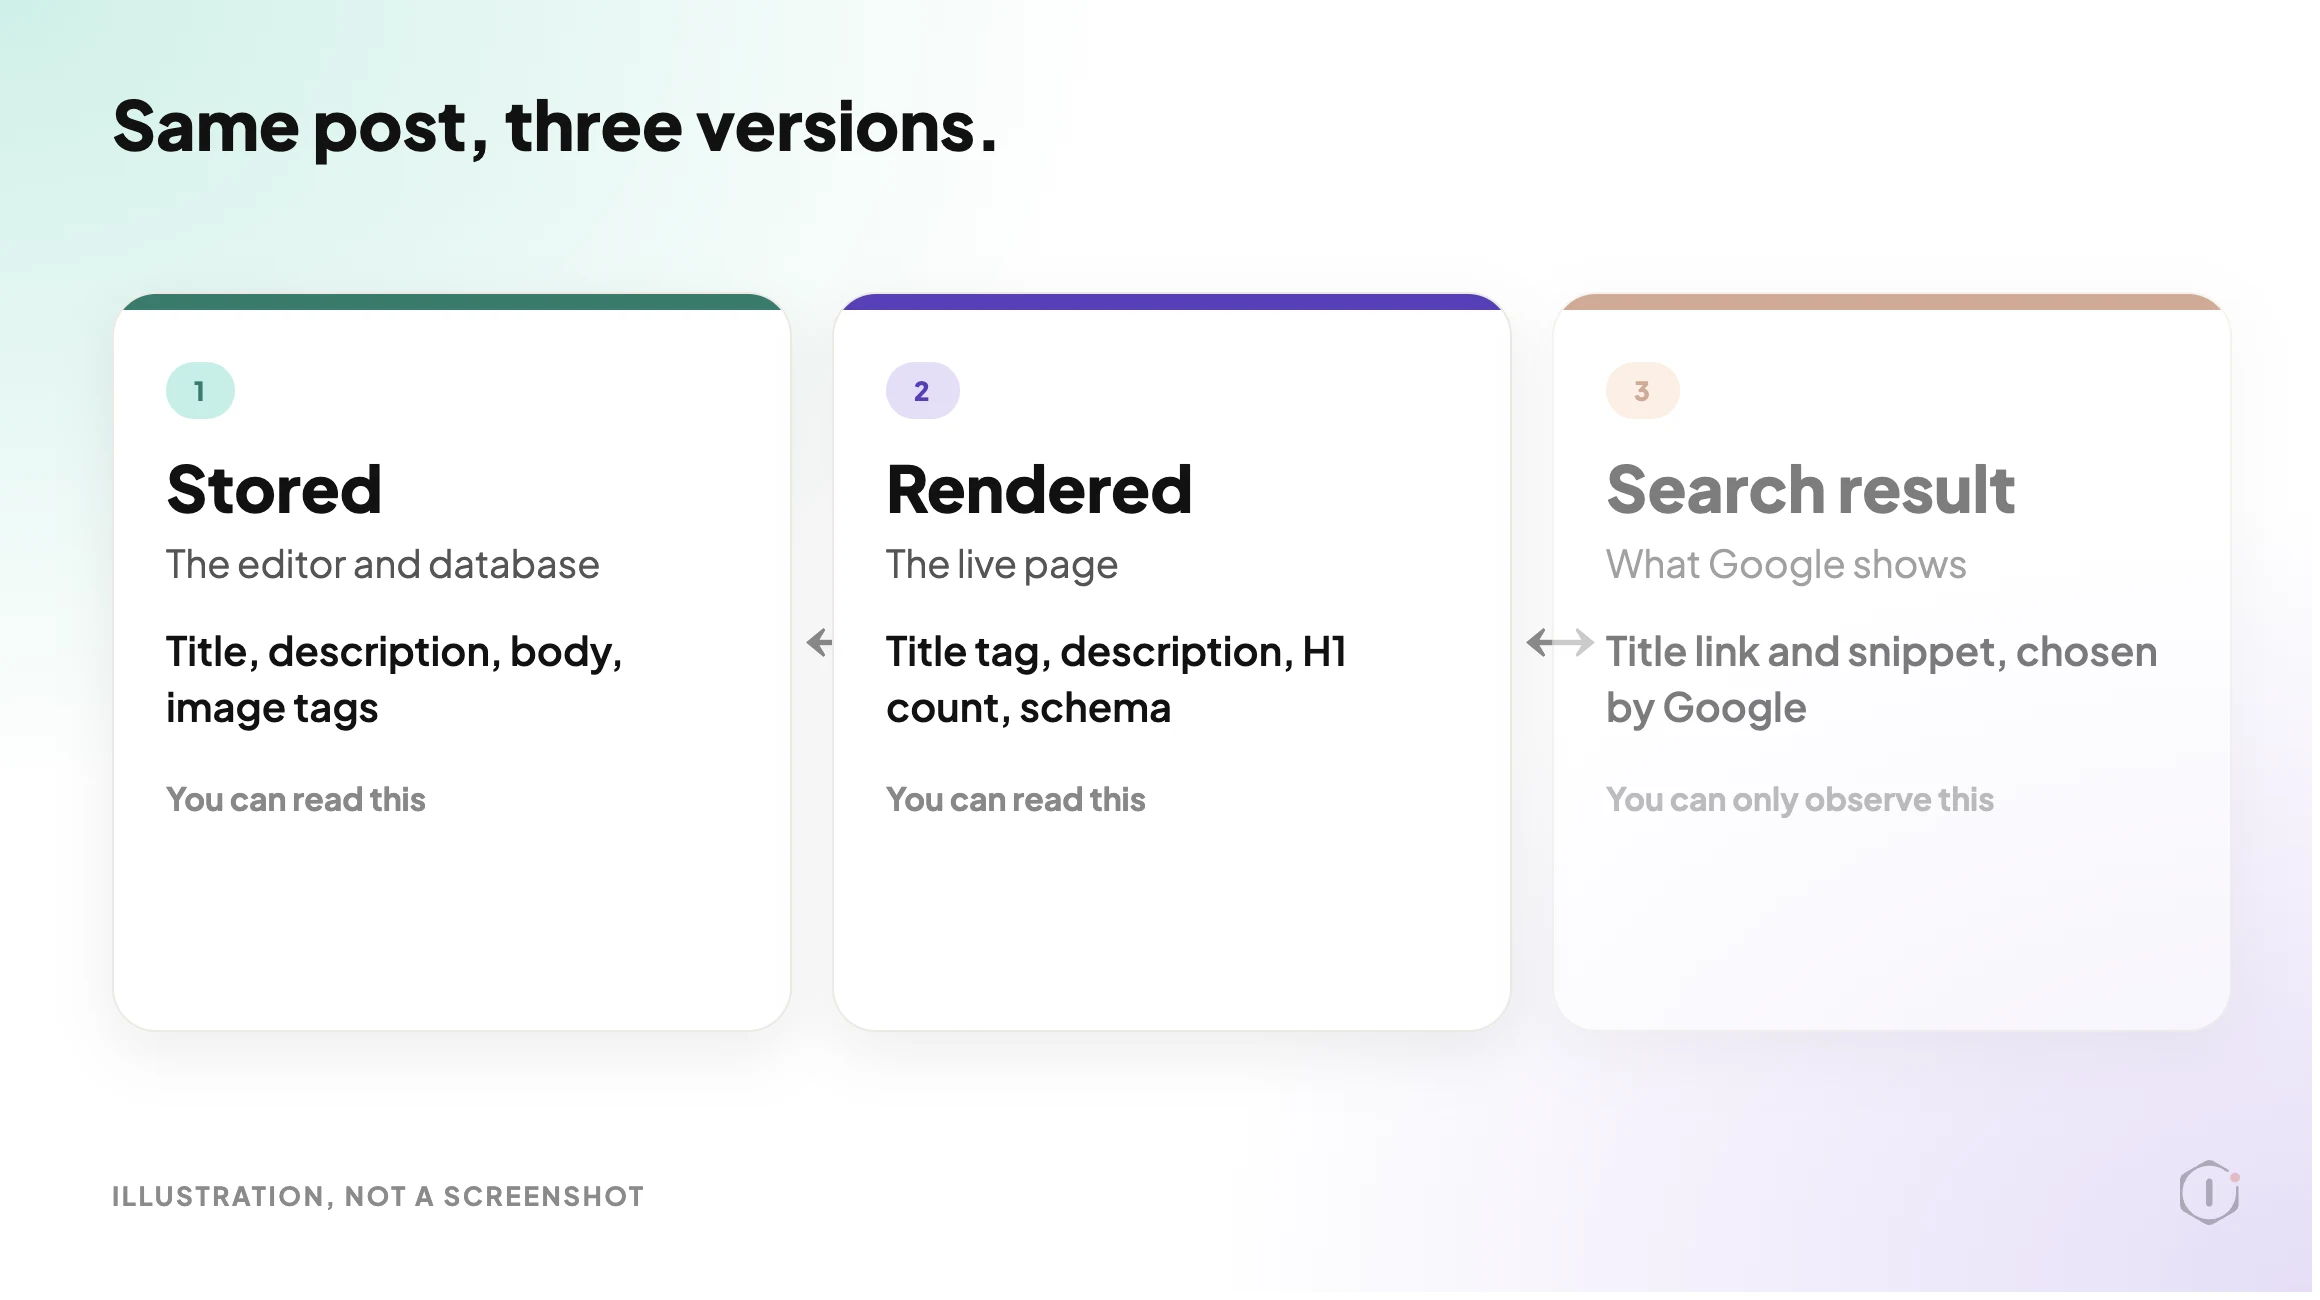
    ViewWhat it tells youWhat it cannot prove alone
    Stored (the database and the editor)The title, description and body as saved, plus the image tags in the bodyWhether a theme or plugin changes any of it before it is served
    Rendered (the live page)The title tag, description, H1 count and schema a crawler really receivesWhether you saved what you meant to, or whether a cache is stale
    Search result (Google)The title link and snippet Google chose to showAnything about your page. Google decides this, and it can differ by query

    The first two you can check today. The third you can only observe, and it changes after Google recrawls the page.

    Illustration of one WordPress post seen three ways: stored in the editor, rendered on the live page, and shown as a search result
    Same post, three versions. A good check compares the first two.

    A Small Test You Can Run Today

    Pick one published post. Write down:

    • The post URL and which SEO plugin is active (Yoast, Rank Math, All in One SEO or none).
    • The title as served, and how many characters it is.
    • The meta description as served, and how many characters it is.
    • How many H1 tags the live page contains.
    • Which images have no alt text, or an empty one.
    • How many links in the body point to your own site.
    • Whether the page already has a JSON-LD schema block, and which plugin prints it.

    A rough way to read the served page from a terminal:

    URL="https://example.com/your-post/"
    curl -s "$URL" -o post.html
    grep -o -i '<title>[^<]*' post.html
    grep -o -i '<meta name="description"[^>]*' post.html
    grep -o -i '<h1' post.html | wc -l
    grep -o -i '<img[^>]*>' post.html | grep -v -i 'alt="[^"]'
    grep -o 'application/ld+json' post.html | wc -l

    These lines read the served HTML only. A tag that a script adds in the browser will not show up, and the attribute order in the description tag varies, so if nothing prints, open view-source and look. The image line lists every image with a missing or empty alt, which includes decorative ones. Treat the output as a prompt to look, not as a score.

    The Playbook, Step By Step

    AI SEO Optimiser is a Protuno SEO playbook. In the Protuno dashboard it carries a Beta label, runs eleven steps in a fixed order and can change a site: it rewrites one post’s content and SEO fields. The public playbooks page lists a playbook with the same purpose under the name Page Optimise, described there in five steps. This post follows the dashboard’s names and eleven steps. Check which version your account shows before you rely on either.

    #StepWhat it does
    1Resolve Target And GatewayReads one setting, the target post ID. If nothing is set it stops. It never picks a post for itself. Confirms the post exists and is a published post or page
    2Detect SEO FrameworkLooks for Yoast, then Rank Math, then All in One SEO. Yoast and Rank Math have writable title and description fields. With All in One SEO or no plugin, those two are deferred
    3Read On Page StateReads the stored title and length, description and length, H1 count, heading outline, images without alt, internal link count and any inline JSON-LD
    4Read The Live PageFetches the rendered page to see the served title, description, H1 count and JSON-LD. If it cannot, it says so. Core Web Vitals are not available here
    5Keyword And SERP ContextOptional. Only if a target keyword is set, it looks up the top ten results for title and snippet context. Otherwise it skips
    6Diagnose On Page SEOTurns the reads into findings tagged by severity
    7Compose Proposed FixesWrites the exact title, description and image alt text, and an Article schema block only if none exists. Every value is checked against length limits first
    8SEO Diff Approval GateBuilds before, after and reason rows. Drops anything out of bounds or unverifiable
    9SEO Safety SnapshotRecords the current title, description and a hash of the body in a backup field before anything is overwritten
    10Apply SEO FixesWrites to the one target post only. The body goes through a recorded content update. Title and description use a recorded meta write when the site offers one
    11Recheck And SEO ReportReads every changed field back, checks the rendered page, and reports before and after with the exact undo

    The order is the safety. Nothing is written before a snapshot, and nothing is called done before it is read back.

    A 31-second walk-through of the eleven steps. All example values are illustrations, not a real run.

    Read The Gate Carefully

    Step 8 is named an approval gate. The instructions for that step say plainly that this playbook has no interactive human step, and that the steps after it, the snapshot, the recorded write and the read-back, stand in for one. The public Page Optimise listing describes applying on approval. Those are two different promises. Before you switch a playbook that writes to a client post, find out which one your version makes, and decide whether you are comfortable with it.

    The Limits It Checks Against

    FieldWhat it flagsSeverity
    Meta descriptionMissingHigh (low if the site has no SEO plugin, since there is nowhere to store one)
    Meta descriptionOver 160 characters, or 1 to 69Medium for too long, low for too short
    TitleOver 60 charactersMedium
    TitleUnder 15 charactersLow
    H1None, or more than oneMedium
    ImagesAny inline image without alt textMedium
    Internal linksNone in the bodyLow
    SchemaNever adds a block if one already exists, inline or plugin-renderedNot a finding

    These are the playbook’s bounds, not Google’s rules. Google’s own pages say there is no limit on how long a title element or a meta description can be, and that Google shortens what it shows to fit the device width. Treat 60 and 160 as a practical editing target, not as a ranking threshold.

    One more limit matters. The image rule counts an image with an empty alt as missing. The W3C accessibility guidance says the opposite for purely decorative images: they should have an empty alt on purpose. A sweep like this will flag them anyway, so a human has to sort real gaps from decoration. Our alt text audit shows how easily an alt count can mislead.

    What An On-Page Check Does Not Solve

    • Whether anyone searches for the topic. Nothing here does keyword research or judges search intent.
    • Whether the content is good. A tidy title on a thin page is still a thin page.
    • Rankings. No set of fixes to one post guarantees a position. Core Web Vitals are not available to this playbook either.
    • The H1 and the links. The playbook reports them and leaves the change to a person. Restructuring a heading or adding links needs judgement.
    • Image alt text that lives on the media record instead of in the post. It is reported, not written.
    • The rest of the site. It acts on one post. For site-wide patterns, the technical SEO audit reads the whole site and changes nothing.

    Questions To Ask Your Current Tooling

    • Does it read the live page, or only the editor?
    • Which plugin owns the title and description, and what happens if two are active?
    • Does it change anything on its own, and where is the target post chosen?
    • Is there a record of the old value before a new one goes in?
    • How do you undo a change that went wrong, and does the undo cover the title as well as the body?
    • Does it tell you what it could not check, or does it return a clean score?

    Which Check Are You Actually Running?

    If you need to knowThe evidenceNext action
    Whether the post is set up wellStored and served title, description, H1 and alt, side by sideFix the gaps in the order below
    Whether the whole site has the same gapA crawl across every pageRead the technical SEO audit approach, then batch the fix
    Whether a page is reachable at allSitemap and internal links, not on-page fieldsSee the sitemap audit and the orphan pages post
    Whether AI answer engines can use the pageStructured data and clear, quotable textSee AI search optimization guidance

    Fixing Findings In The Right Order

    OrderFixWhy here
    1Take a restore pointEverything after this changes the post
    2Resolve the H1 questionA human decision, and it changes what Google may treat as the main title
    3TitleHighest-visibility field, but only one of several inputs
    4DescriptionA pitch Google may or may not use
    5Alt text on meaningful imagesFix real gaps, leave decorative images empty on purpose
    6Internal linksAdded by hand, where they help a reader
    7SchemaLast, and only if none exists yet

    Two rules hold for every row. Take the restore point first. Re-read the live page after each change, because a cache can show the old version for a while.

    A write that you cannot undo is a different kind of risk. Our post on what a rollback actually reverses is a good test of any undo claim. And before an agent gets write access to a site at all, the WordPress MCP ability list shows how to sort what it can do by what you would let it do unattended.

    A Five-Post Audit You Can Do This Week

    Take five published posts, ideally the ones that earn the most traffic. For each, record:

    1. The served title and its length.
    2. The served description and its length, or “missing”.
    3. The H1 count on the live page.
    4. Images without alt, split into meaningful and decorative.
    5. The number of internal links, and whether any point to a post that no longer exists.

    Then pick one outcome per post: fix it now, test it on a staging copy first, hand it to the person who owns the content, leave it as is with a note, or defer it until the plugin question is settled.

    If a post fails three of the five, start there. A fixed list of steps is easier to repeat than a clever one, which is the argument in our piece on writing the update process down before it runs.

    Why On-Page Fields Go Stale

    Plugins get swapped, themes change and titles get rewritten by someone else. A title that was right in March can be wrong in October. A theme update can add a second H1. A plugin swap can leave the description in a field the new plugin does not read, and a cache can keep serving the old page. Nothing in the editor will tell you any of that. Run the five-post audit again after any theme or SEO plugin change.

    Two Outside Views

    A tutorial and a forum thread. Neither is an endorsement.

    Technical Bro’s WordPress SEO course is a Rank Math tutorial. By its own description it covers the SEO title and meta description, heading structure, image alt text, internal linking and schema, which are the six things this checklist reads. The description also says that following a checklist does not guarantee first-page rankings.

    A WordPress SEO tutorial built on Rank Math, covering title, meta description, headings, alt text, internal links and schema.

    Technical Bro, “Wordpress SEO full course 2026 | How to Rank Website on Google First Page | Rank Math SEO Tutorial” on YouTube, 27 Sep 2026

    On Reddit, an r/Wordpress thread describes a company site running two SEO plugins, Rank Math and All in One SEO, and the poster asks what to check before removing one. That is step 2 of the playbook as a real question: which plugin owns the title and description.

    “…is there anything I need to consider when deactivating one of the plugins?”

    r/Wordpress, “Company Site has 2 SEO Plugins, Need to Remove One.”, October 2026

    Where Protuno Fits

    In the Protuno dashboard, the SEO agent is Iris, and this playbook’s category is SEO. It is a Beta playbook that can change a site, so it needs the Protuno plugin on the site first. It works on one post you name, shows its proposed changes as a diff, snapshots before it writes, and reads everything back.

    It does not choose the post, and it does not replace judgement on headings and links.

    Sources And Further Reading

    The Point

    A score says how a post looked in the editor. A checklist says what the page serves.

    Run the checks in order, change one thing at a time, and keep the old value.

    Which of your five best posts has never had its served title and description read side by side?

  • WordPress Staging Site: What Drifts From Live

    WordPress Staging Site: What Drifts From Live

    The update passed on staging. You pushed it to live. Live broke.

    Nobody did anything wrong in the update itself. The test was honest. It was just run against a site that had quietly stopped being a copy of the one that matters.

    That gap has a name worth using with clients: drift. A WordPress staging site and its live twin start identical on the day the clone is made, and then they separate, one small change at a time, until the test tells you about a site that no longer exists.

    Short answer: a staging site is only as useful as the distance between it and live, and that distance is measurable. Before you trust a staging test, compare six things: plugin and theme versions, database content, settings rows, the search engine visibility flag, cron, and the caching and CDN layer. If any of them differ in a way that touches the change you are testing, the test proved less than you think.

    What this post is, and is not: this is a comparison routine you can run yourself on two sites you control, from outside and from inside. It is not a claim that a matched staging site makes an update safe, and it is not a review of any specific host’s staging feature. Hosts implement staging differently, so confirm how your own host’s push behaves before you rely on it.

    A side by side comparison of a live WordPress site and its staging copy, with three rows highlighted where the two no longer match.
    The clone was identical on day one. This is day ninety.

    Why A Matching Staging Site Stops Matching

    Nobody decides to let staging drift. It happens because the two sites are used by different people for different reasons.

    Live gets content. Orders, posts, form entries, new users, a plugin the client installed after seeing it recommended somewhere. Staging gets experiments. A theme tweak nobody reverted, a plugin activated to test one thing six weeks ago, a constant added to wp-config.php during a debugging session.

    Both sites are being maintained honestly. They are just being maintained in different directions.

    The failure this produces is specific and it is the worst kind: a false pass. A failed staging test is useful, because you learn something before the client does. A passed staging test on a drifted site teaches you nothing and feels like proof. You then push to live with the confidence of someone who tested, which is exactly the confidence that skips the backup step.

    That is why drift belongs in the same conversation as the update process written out before it runs. A pre-flight that includes “did staging actually match” is a different pre-flight from one that only asks “did staging pass”.

    Why Core Version Drift Is Worse This Month

    WordPress 7.1.3 shipped on 6 October 2026 as a maintenance and security release, with 7 security fixes and 4 bug fixes. The announcement recommends updating immediately.

    Live sites that take a release like that quickly move to a new core version. A staging copy cloned last month does not move with them. It sits on the old core until somebody remembers it exists.

    So the first drift of the season is the boring one: live runs the patched core and staging runs the one before it. Any test you run on staging now is a test of a version your live site has already left. The plugin updates you queue up next are tested against the wrong foundation.

    The Six Things That Drift First

    Across sites, the same six categories separate before anything else does. They are listed here in the order you should check them, which is roughly the order of how often they bite.

    #What driftsHow it usually happensWhat it costs you
    1Plugin and theme versionsLive gets updates, staging does not, or the reverseYou test against code the live site is not running
    2Database contentLive keeps collecting orders, posts, users and form entriesQueries behave differently at a different row count
    3Settings rowsA plugin reconfigured on one site only, usually during debuggingThe feature you tested is configured differently on live
    4Search engine visibility flagThe clone discourages search engines, and a push carries it backLive goes no-index without anyone noticing
    5CronStaging cron is disabled to stop duplicate emailsScheduled work passes on staging because it never ran
    6Caching and CDNStaging has no page cache and no CDN in front of itNothing you measured about speed transfers to live

    Four and six deserve a sentence more than the table gives them. Cron, row five, is the other quiet one, and it gets its own check further down.

    The visibility flag is the one that turns a maintenance task into an SEO incident. Most staging clones are deliberately set to discourage search engines, which is correct for staging. The danger is the direction of travel: if a full database push moves that option row back to live, the live site is now asking not to be indexed, and nothing on the front end looks wrong. What that setting actually does, and what it does not do, is covered in the robots.txt myth. Read that before you decide how worried to be.

    Caching is the one people misread. A staging site usually runs with the page cache off and no CDN pointed at it, which makes it a reasonable place to test functionality and a poor place to test anything about speed or headers. If your test involved a page loading faster, you measured a site with a different delivery layer. The WordPress page cache header lies explains why the header you would check to confirm this is itself not trustworthy on its own.

    One small setting helps with all six, and it is easy to skip. WordPress lets a site declare an environment type: local, development, staging or production. A site that never sets it is treated as production. If staging and live each declare what they are, plugins and hosts have something honest to read, and you have a one-line fact to compare.

    Diagram of the six categories that drift first between a WordPress live site and its staging copy, with the visibility flag and cron rows flagged.
    Two of the six fail silently. Those are the two to check first.

    Comparing The Two Sites From Outside

    Start outside, because it needs no access and it catches the loudest differences in a couple of minutes.

    Request the same path on both hostnames and compare the responses. You are looking for four things:

    1. The HTTP status and the final URL after redirects. A staging site that redirects somewhere unexpected is telling you its site URL rows are wrong.
    2. The X-Robots-Tag response header, and the robots meta tag in the HTML, on both.
    3. Any cache or CDN headers present on live and absent on staging, or the reverse.
    4. The generator tag and any versioned asset URLs, which give you a rough read on whether core and plugin versions line up.

    Then fetch /robots.txt on both and read them side by side rather than skimming.

    curl -sI https://example.com/ | grep -i -E "^(HTTP|location|x-robots-tag|cache-control|age|cf-cache-status|x-cache)"
    curl -sI https://staging.example.com/ | grep -i -E "^(HTTP|location|x-robots-tag|cache-control|age|cf-cache-status|x-cache)"

    This outside pass will not tell you about settings rows or database size. It will tell you within minutes whether the two sites disagree about what they are, which is the category of drift most likely to cause a visible incident.

    Comparing The Two Sites From Inside

    The inside pass is where the real distance shows up. On both sites, record the same short list, then diff it:

    • WordPress core version.
    • Every installed plugin, its version, and whether it is active. Inactive but installed counts.
    • Every installed theme and which one is active.
    • The values of blog_public, home, and siteurl.
    • The row count of your largest content tables, and the total number of rows in the options table.
    • Whether DISABLE_WP_CRON is defined, and when the next scheduled event is due.
    • The environment type each site declares, and any constants in wp-config.php that exist on one site and not the other.

    Two of these are easy to get wrong. Inactive plugins matter because a push can activate them and because they still receive updates. And the options table is worth counting rather than eyeballing: the autoloaded portion of it behaves differently at different sizes, and the autoload query everyone is running covers how to measure it properly.

    Cron deserves its own check rather than a line in a list. A staging site with cron disabled will pass a test of anything scheduled, because nothing scheduled ran. You did not test the feature. You tested that the feature did not crash while sitting still. The failure that never alerts you is the same failure mode on live, which is a useful reminder that this is not a staging-only problem.

    One more inside check is worth the minute it takes: the PHP version. Staging and live on the same host usually match, but not always, and a staging environment left on an older branch will accept code that live rejects outright. The WordPress PHP version problem is the longer argument for treating this as a scheduled concern rather than an occasional one.

    What A Push Overwrites

    Before you push staging to live, the question to answer is not “is the code ready”. It is “what on live is about to be replaced”.

    A files push, a database push and a combined push each replace something different. The database push is the one that ends careers, because live kept collecting real work while staging sat still, and a full database push replaces that work instead of merging it. It also carries the options table, which is how a staging no-index flag reaches a production site.

    Two rules make this survivable. Take a restore point immediately before the push and confirm it is real, which is the whole argument of verifying a WordPress backup. And know in advance what a rollback can and cannot reverse, as set out in what an automatic rollback can undo and what it destroys.

    After the push, re-check the same six categories against live. Re-check the visibility flag and cron first, because those are the two that fail silently.

    A 2026 guide to creating a WordPress staging site, in about three minutes.

    Robbie’s Tutorials, “How to Create a WordPress Staging Site [2026 Full Guide]” on YouTube, 25 Jun 2026

    Has a migration or update ever gone wrong on a live site? What happened?

    r/Wordpress, “How do you handle moving WordPress sites between local/staging/production?”, August 2026

    Both are about getting a staging copy right. The video covers setting one up. The thread is a working question about moving sites between local, staging and production, and the line quoted above is the one this post answers: what goes wrong, and how you would have known.

    What Comparing Staging To Live Does Not Solve

    A matched staging site is a better test. It is not a safe one.

    Even with zero drift across all six categories, a staging test cannot tell you whether:

    • the update behaves the same under real traffic, because staging has none;
    • a third party integration will respond, since most are pointed at test credentials or nothing at all;
    • an email actually sends, because staging usually has outbound mail suppressed on purpose;
    • a payment path completes, for the same reason;
    • a scheduled job runs correctly over days rather than in a single manual trigger;
    • the CDN in front of live will serve the new asset, since staging is not behind it; or
    • the change interacts badly with data volumes that only exist on live.

    None of that is an argument against staging. It is an argument against reading a staging pass as a guarantee. The honest sentence to put in a client report is the same one that belongs in any check: what was tested, on what, and what was not assessed.

    There is also a drift you cannot close by matching. A staging site matched to live on Monday has drifted again by Friday, because live kept working. A comparison is a snapshot, so the useful question is not whether staging matched, but when you last checked that it did.

    Sources And Further Reading

    Which Of Your Staging Sites Is Still A Copy?

    If you run twenty sites, you probably have twenty staging environments, and you almost certainly do not know which ones still resemble the sites they were cloned from.

    Pick five. Run the outside pass, then the inside pass. Record the drift age, the version differences, the visibility flag, and the cron state for each pair.

    So: on the last update you pushed from staging, could you have said, with evidence, how far that staging site had drifted from live before you trusted the test?

  • WordPress User Roles: Who Really Has The Keys

    WordPress User Roles: Who Really Has The Keys

    Every WordPress site has an account nobody remembers creating.

    It might belong to a freelancer from two years ago, a plugin vendor’s support login, or a colleague who has since left. It still works. It is still an Administrator.

    The password is only half the problem. The bigger question is how many people can change your site today, and whether you could name every one of them.

    Short answer: To audit WordPress user roles, open the Users screen, filter by role, and count the Administrators. Each one can install plugins, edit code and create more users. Any Administrator with no named owner and no clear reason to exist is the first account to question. Then check whether anyone has a role above their job, and whether any login is shared.

    What this post is, and is not: A read-only audit of WordPress user roles, for people who look after several WordPress sites. The role descriptions follow how WordPress core documents its default roles. Nothing here is a result from a real client site, and it does not replace a full security audit.

    An Administrator is not a job title. It is a list of everything someone can break.

    Illustration of the five default WordPress user roles as a ladder, from Subscriber at the bottom to Administrator at the top
    The higher the role, the more a single stolen password can change.

    WordPress User Roles: What Each Default Role Can Do

    A single WordPress site ships with five roles. They are ordered by how much damage one stolen login can do.

    RoleWhat it can doWhat it should be used for
    AdministratorEverything on the site: install and delete plugins and themes, add and remove users, change any setting, and edit theme and plugin files unless file editing is switched offThe few people who run the site
    EditorPublish and edit all posts and pages, including other people’s, and moderate comments. No plugin, theme or user controlContent managers
    AuthorPublish and edit their own posts, and upload filesRegular writers
    ContributorWrite and edit their own posts, but not publish them or upload filesGuest writers
    SubscriberRead, and edit their own profileMembers, customers, commenters

    For a short overview of the defaults, there is a recent video, WordPress User Roles Explained (2026), from VIS Mountain Marketing & Advertising. Its description says it is narrated with an AI voice and shows simplified diagrams, not live screenshots, so use it as a refresher and check the official documentation for detail.

    What each WordPress role can really do, which one to give each kind of person, and how to change someone’s role in under a minute.

    VIS Mountain Marketing & Advertising, “WordPress User Roles Explained (2026): Which Role to Give Each Person + How to Change It” on YouTube, 6 Oct 2026

    Two things change this picture.

    First, plugins add roles and change what the default ones can do. A store plugin adds a Shop Manager. A membership plugin adds its own. These roles can carry real power, and they rarely stand out in a quick look at the Users screen.

    Second, a multisite network has a Super Administrator above every site. That one account controls the whole network, not a single site.

    Of all the WordPress user roles, one matters most for an audit. Administrator decides who can change everything else.

    Listing Every Account From Outside And Inside

    You can see your accounts and their WordPress user roles from two places, and the two lists do not match.

    From inside, the Users screen or the command line shows every account, its role and when it registered. From outside, you only see what the site chooses to reveal. By default, a WordPress site can reveal usernames through public routes. We covered all three of them, and how to close them, in WordPress user enumeration is still on by default, so this post does not repeat that.

    What matters here is the gap between the two lists.

    ViewWhat it tells youWhat it cannot prove alone
    Inside, Users screenEvery account and its roleWhether anyone still uses it
    Inside, command lineThe same list, in a form you can save and compare next monthWho the person behind a login really is
    Outside, public routesWhich usernames a stranger can findWhich of them are Administrators
    Illustration comparing the account list seen from inside WordPress with the shorter list visible from outside, with the gap highlighted
    An account that only shows up on one side is a question worth asking.

    A small audit you can run today:

    • Count the accounts in each role on the Users screen.
    • Save the Administrator list with name, email and registered date.
    • Write an owner and a reason beside every Administrator.
    • Mark every account you cannot explain.

    With command-line access, these two commands cover the first steps:

    wp role list
    wp user list --role=administrator --fields=ID,user_login,user_email,user_registered

    The registered date is the cheapest clue you have. An old account with no known owner is the first one to question.

    One more caution. Code that runs inside WordPress can change what WordPress shows you. The r/Wordpress write-up linked below describes malware that kept a list of administrator accounts to hide, so a Users screen can look clean when it is not. If you suspect a problem, ask the database directly. This query lists every account with the Administrator role, and you should change each wp_ to your own table prefix:

    wp db query "SELECT u.ID, u.user_login, u.user_email, u.user_registered FROM wp_users u JOIN wp_usermeta m ON m.user_id = u.ID WHERE m.meta_key = 'wp_capabilities' AND m.meta_value LIKE '%administrator%'"

    If that list is longer than the Users screen, treat it as an incident and not a tidy-up.

    A 34-second walk-through of the audit. All scenes are illustrations with example accounts.

    The Three Accounts To Question First

    An audit of WordPress user roles does not need to be long. Three kinds of account cover most of the risk.

    1. Administrators nobody can name. If no one on your team can say who it belongs to and why it exists, treat it as a finding. A forgotten Administrator is an unlocked door that nobody knows about.

    2. Accounts with a role above their job. A writer who publishes their own posts needs Author, not Editor. A client who updates one page needs Editor at most. Ask whether the person could do their job one role lower. Agencies argue about whether a client should get Administrator all the time, and the least-privilege answer is almost always no.

    3. Shared logins. One account used by three people cannot be traced to any of them. When something changes, nobody can say who did it. Give each person their own account, then remove the shared one.

    One r/Wordpress thread, “Found a WordPress malware using __GA_INJ_START__ and hidden admin accounts — full incident analysis”, is a write-up of a hacked site where the attacker kept hidden administrator accounts. The author describes how the malicious code worked:

    “The malicious code maintained a list of administrator accounts that should be hidden.”

    r/Wordpress, “Found a WordPress malware using __GA_INJ_START__ and hidden admin accounts — full incident analysis”, August 2026

    What Changing A Role Breaks

    Removing access is easy to say and harder to do. A role change can stop things that quietly depend on it.

    Check these before you demote an account:

    • Scheduled work. Does a plugin run jobs as that user?
    • Authorship. Posts belong to the account. Deleting the user forces a choice about where the content goes, while demoting does not.
    • Integrations. An automation tool or API may sign in with that login.
    • Backups and updates. Some tools act as a named Administrator.

    The safe order is short. Demote first, and do not delete. Watch the site for a few days. Delete only when nothing has broken.

    Take a restore point before changing roles on a real site. If something does break, a rollback is only as good as what it can actually undo, so find that out before you need it.

    Checking It On A Schedule

    A WordPress user roles audit done once goes stale. People join, leave and change jobs, and plugins add roles.

    Keep the software current as well. WordPress 7.1.3 was released on 6 October 2026 as a maintenance and security release, and the announcement recommends updating immediately. A tidy account list says nothing about the code that guards it.

    A monthly pass is enough for most sites. Compare this month’s Administrator list with last month’s. Anything new needs an owner and a reason. Anything missing should be a change you expected.

    For agencies, this belongs in the client report as one short line: how many Administrators, and whether each one is accounted for. We wrote about what goes into a client report and what stays out. An Administrator list is a good example of a short finding that earns its place.

    A role review also fits inside a wider WordPress security audit, next to the basics in WordPress hardening.

    What This Does Not Solve

    An audit of WordPress user roles is a view of access, and it has limits.

    • It does not tell you a password is strong. A well-named account with a weak password is still a weak account.
    • It does not show activity. Core WordPress does not record who logged in or what they changed. You need an activity log for that.
    • It does not see plugin roles in full. Some plugins grant power through their own settings, not through the role name.
    • It does not see an account that hides itself. The Users screen is only as honest as the code running behind it. Compare it with a direct database query when something feels off.
    • It does not catch an account that was created and removed. If someone added an Administrator, did their work and deleted it, the list looks clean.
    • It does not cover access outside WordPress. Hosting panels, SFTP, database users and DNS each have their own accounts.
    • It does not cover access given to software. Connecting an AI tool or an automation is another kind of access and needs its own questions. We listed them in AI agent permissions on WordPress.

    A clean list from a check that skipped half these places is worse than an honest “I reviewed WordPress users only.” Say which places you covered.

    A Five-Site Audit You Can Do This Week

    Pick five sites you look after. For each one, write down:

    • The count of accounts in each role.
    • Every Administrator, with a name, an owner and a reason.
    • Any account that has not logged in for a long time, if you can tell.
    • Any account with a role above the person’s job.
    • Any shared login.

    Then choose one outcome for every account you questioned:

    1. Keep it, with an owner and a review date.
    2. Demote it one role.
    3. Test the change on a copy first, then demote.
    4. Replace a shared login with named accounts.
    5. Remove it, after a demotion period with nothing broken.
    6. Investigate it, if nobody can explain it.

    Investigate first. An Administrator nobody can explain decides whether this was a tidy-up or an incident.

    Sources And Further Reading

    The Point

    WordPress user roles are a list of who can change your site. Most sites hold more of that power than anyone has written down.

    You do not need a tool to start. You need an hour and a list.

    How many Administrators does your busiest client site have, and could you name every one of them?

  • WordPress Hacked: The First Hour, In Order

    WordPress Hacked: The First Hour, In Order

    The worst moment of a hacked site is not the discovery. It is the next ten minutes.

    You open the dashboard, you start deleting things, you reset one password, you restore a backup. Every one of those moves feels like progress. Several of them destroy the evidence you need, or lock the door while the intruder is still inside.

    Short answer: When a WordPress hacked site lands on your desk, do the first hour in this order. Write down what you see. Copy the site as it is. Cut off access, including the access that sits above WordPress. Check the backup before you trust it. Clean, update, and rotate passwords again once the site is clean. Only then ask how they got in. The order matters more than any single tool.

    What this post is, and is not: A practical response checklist for people who run or look after WordPress sites. It draws on the official WordPress.org guide to a hacked site. The order of the seven moves, and the reasons for it, are ours. It is not a malware removal service, not legal advice, and not a result from a real incident. If the site holds customer payment data or personal data, tell your host and take professional help early.

    A scan tells you what is wrong. A response tells you what to do first.

    Illustration of the seven steps in the first hour after a WordPress site is hacked: record, copy, lock access, check the backup, clean, rotate passwords again and find the cause
    Seven moves, in this order. Skipping ahead is how sites get hacked twice.

    Why Panic Cleaning Makes It Worse

    The urge is to fix what you can see. A strange admin user, a defaced page, a spam redirect. You remove it and the symptom goes away.

    That tells you very little. A visible symptom is often the last thing an intruder did, not the first. The way in is usually still open, and a copy of the way back in may already be sitting in a file you have not looked at.

    The WordPress.org guide opens with a plain instruction: stay calm, then document. It says a hack is an ambiguous word that tells you little about what happened, so the symptoms you can name are the thing to write down first.

    Panic cleaning has three common results:

    • Evidence is lost. If you delete before you copy, you cannot tell afterwards what was changed.
    • The door stays open. Cleaning files without changing access lets the same account or key back in.
    • A bad backup gets restored. A copy taken after the break-in can bring the problem straight back.

    We looked at the scanning side in WordPress Malware Scan. A scan answers “what is on this site”. This post answers the question that comes before and after it: what do I do, and in what order.

    Seven Moves For A WordPress Hacked Site

    #MoveWhy it comes here
    1Write down what you seeIt is the only record of what the site looked like before you touched it
    2Copy the site as it isYou need the evidence, and a safety net if the cleanup goes wrong
    3Lock accessStops new changes while you work
    4Check the backupA restore is only safe if the copy is older than the break-in
    5CleanRemove the cause, not just the symptom
    6Update and rotate againFixes the known weakness and replaces anything the intruder saw
    7Find how they got inWithout it, the same hole is still there

    Each move gets its own section below.

    Move One: Write It Down Before You Touch Anything

    Open a note and write four things. It takes five minutes and it is the most useful five minutes of the hour.

    • What you are seeing that tells you the site is hacked.
    • When you noticed it, with the time zone.
    • What changed recently: a new plugin, a theme edit, a new user, a host move.
    • Where the site is hosted, and who else has access.

    The WordPress.org guide lists the kind of symptoms that count as clear signs: the site is blocked by a search engine, the host has disabled it, it is flagged for distributing malware, visitors report their antivirus is warning them, you hear it is being used to attack other sites, or you see actions nobody authorised, such as new users.

    Write down which of those you actually saw. “It looks hacked” is not a symptom. “A new administrator account appeared on Tuesday” is.

    Move Two: Copy The Site As It Is

    Before you clean, take a full copy of the files and the database. Keep it somewhere that is not the same server.

    This copy is not a backup you plan to restore. It is evidence. If the cleanup breaks something, you can go back. If you later need to work out how the intruder got in, you have something to read.

    The same WordPress.org guide makes the point that even an infected copy is worth keeping. It recommends one more snapshot of the environment before the cleaning starts.

    Ask your host for logs while you are at it. Many hosts keep very little for very long, so ask early. We cannot say what yours keeps. The point is that a log you did not ask for in time is a log you will not have.

    Move Three: Lock Access, Including The Part Above WordPress

    Locking access means more than changing the admin password.

    Think of access in three layers:

    LayerExamplesOften missed because
    WordPressAdmin and editor accounts, application passwordsIt is the layer everyone remembers
    HostingControl panel, SFTP, SSH keys, database userIt sits above WordPress and plugins cannot see it
    PeopleLaptops, saved FTP passwords, shared loginsThe weak point is a machine, not the site

    For WordPress itself, the official guide suggests forcing a password reset for all users, especially administrators, and changing the secret keys in wp-config.php. Changing the keys logs everyone out, including a session the intruder may still be holding.

    For hosting, change the SFTP, control panel and database passwords, and remove any key or user you do not recognise. If you cannot name an account, treat it as a finding.

    For people, the guide recommends scanning your own computer too. In many cases the infection starts on a local machine that captured a login.

    If you cannot log in at all, the guide describes a way back through the database tools your host provides, by resetting the user record directly. That is a task for someone comfortable in the database.

    We looked at how accounts and routes get exposed in WordPress user enumeration. It is a useful read for the question “which names can an outsider see”.

    Move Four: Check The Backup Before You Trust It

    Restoring a backup feels like the safest move. It is only safe if the backup is older than the break-in.

    An intruder may have been inside for days before anything visible happened. A backup taken last night can contain exactly what you are trying to remove. The WordPress.org guide notes that you can restore a backup and move straight into the investigation, which is the careful way to read it: restore to look, not to relax.

    Three questions to ask of every backup:

    • When was it taken, compared with the first sign of trouble? Use your notes from move one.
    • Where is it stored? A backup on the same server may have been reached too.
    • Has it ever been restored on a test copy? If not, it is a file with a hopeful name. We wrote about that in verifying a WordPress backup.
    Illustration of a timeline showing that a backup taken before the first sign of the break-in is safer to restore than one taken after it
    A backup is only as clean as the day it was taken.

    Move Five: Clean The Cause, Not The Symptom

    Cleaning means replacing, not patching. The guide’s approach is practical and worth following closely.

    • Core. The folders wp-admin and wp-includes can be replaced safely with a fresh copy of the same WordPress version. The guide suggests using SFTP to upload them rather than the dashboard reinstall, because the dashboard installer tends to overwrite existing files and intruders add new ones.
    • Plugins and themes. Reinstall them from their original source. A modified file that looks normal is the whole point of a backdoor.
    • The .htaccess file. The guide calls it one of the most commonly modified files, whatever the type of infection, and notes it may sit in more than one folder.
    • Files that load on every request. index.php, header.php, footer.php and functions.php are named in the guide because a change there affects every page.
    • Users and the database. Check administrator accounts and look for anything you did not create.

    Deactivating is not removing. A file that runs when someone requests its address does not care whether the plugin around it is switched on. Delete what should not be there.

    The official guide calls finding and removing the hack the most daunting part of the whole process, and it gives no single method, because the right steps depend on the symptoms and on your own technical skill. If you are not sure, a professional clean is cheaper than a second hack.

    One practical walk-through is Ferdy Korpershoek’s video, WordPress Getting Hacked? Here’s What To Do Now, which shows a real hacked website being scanned and cleaned. The description says it uses the MalCare plugin and discloses an affiliate link, so read it as one practitioner’s method, not as a recommendation from us.

    I’ll even show you a REAL hacked website, how malware was detected, and how we removed it in just a few clicks.

    Ferdy Korpershoek, “WordPress Getting Hacked? Here’s What To Do Now” on YouTube, 18 May 2026

    Move Six: Update, Then Change The Passwords Again

    Once the site is clean, update WordPress, plugins and themes to the latest versions. The guide says older versions are more prone to being hacked, and that is where many incidents start.

    A timely example. WordPress 7.1.3 was released on 6 October 2026 as a maintenance and security release. The announcement lists seven security fixes and four bug fixes, and says that because it is a security release, updating immediately is recommended. We cannot say whether any particular hack used any of those issues, and this post does not claim that. The practical point is smaller: if your site is behind on core updates, that is the first thing to fix.

    Then change the passwords a second time. The guide is explicit about this. If you changed them when you found the hack and the intruder was still inside, the new passwords may have been seen. Change them again after the site is clean, and consider changing the database user and password as well.

    Two things are worth turning on at this point: a second factor on logins, and a short list of who has access at all. We looked at what happens when a vulnerable plugin goes unnoticed in WordPress vulnerability scanner design and at forgotten plugins in removed plugins.

    A 34-second walk-through of the seven moves. All scenes are illustrations, not a real incident.

    Move Seven: Find Out How They Got In

    This is the step that gets skipped, because the site looks fine again.

    The WordPress.org guide calls it forensics: understanding what happened and how the attacker got in, so it cannot be used again. It admits that is hard for most site owners because of missing data and technical depth.

    You can still narrow it down with what you already wrote and copied:

    • Compare the date you first saw a problem with the dates of your last plugin and theme changes.
    • Look at the accounts that were added, and when.
    • Check whether any plugin or theme was out of date, abandoned or removed from the repository.
    • Ask whether the PHP version was supported. See the WordPress PHP version problem.
    • Ask the host what they saw on their side.

    If you cannot find the cause, say so in your notes. “Unknown, access rotated, monitoring added” is an honest record. A made-up cause is worse than none.

    A site that comes back dirty is exactly what this step is for. One r/Wordpress thread, “How to fix wordpress hacked website? Can anyone guide step by step.”, starts from a site owner whose developer cleaned the site and saw the files return. Without knowing how the intruder got in, a clean-up can only hope the same door stays shut.

    “I got that checked by developee and he cleaned it but everything came back.”

    r/Wordpress, “How to fix wordpress hacked website? Can anyone guide step by step.”, October 2026

    Blacklists And Search Console Warnings

    Search engines and antivirus tools may flag a hacked site. The guide recommends registering the site with the webmaster consoles so you hear about it from them. Google Search Console also has a Manual actions report. If Google has issued a manual action against the site, you fix every affected page and then select Request Review in that report, describing what you fixed. Check the report for the exact wording that applies to your case.

    Treat that as a signal, not as proof. Not seeing a warning does not mean the site is clean, and seeing one does not tell you what is wrong. Check the site, then check the report.

    What This Does Not Solve

    A first-hour order is a way to stop making it worse. It does not make a hack impossible.

    • It does not tell you how you were hacked. Move seven narrows it down. It does not prove it.
    • It does not guarantee a clean site. Intruders can plant more than one way back in. A single clean scan is not the end.
    • It does not replace professional help. Customer data, payment data and legal duties need someone qualified.
    • It does not prevent the next one. Prevention is a different job. We measured common hardening advice in WordPress hardening.
    • It is not a result from a real incident. Nothing in this post comes from a site we cleaned.

    A response checklist is for the day it happens. A monitoring habit is for the days before it. Our write-up of WordPress security monitoring covers the second one.

    A Five-Site Check You Can Do This Week

    You do not need a hack to practise. Pick five sites you look after and answer these for each:

    1. Where would you write down what you see, and who gets the note?
    2. Can you take a full copy of files and database in under an hour?
    3. Who holds hosting, SFTP and database access, and when were those passwords last changed?
    4. Has your newest backup ever been restored on a test copy?
    5. Is the site on the latest WordPress version, with a supported PHP version?

    Then pick one outcome per site: fix it now, test it first, hand it to someone who owns it, or accept the gap with an owner and a date.

    If a site fails three of the five, start with that one. Our piece on the client report is a useful reminder of how to tell a client what you found, in the order they need it.

    Sources And Further Reading

    The Point

    A hacked site is two jobs: stop it, then understand it.

    The first hour is about doing them in that order.

    Which of your sites has no written answer to “who has access, and when did we last change it”?

  • WordPress Spam Comments: The Playbook, Step By Step

    WordPress Spam Comments: The Playbook, Step By Step

    Most spam cleanup is a button labelled Empty Spam. The button never asks which of those comments were real.

    A spam folder is a pile of guesses. Most are right. A few are a customer asking a question, and once the folder is emptied nobody can tell which few.

    Short answer: safe WordPress spam comment cleanup needs a second signal beyond the spam label, a rule that stops the whole job when the numbers look wrong, and a way back. The Protuno Spam Comment Deleter playbook does this in four steps. It moves only the comments that carry two signals to the trash, it never permanently removes anything, and it checks afterwards that the comments you wanted to keep did not move.

    What this post is, and is not: it is a practical walk through one playbook and the reasoning behind its order. It describes how the check works from the playbook’s own step files. It does not quote a run, a count or a result, because this post is written without running the playbook.

    An empty folder is a fact about a button. A clean comment section is a fact about every comment you kept.

    Four steps of the Spam Comment Deleter playbook, from baseline and stop rule to a verified report

    Why Emptying The Spam Folder Falls Short

    WordPress gives every comment one status: approved, held for moderation, spam or trash. That status is a single label, set by whatever last touched the comment. A spam filter set it. A person set it. A plugin that misfired set it.

    Emptying the folder trusts that label completely. If the label is wrong on one comment, the comment is gone. There is no second look, because the button was built for speed.

    The opposite habit is just as common. The folder is never emptied, so spam that was caught and never cleared sits in the database indefinitely, and the comment tables grow for years. Nobody wants to be the person who clicks the button, so nobody does.

    Both habits come from the same gap. There is no step between “flagged” and “gone” that checks the flag.

    That gap is the interesting part of this playbook. It is also why the job is a poor fit for a blind schedule and a good fit for a written sequence.

    Three Signals On One Comment

    The playbook decides what is safe to move by looking at each spam comment in three ways. Any one of them alone is weak.

    SignalWhat it tells youWhat it cannot prove alone
    Comment status is spamSomething classed it as spamThat the classifier was right
    Akismet result on the commentA detector independently said true (or 1)That the comment has been there long enough to be settled
    Age of the commentIt is older than a minimum (10 minutes by default)That it is spam at all

    The rule that follows from the table is short. A comment is eligible only when it is already spam, a detector has confirmed it, and it is not brand new. The playbook calls that the dual-signal rule.

    Two cases matter more than the rest. An Akismet result that is explicitly false means the detector said this is not spam, so the comment is never eligible. A comment with no Akismet data at all has no second signal, so it is not eligible either, and the playbook will not call it confirmed spam.

    Three signals compared: spam status, Akismet confirmation and age, with the combinations that qualify

    A Small Test You Can Run Today

    You can see the shape of your own problem in about ten minutes, with nothing installed.

    Write down five things for one site:

    • How many comments are approved, held for moderation, in spam and in trash.
    • Whether Akismet is installed and active.
    • Whether the trash is switched on, meaning a retention period is set rather than zero.
    • The oldest comment in the spam folder.
    • Any spam comment you recognise as a real person.

    Here are the places to look:

    /wp-admin/edit-comments.php?comment_status=spam
    /wp-admin/edit-comments.php?comment_status=trash
    /wp-admin/plugins.php          (is Akismet listed and active?)
    wp-config.php                  (search for EMPTY_TRASH_DAYS)

    If you find even one real comment in the spam folder, you have your reason to read on. A cleanup that cannot tell that comment apart is a cleanup you should not schedule.

    The Playbook, Step By Step

    Spam Comment Deleter is a Protuno Care playbook. It runs a fixed sequence of four steps, and only one of them changes the site. In the dashboard it carries the CAN WRITE label. The public playbooks page lists the same four-step playbook as Comment Cleanup, described as clearing the spam that WordPress has already flagged, and nothing else. The dashboard card calls it Spam Comment Deleter, so you may see either name.

    #StepWhat it does
    1Comment Baseline And Anomaly GateReads the comment counts (approved, moderated, spam, trash), works out the spam ratio, applies the stop rule, and records the trash retention period and whether Akismet is installed. Changes nothing.
    2Build High Confidence Spam BucketSorts spam comments into buckets under the dual-signal rule: eligible, medium (spam only, never actioned) and too new (skipped). Changes nothing.
    3Trash Confirmed SpamThe only step that writes. Moves eligible comments to the trash one at a time, after a retention check and a written audit manifest.
    4Verify Spam Cleanup ReportRe-reads the counts, asserts that spam dropped by exactly the number trashed and that approved and moderated did not change, then writes the report. Changes nothing.

    The order is the safety. The counts and the stop rule come before any bucket exists. The bucket exists before anything is trashed. The check comes after, and it is the only one that can say the earlier steps did what they claimed.

    Step 1 and step 2 both use one read capability, called comments-spam-audit, to compute the counts and the buckets on the site itself. The step file explains why: an earlier version paged the comments over the REST API, which cannot see comment meta. That version got seven of nine counts wrong and planned to trash six spam comments, including one whose Akismet result was explicitly false. The fix was to stop rebuilding the numbers from REST pages.

    That is a good rule for any cleanup tool you are considering. The classification has to be read from where the signal lives.

    What The Stop Rule Is Protecting You From

    Step 1 computes one ratio: spam divided by approved plus moderated plus spam. Trash is left out on purpose, because trashed comments are spam that has already been dealt with. The default threshold is 0.6.

    Here is how that works, with made-up numbers to show the arithmetic and not a result from any site.

    IllustrationApprovedModeratedSpamRatioGate
    A normal blog30020800.20Proceed
    A broken classifier10009000.90Stop

    When the gate says stop, the playbook stops the whole job. It reports that the spam volume is anomalous, likely a misconfigured classifier, and that manual review is needed before any cleanup.

    The reasoning is sound. A huge spam share is more likely to be a classifier gone wrong than a site that is 90 percent spam. Mass-trashing it could bury the real comments. A stop here counts as a correct outcome, not a failure.

    Step 3 adds its own gate. If the trash retention period is zero or unset, moving a comment to the trash would remove it for good. The playbook refuses and says so. By default WordPress keeps trashed items for 30 days, and the playbook reads the actual value on your site rather than assuming it.

    What Spam Comment Cleanup Does Not Solve

    • It does not stop new spam. It clears comments that are already flagged. Preventing them is a different job.
    • It does not work without a detector. If Akismet is not installed, nothing can be confirmed under the dual-signal rule, so nothing is eligible. The report leads with that root cause and recommends installing and activating Akismet.
    • It does not touch the medium bucket. Spam without a second signal is reported, and the recommendation is to review it by hand in the Comments screen.
    • It does not remove anything permanently. The playbook trashes. It never deletes and never recommends emptying the trash.
    • It does not touch approved or moderated comments. Step 3 re-checks every comment right before moving it and skips anything that is not still spam.
    • It does not read intent. A comment confirmed as spam is spam by two signals. That is strong evidence, not a mind reader.

    Questions To Ask Your Current Tooling

    • Does it use a second signal before it removes anything, or only the spam label?
    • What happens to a comment with no detector data?
    • Does it stop on a strange spam ratio, or does it carry on?
    • Does it check that your trash is switched on before it trashes?
    • Does it write down what it is about to move, before it moves it?
    • Can a whole run be undone with one action?
    • After the run, does anything compare the real comments before and after?

    If the answer to most of these is “I am not sure”, the tool is a button with a schedule.

    Which Check Are You Actually Running?

    If you need to knowThe evidenceNext action
    How much spam is sitting thereCounts of approved, moderated, spam and trashBaseline step, read-only
    Whether the classifier is healthySpam ratio against a thresholdStop and review by hand if it is anomalous
    Which spam is certainSpam status plus Akismet confirmation plus ageMove that bucket to the trash
    Which spam is only probableSpam status without a second signalReview by hand in the Comments screen
    Whether the cleanup was exactSpam dropped by the trashed count, real comments unchangedRead the verification report

    Fixing Findings In The Right Order

    When a run produces buckets, the order of work matters.

    PriorityFindingWhat to do
    1The stop rule firedFind out why the spam ratio is so high before touching anything
    2Trash is disabledSwitch the retention period on first, then clean up
    3No detector installedInstall and activate Akismet, then run again
    4High-confidence bucket has entriesMove them to the trash and read the report
    5Medium bucket has entriesReview by hand, comment by comment

    Two practical rules sit under this table.

    Restore point first. Before anything that changes a site, know how you would get back. The playbook writes an audit manifest of the exact comments it plans to move, before it moves any, and a run report that can roll the run back. For the site as a whole, verify the backup as well, because a backup you have never checked is a file with a hopeful name.

    Re-check after the change. The final step exists because “it said it worked” is not evidence. Step 4 compares the before and after counts.

    A Five-Site Audit You Can Do This Week

    Pick five sites. For each one, write down:

    • Approved, moderated, spam and trash counts.
    • Whether Akismet is active.
    • Whether the trash retention period is set.
    • The age of the oldest spam comment.
    • Whether any real person is sitting in the spam folder.

    Then decide one of these for each site:

    • Fix now: the folder holds certain spam and the trash is on.
    • Test first: the ratio looks odd, so find the cause before cleaning.
    • Replace: the site has no detector, so install one.
    • Remove: a comment form nobody uses and nobody moderates.
    • Accept with an owner and a date: the spam can stay, with a named person and a review date.
    • Investigate: the spam folder contains something that looks like a real person.

    It is the same arithmetic as the rest of maintenance work. Every small chore multiplies by the number of sites, which is where the unbilled half hour comes from.

    Why Spam Cleanup Goes Stale

    A cleaned folder is a snapshot, and new spam arrives the next day. Security Monitoring has a section on why a one-off security check goes stale, and the same logic applies here. The playbook is listed as weekly on the public playbooks page for that reason.

    Where Protuno Fits

    Spam Comment Deleter sits in the Care category. It is one of the playbooks that can change a site, so it needs the Protuno plugin on the site, and only one of its four steps writes. The other three only read. The decision to run it, and what to do with the comments it leaves alone, stays with a person.

    The split between reading and acting is the point of detection being solved while deciding is not. If you want the update version of this approach, The WordPress Update Process, Written Out Before It Runs is the closest match. And before you connect any automation to a client site, read what to ask about permissions.

    If the question is how a rollback works in practice, WordPress Rollback After An Update covers it, and it names spam comments among the changes the run report can undo.

    The Point

    A spam filter decides. A cleanup should check.

    The safe version needs two signals, a stop rule, a trash that is switched on and a before and after count.

    Which of your sites would you trust to empty the spam folder tonight?